Qwen3.5-35B-A3B 吞吐量优化
结论
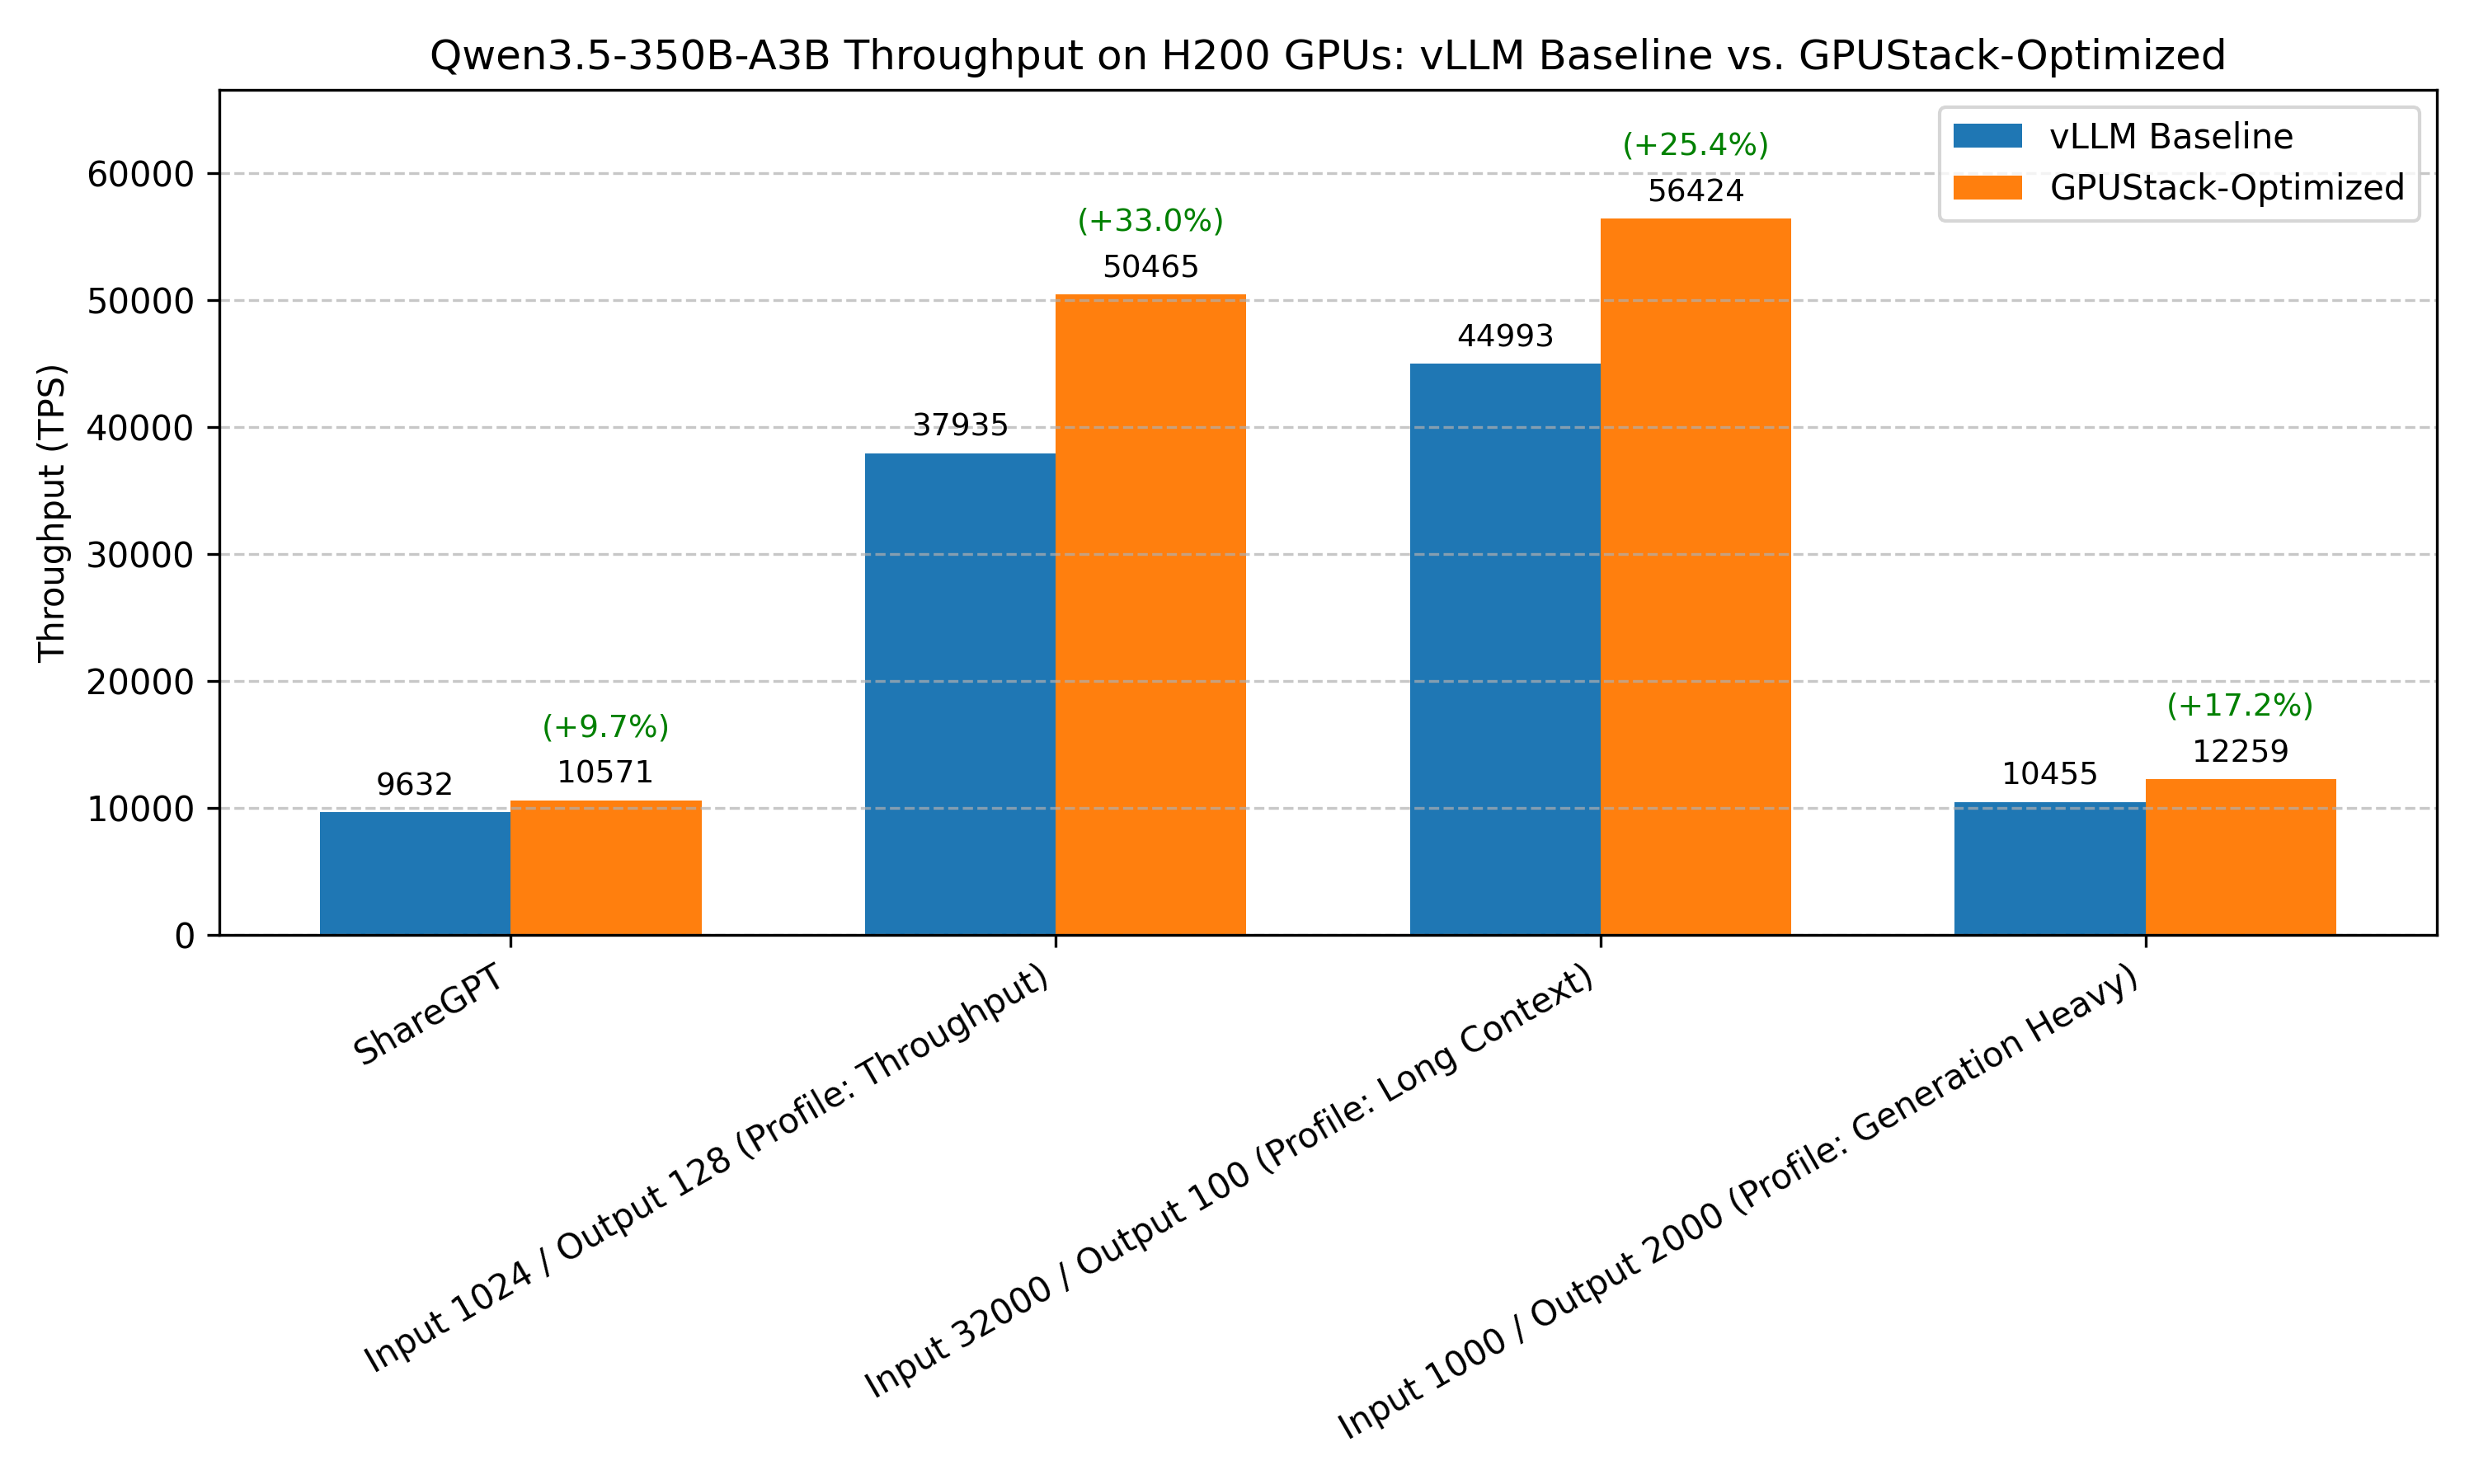
Qwen3.5-35B-A3B 在 NVIDIA H200 上的吞吐量优化推荐配置:
推理服务命令
| vllm serve Qwen/Qwen3.5-35B-A3B-FP8 \
--reasoning-parser=qwen3 \
--performance-mode=throughput \
--max-model-len=32768 \
--enable-prefix-caching
|
优化前后的基准测试结果对比:
| 基准测试用例 | 基准配置(未做任何优化的 vLLM) | 优化后 |
| ShareGPT 测试配置 | Total TPS: 9632.01
Mean TPOT(ms): 25.89 | Total TPS: 10570.88 (+9.75%)
Mean TPOT(ms): 24.71 |
| 吞吐量测试配置 | Total TPS: 37934.72
Mean TPOT(ms): 45.39 | Total TPS: 50464.84 (+33.03%)
Mean TPOT(ms): 41.12 |
| 长上下文测试配置 | Total TPS: 44993.20
Mean TPOT(ms): 319.79 | Total TPS: 56424.42 (+25.41%)
Mean TPOT(ms): 227.43 |
| 生成密集型测试配置 | Total TPS: 10455.38
Mean TPOT(ms): 2.48 | Total TPS: 12258.79 (+17.25%)
Mean TPOT(ms): 2.92 |
说明
- 基准测试未覆盖所有可能的优化组合。例如,我们会选择默认配置下表现最好的推理引擎作为后续调优的起点。这种剪枝方式得到的是局部最优解,未必是全局最优解。
- 其他优化方法取决于具体使用场景,包括最大批大小、调度配置、扩展 KV cache、CUDA graph 等。本文结论可作为进一步针对性优化的起点。
- 测试基于特定的硬件和软件环境。推理引擎的改进可能带来新的结论。
- 量化可能影响准确率,但对于大多数模型,FP8 量化的准确率下降可控制在 1% 以内。详情参见评估结果。因此,强烈建议在低延迟推理服务场景中使用 FP8 量化。
- 推测解码能够显著降低低并发请求的延迟,但加速效果取决于基准测试数据集的数据分布和草稿模型的选择。例如,本测试所选的草稿模型使用英文数据训练,在其他语言上的表现可能不够理想。
如有遗漏或需要根据最新变化更新的内容,请告诉我们。
实验环境
模型
硬件
NVIDIA H200
引擎版本
- vLLM v0.17.1
- SGLang v0.5.9
基准测试方法
本项目使用 GPUStack 的一键基准测试功能评估推理服务工作负载。本文中的基准测试均通过该流程执行。
GPUStack 的基准测试通过封装项目 benchmark-runner,基于 guidellm 实现。
对于以下基准测试配置,GPUStack 负责模型部署、基准测试任务提交和结果收集。
基准测试配置
ShareGPT
| dataset_name: ShareGPT
request_rate: 1000
total_requests: 1000
|
吞吐量
| dataset_name: Random
dataset_input_tokens: 1024
dataset_output_tokens: 128
dataset_seed: 42
request_rate: 1000
total_requests: 1000
|
长上下文
| dataset_name: Random
dataset_input_tokens: 32000
dataset_output_tokens: 100
dataset_seed: 42
request_rate: 1000
total_requests: 100
|
生成密集型
| dataset_name: Random
dataset_input_tokens: 1000
dataset_output_tokens: 2000
dataset_seed: 42
request_rate: 1000
total_requests: 200
|
开源工具替代方案
如果不使用 GPUStack,可以直接执行 guidellm benchmark 命令替代 GPUStack 基准测试流程。
对于包含 dataset_name: ShareGPT 的测试配置:
| guidellm benchmark \
--target ${target} \
--profile constant \
--rate ${request_rate} \
--max-requests ${total_requests} \
--processor ${model_path} \
--data ./ShareGPT_V3_unfiltered_cleaned_split.json
|
对于包含 dataset_name: Random 的测试配置:
| guidellm benchmark \
--target ${target} \
--profile constant \
--rate ${request_rate} \
--max-requests ${total_requests} \
--processor ${model_path} \
--data "prompt_tokens=${dataset_input_tokens},output_tokens=${dataset_output_tokens}" \
--random-seed ${dataset_seed:-42}
|
实验结果
推理引擎基准配置
vLLM
- 测试配置:
ShareGPT - 后端参数:
| --reasoning-parser=qwen3
--max-model-len=32768
|
基准测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 512
Benchmark duration (s): 70.72
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 14.14
Output token throughput (tok/s): 4347.55
Peak output token throughput (tok/s): 30810010.86
Peak concurrent requests: 512.00
Total Token throughput (tok/s): 9632.01
----------------------Latency---------------------
Mean Latency(s): 30.19
Median Latency(s): 27.48
P95 Latency(s): 60.73
P99 Latency(s): 65.37
---------------Time to First Token----------------
Mean TTFT (ms): 4072.64
Median TTFT (ms): 5786.23
P95 TTFT (ms): 9276.23
P99 TTFT (ms): 10204.44
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 25.89
Median TPOT (ms): 11.63
P95 TPOT (ms): 119.58
P99 TPOT (ms): 161.45
---------------Inter-token Latency----------------
Mean ITL (ms): 11.46
Median ITL (ms): 0.00
P95 ITL (ms): 101.72
P99 ITL (ms): 132.49
==================================================
|
SGLang
- 测试配置:
ShareGPT - 后端参数:
| --reasoning-parser=qwen3
--context-length=32768
|
基准测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 512
Benchmark duration (s): 124.99
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 8.00
Output token throughput (tok/s): 2254.86
Peak output token throughput (tok/s): 125470.63
Peak concurrent requests: 512.00
Total Token throughput (tok/s): 4995.66
----------------------Latency---------------------
Mean Latency(s): 50.86
Median Latency(s): 53.56
P95 Latency(s): 82.38
P99 Latency(s): 95.75
---------------Time to First Token----------------
Mean TTFT (ms): 34359.37
Median TTFT (ms): 44424.39
P95 TTFT (ms): 50796.35
P99 TTFT (ms): 53280.79
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 180.73
Median TPOT (ms): 145.27
P95 TPOT (ms): 376.50
P99 TPOT (ms): 743.84
---------------Inter-token Latency----------------
Mean ITL (ms): 58.84
Median ITL (ms): 63.82
P95 ITL (ms): 70.78
P99 ITL (ms): 73.69
==================================================
|
- 汇总:
vLLM Total TPS = 9632.01, SGLang Total TPS = 4995.66. vLLM 性能更优,差值为 4,636.35 tok/s (92.8%); Mean TPOT = 25.89 ms 与 180.73 ms, 减少 154.84 ms (85.67%).
量化
- 测试配置:
ShareGPT - 后端参数:
| --reasoning-parser=qwen3
--max-model-len=32768
|
基准测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 512
Benchmark duration (s): 65.09
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 15.36
Output token throughput (tok/s): 4487.88
Peak output token throughput (tok/s): 22765417.84
Peak concurrent requests: 512.00
Total Token throughput (tok/s): 9942.93
----------------------Latency---------------------
Mean Latency(s): 28.47
Median Latency(s): 25.85
P95 Latency(s): 57.18
P99 Latency(s): 60.94
---------------Time to First Token----------------
Mean TTFT (ms): 4477.45
Median TTFT (ms): 6644.58
P95 TTFT (ms): 10070.32
P99 TTFT (ms): 10452.25
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 24.85
Median TPOT (ms): 12.27
P95 TPOT (ms): 105.60
P99 TPOT (ms): 155.56
---------------Inter-token Latency----------------
Mean ITL (ms): 8.97
Median ITL (ms): 0.00
P95 ITL (ms): 82.98
P99 ITL (ms): 122.57
==================================================
|
前缀缓存 && 量化
- 测试配置:
ShareGPT - 后端参数:
| --reasoning-parser=qwen3
--enable-prefix-caching
--max-model-len=32768
|
基准测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 512
Benchmark duration (s): 66.14
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 15.12
Output token throughput (tok/s): 4666.64
Peak output token throughput (tok/s): 33515595.85
Peak concurrent requests: 512.00
Total Token throughput (tok/s): 10338.96
----------------------Latency---------------------
Mean Latency(s): 28.95
Median Latency(s): 26.27
P95 Latency(s): 58.15
P99 Latency(s): 61.94
---------------Time to First Token----------------
Mean TTFT (ms): 4274.88
Median TTFT (ms): 6301.11
P95 TTFT (ms): 9633.89
P99 TTFT (ms): 10096.50
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 24.69
Median TPOT (ms): 11.84
P95 TPOT (ms): 107.47
P99 TPOT (ms): 157.98
---------------Inter-token Latency----------------
Mean ITL (ms): 9.53
Median ITL (ms): 0.00
P95 ITL (ms): 85.45
P99 ITL (ms): 126.18
==================================================
|
- 测试配置:
ShareGPT - 后端参数:
| --reasoning-parser=qwen3
--performance-mode=throughput
--max-model-len=32768
--enable-prefix-caching
|
基准测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 512
Benchmark duration (s): 65.25
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 15.33
Output token throughput (tok/s): 4771.31
Peak output token throughput (tok/s): 41235027.15
Peak concurrent requests: 512.00
Total Token throughput (tok/s): 10570.88
----------------------Latency---------------------
Mean Latency(s): 28.45
Median Latency(s): 25.64
P95 Latency(s): 57.14
P99 Latency(s): 60.99
---------------Time to First Token----------------
Mean TTFT (ms): 4123.08
Median TTFT (ms): 6272.83
P95 TTFT (ms): 8823.87
P99 TTFT (ms): 9032.36
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 24.71
Median TPOT (ms): 11.49
P95 TPOT (ms): 108.44
P99 TPOT (ms): 153.41
---------------Inter-token Latency----------------
Mean ITL (ms): 10.10
Median ITL (ms): 0.00
P95 ITL (ms): 84.74
P99 ITL (ms): 124.30
==================================================
|
- 测试配置:
ShareGPT - 后端参数:
| --reasoning-parser=qwen3
--performance-mode=throughput
--max-model-len=32768
--enable-prefix-caching
--kv-cache-dtype=fp8
|
基准测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 512
Benchmark duration (s): 66.34
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 15.07
Output token throughput (tok/s): 4677.83
Peak output token throughput (tok/s): 34141109.18
Peak concurrent requests: 512.00
Total Token throughput (tok/s): 10363.77
----------------------Latency---------------------
Mean Latency(s): 28.91
Median Latency(s): 26.27
P95 Latency(s): 58.08
P99 Latency(s): 62.05
---------------Time to First Token----------------
Mean TTFT (ms): 4166.57
Median TTFT (ms): 6373.29
P95 TTFT (ms): 8930.75
P99 TTFT (ms): 9126.76
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 24.91
Median TPOT (ms): 11.41
P95 TPOT (ms): 111.86
P99 TPOT (ms): 156.62
---------------Inter-token Latency----------------
Mean ITL (ms): 10.14
Median ITL (ms): 0.00
P95 ITL (ms): 89.13
P99 ITL (ms): 125.58
==================================================
|
推测解码 && 量化
- 测试配置:
ShareGPT - 后端参数:
| --reasoning-parser=qwen3
--speculative-config={"method":"mtp","num_speculative_tokens":4}
--max-model-len=32768
|
基准测试结果
| ============ Serving Benchmark Result ============
Successful requests: 516
Maximum request concurrency: 512
Benchmark duration (s): 17.44
Total input tokens: 54307
Total generated tokens: 112466
Request throughput (req/s): 29.59
Output token throughput (tok/s): 10462.21
Peak output token throughput (tok/s): 19149104.07
Peak concurrent requests: 512.00
Total Token throughput (tok/s): 15514.15
----------------------Latency---------------------
Mean Latency(s): 16.92
Median Latency(s): 17.05
P95 Latency(s): 17.28
P99 Latency(s): 17.30
---------------Time to First Token----------------
Mean TTFT (ms): 1956.19
Median TTFT (ms): 0.00
P95 TTFT (ms): 7744.57
P99 TTFT (ms): 8032.17
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 66.41
Median TPOT (ms): 44.74
P95 TPOT (ms): 149.10
P99 TPOT (ms): 477.78
---------------Inter-token Latency----------------
Mean ITL (ms): 0.00
Median ITL (ms): 0.00
P95 ITL (ms): 0.00
P99 ITL (ms): 0.00
==================================================
|
优化选项汇总
| 基准测试用例 | 优化后 | 基准配置 |
| 量化 | Total TPS: 9942.93 (+3.23%)
Mean TPOT(ms): 24.85 | Total TPS: 9632.01
Mean TPOT(ms): 25.89 |
| 前缀缓存 && 量化 | Total TPS: 10338.96 (+7.34%)
Mean TPOT(ms): 24.69 | Total TPS: 9632.01
Mean TPOT(ms): 25.89 |
| 性能模式 && 前缀缓存 && 量化 | Total TPS: 10570.88 (+9.75%)
Mean TPOT(ms): 24.71 | Total TPS: 9632.01
Mean TPOT(ms): 25.89 |
| KV Cache 数据类型 && 性能模式 && 前缀缓存 && 量化 | Total TPS: 10363.77 (+7.60%,低于此前的 +9.75%, 最终命令中不采用此优化)
Mean TPOT(ms): 24.91 | Total TPS: 9632.01
Mean TPOT(ms): 25.89 |
| 推测解码 && 量化 | Total TPS: 15514.15 (成功率:51.6%, 不采用此优化)
Mean TPOT(ms): 66.41 | Total TPS: 9632.01
Mean TPOT(ms): 25.89 |
其他基准测试用例
ShareGPT
- 基准配置的后端参数:
| --reasoning-parser=qwen3
--max-model-len=32768
|
基准配置的测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 512
Benchmark duration (s): 70.72
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 14.14
Output token throughput (tok/s): 4347.55
Peak output token throughput (tok/s): 30810010.86
Peak concurrent requests: 512.00
Total Token throughput (tok/s): 9632.01
----------------------Latency---------------------
Mean Latency(s): 30.19
Median Latency(s): 27.48
P95 Latency(s): 60.73
P99 Latency(s): 65.37
---------------Time to First Token----------------
Mean TTFT (ms): 4072.64
Median TTFT (ms): 5786.23
P95 TTFT (ms): 9276.23
P99 TTFT (ms): 10204.44
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 25.89
Median TPOT (ms): 11.63
P95 TPOT (ms): 119.58
P99 TPOT (ms): 161.45
---------------Inter-token Latency----------------
Mean ITL (ms): 11.46
Median ITL (ms): 0.00
P95 ITL (ms): 101.72
P99 ITL (ms): 132.49
==================================================
|
- 优化后的后端参数:
| --reasoning-parser=qwen3
--performance-mode=throughput
--max-model-len=32768
--enable-prefix-caching
|
优化后的测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 512
Benchmark duration (s): 65.25
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 15.33
Output token throughput (tok/s): 4771.31
Peak output token throughput (tok/s): 41235027.15
Peak concurrent requests: 512.00
Total Token throughput (tok/s): 10570.88
----------------------Latency---------------------
Mean Latency(s): 28.45
Median Latency(s): 25.64
P95 Latency(s): 57.14
P99 Latency(s): 60.99
---------------Time to First Token----------------
Mean TTFT (ms): 4123.08
Median TTFT (ms): 6272.83
P95 TTFT (ms): 8823.87
P99 TTFT (ms): 9032.36
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 24.71
Median TPOT (ms): 11.49
P95 TPOT (ms): 108.44
P99 TPOT (ms): 153.41
---------------Inter-token Latency----------------
Mean ITL (ms): 10.10
Median ITL (ms): 0.00
P95 ITL (ms): 84.74
P99 ITL (ms): 124.30
==================================================
|
吞吐量测试配置
- 基准配置的后端参数:
| --reasoning-parser=qwen3
--max-model-len=32768
|
基准配置的测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 512
Benchmark duration (s): 40.37
Total input tokens: 1033932
Total generated tokens: 128000
Request throughput (req/s): 24.77
Output token throughput (tok/s): 4178.94
Peak output token throughput (tok/s): 4782814.36
Peak concurrent requests: 512.00
Total Token throughput (tok/s): 37934.72
----------------------Latency---------------------
Mean Latency(s): 19.96
Median Latency(s): 20.63
P95 Latency(s): 32.86
P99 Latency(s): 34.01
---------------Time to First Token----------------
Mean TTFT (ms): 5809.82
Median TTFT (ms): 5564.25
P95 TTFT (ms): 14821.97
P99 TTFT (ms): 16424.58
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 45.39
Median TPOT (ms): 43.47
P95 TPOT (ms): 115.80
P99 TPOT (ms): 128.32
---------------Inter-token Latency----------------
Mean ITL (ms): 0.00
Median ITL (ms): 0.00
P95 ITL (ms): 0.00
P99 ITL (ms): 0.00
==================================================
|
- 优化后的后端参数:
| --reasoning-parser=qwen3
--performance-mode=throughput
--max-model-len=32768
--enable-prefix-caching
|
优化后的测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 512
Benchmark duration (s): 33.09
Total input tokens: 1033932
Total generated tokens: 128000
Request throughput (req/s): 30.04
Output token throughput (tok/s): 5559.27
Peak output token throughput (tok/s): 8426225.08
Peak concurrent requests: 512.00
Total Token throughput (tok/s): 50464.84
----------------------Latency---------------------
Mean Latency(s): 16.41
Median Latency(s): 18.57
P95 Latency(s): 25.97
P99 Latency(s): 26.61
---------------Time to First Token----------------
Mean TTFT (ms): 5263.31
Median TTFT (ms): 5797.34
P95 TTFT (ms): 12306.78
P99 TTFT (ms): 13313.63
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 41.12
Median TPOT (ms): 45.29
P95 TPOT (ms): 96.15
P99 TPOT (ms): 104.01
---------------Inter-token Latency----------------
Mean ITL (ms): 0.00
Median ITL (ms): 0.00
P95 ITL (ms): 0.00
P99 ITL (ms): 0.00
==================================================
|
长上下文测试配置
- 基准配置的后端参数:
| --reasoning-parser=qwen3
--max-model-len=32768
|
基准配置的测试结果
| ============ Serving Benchmark Result ============
Successful requests: 100
Maximum request concurrency: 100
Benchmark duration (s): 73.72
Total input tokens: 3200993
Total generated tokens: 10000
Request throughput (req/s): 1.36
Output token throughput (tok/s): 140.12
Peak output token throughput (tok/s): 309.07
Peak concurrent requests: 100.00
Total Token throughput (tok/s): 44993.20
----------------------Latency---------------------
Mean Latency(s): 47.26
Median Latency(s): 48.95
P95 Latency(s): 61.84
P99 Latency(s): 62.18
---------------Time to First Token----------------
Mean TTFT (ms): 31979.13
Median TTFT (ms): 31950.33
P95 TTFT (ms): 55557.79
P99 TTFT (ms): 57562.19
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 319.79
Median TPOT (ms): 319.50
P95 TPOT (ms): 555.58
P99 TPOT (ms): 575.62
---------------Inter-token Latency----------------
Mean ITL (ms): 0.00
Median ITL (ms): 0.00
P95 ITL (ms): 0.00
P99 ITL (ms): 0.00
==================================================
|
- 优化后的后端参数:
| --reasoning-parser=qwen3
--performance-mode=throughput
--max-model-len=32768
--enable-prefix-caching
|
优化后的测试结果
| ============ Serving Benchmark Result ============
Successful requests: 100
Maximum request concurrency: 100
Benchmark duration (s): 59.32
Total input tokens: 3200993
Total generated tokens: 10000
Request throughput (req/s): 1.69
Output token throughput (tok/s): 175.72
Peak output token throughput (tok/s): 950.60
Peak concurrent requests: 100.00
Total Token throughput (tok/s): 56424.42
----------------------Latency---------------------
Mean Latency(s): 44.56
Median Latency(s): 46.68
P95 Latency(s): 51.00
P99 Latency(s): 51.33
---------------Time to First Token----------------
Mean TTFT (ms): 22743.47
Median TTFT (ms): 22414.07
P95 TTFT (ms): 42138.77
P99 TTFT (ms): 43901.20
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 227.43
Median TPOT (ms): 224.14
P95 TPOT (ms): 421.39
P99 TPOT (ms): 439.01
---------------Inter-token Latency----------------
Mean ITL (ms): 0.00
Median ITL (ms): 0.00
P95 ITL (ms): 0.00
P99 ITL (ms): 0.00
==================================================
|
生成密集型测试配置
- 基准配置的后端参数:
| --reasoning-parser=qwen3
--max-model-len=32768
|
基准配置的测试结果
| ============ Serving Benchmark Result ============
Successful requests: 200
Maximum request concurrency: 200
Benchmark duration (s): 57.74
Total input tokens: 201982
Total generated tokens: 400000
Request throughput (req/s): 3.45
Output token throughput (tok/s): 6947.30
Peak output token throughput (tok/s): 77961040.89
Peak concurrent requests: 200.00
Total Token throughput (tok/s): 10455.38
----------------------Latency---------------------
Mean Latency(s): 57.43
Median Latency(s): 57.45
P95 Latency(s): 57.54
P99 Latency(s): 57.57
---------------Time to First Token----------------
Mean TTFT (ms): 1915.55
Median TTFT (ms): 1956.25
P95 TTFT (ms): 3537.91
P99 TTFT (ms): 3608.07
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 2.48
Median TPOT (ms): 1.00
P95 TPOT (ms): 28.70
P99 TPOT (ms): 28.76
---------------Inter-token Latency----------------
Mean ITL (ms): 1.52
Median ITL (ms): 0.00
P95 ITL (ms): 26.98
P99 ITL (ms): 27.96
==================================================
|
- 优化后的后端参数:
| --reasoning-parser=qwen3
--performance-mode=throughput
--max-model-len=32768
--enable-prefix-caching
|
优化后的测试结果
| ============ Serving Benchmark Result ============
Successful requests: 200
Maximum request concurrency: 200
Benchmark duration (s): 49.34
Total input tokens: 201982
Total generated tokens: 400000
Request throughput (req/s): 4.05
Output token throughput (tok/s): 8145.62
Peak output token throughput (tok/s): 100865026.05
Peak concurrent requests: 200.00
Total Token throughput (tok/s): 12258.79
----------------------Latency---------------------
Mean Latency(s): 49.16
Median Latency(s): 49.16
P95 Latency(s): 49.18
P99 Latency(s): 49.20
---------------Time to First Token----------------
Mean TTFT (ms): 1574.69
Median TTFT (ms): 1624.98
P95 TTFT (ms): 2718.49
P99 TTFT (ms): 2763.35
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 2.92
Median TPOT (ms): 0.82
P95 TPOT (ms): 24.58
P99 TPOT (ms): 24.59
---------------Inter-token Latency----------------
Mean ITL (ms): 2.14
Median ITL (ms): 0.00
P95 ITL (ms): 23.67
P99 ITL (ms): 23.99
==================================================
|