Qwen3.5-35B-A3B 延迟优化
结论
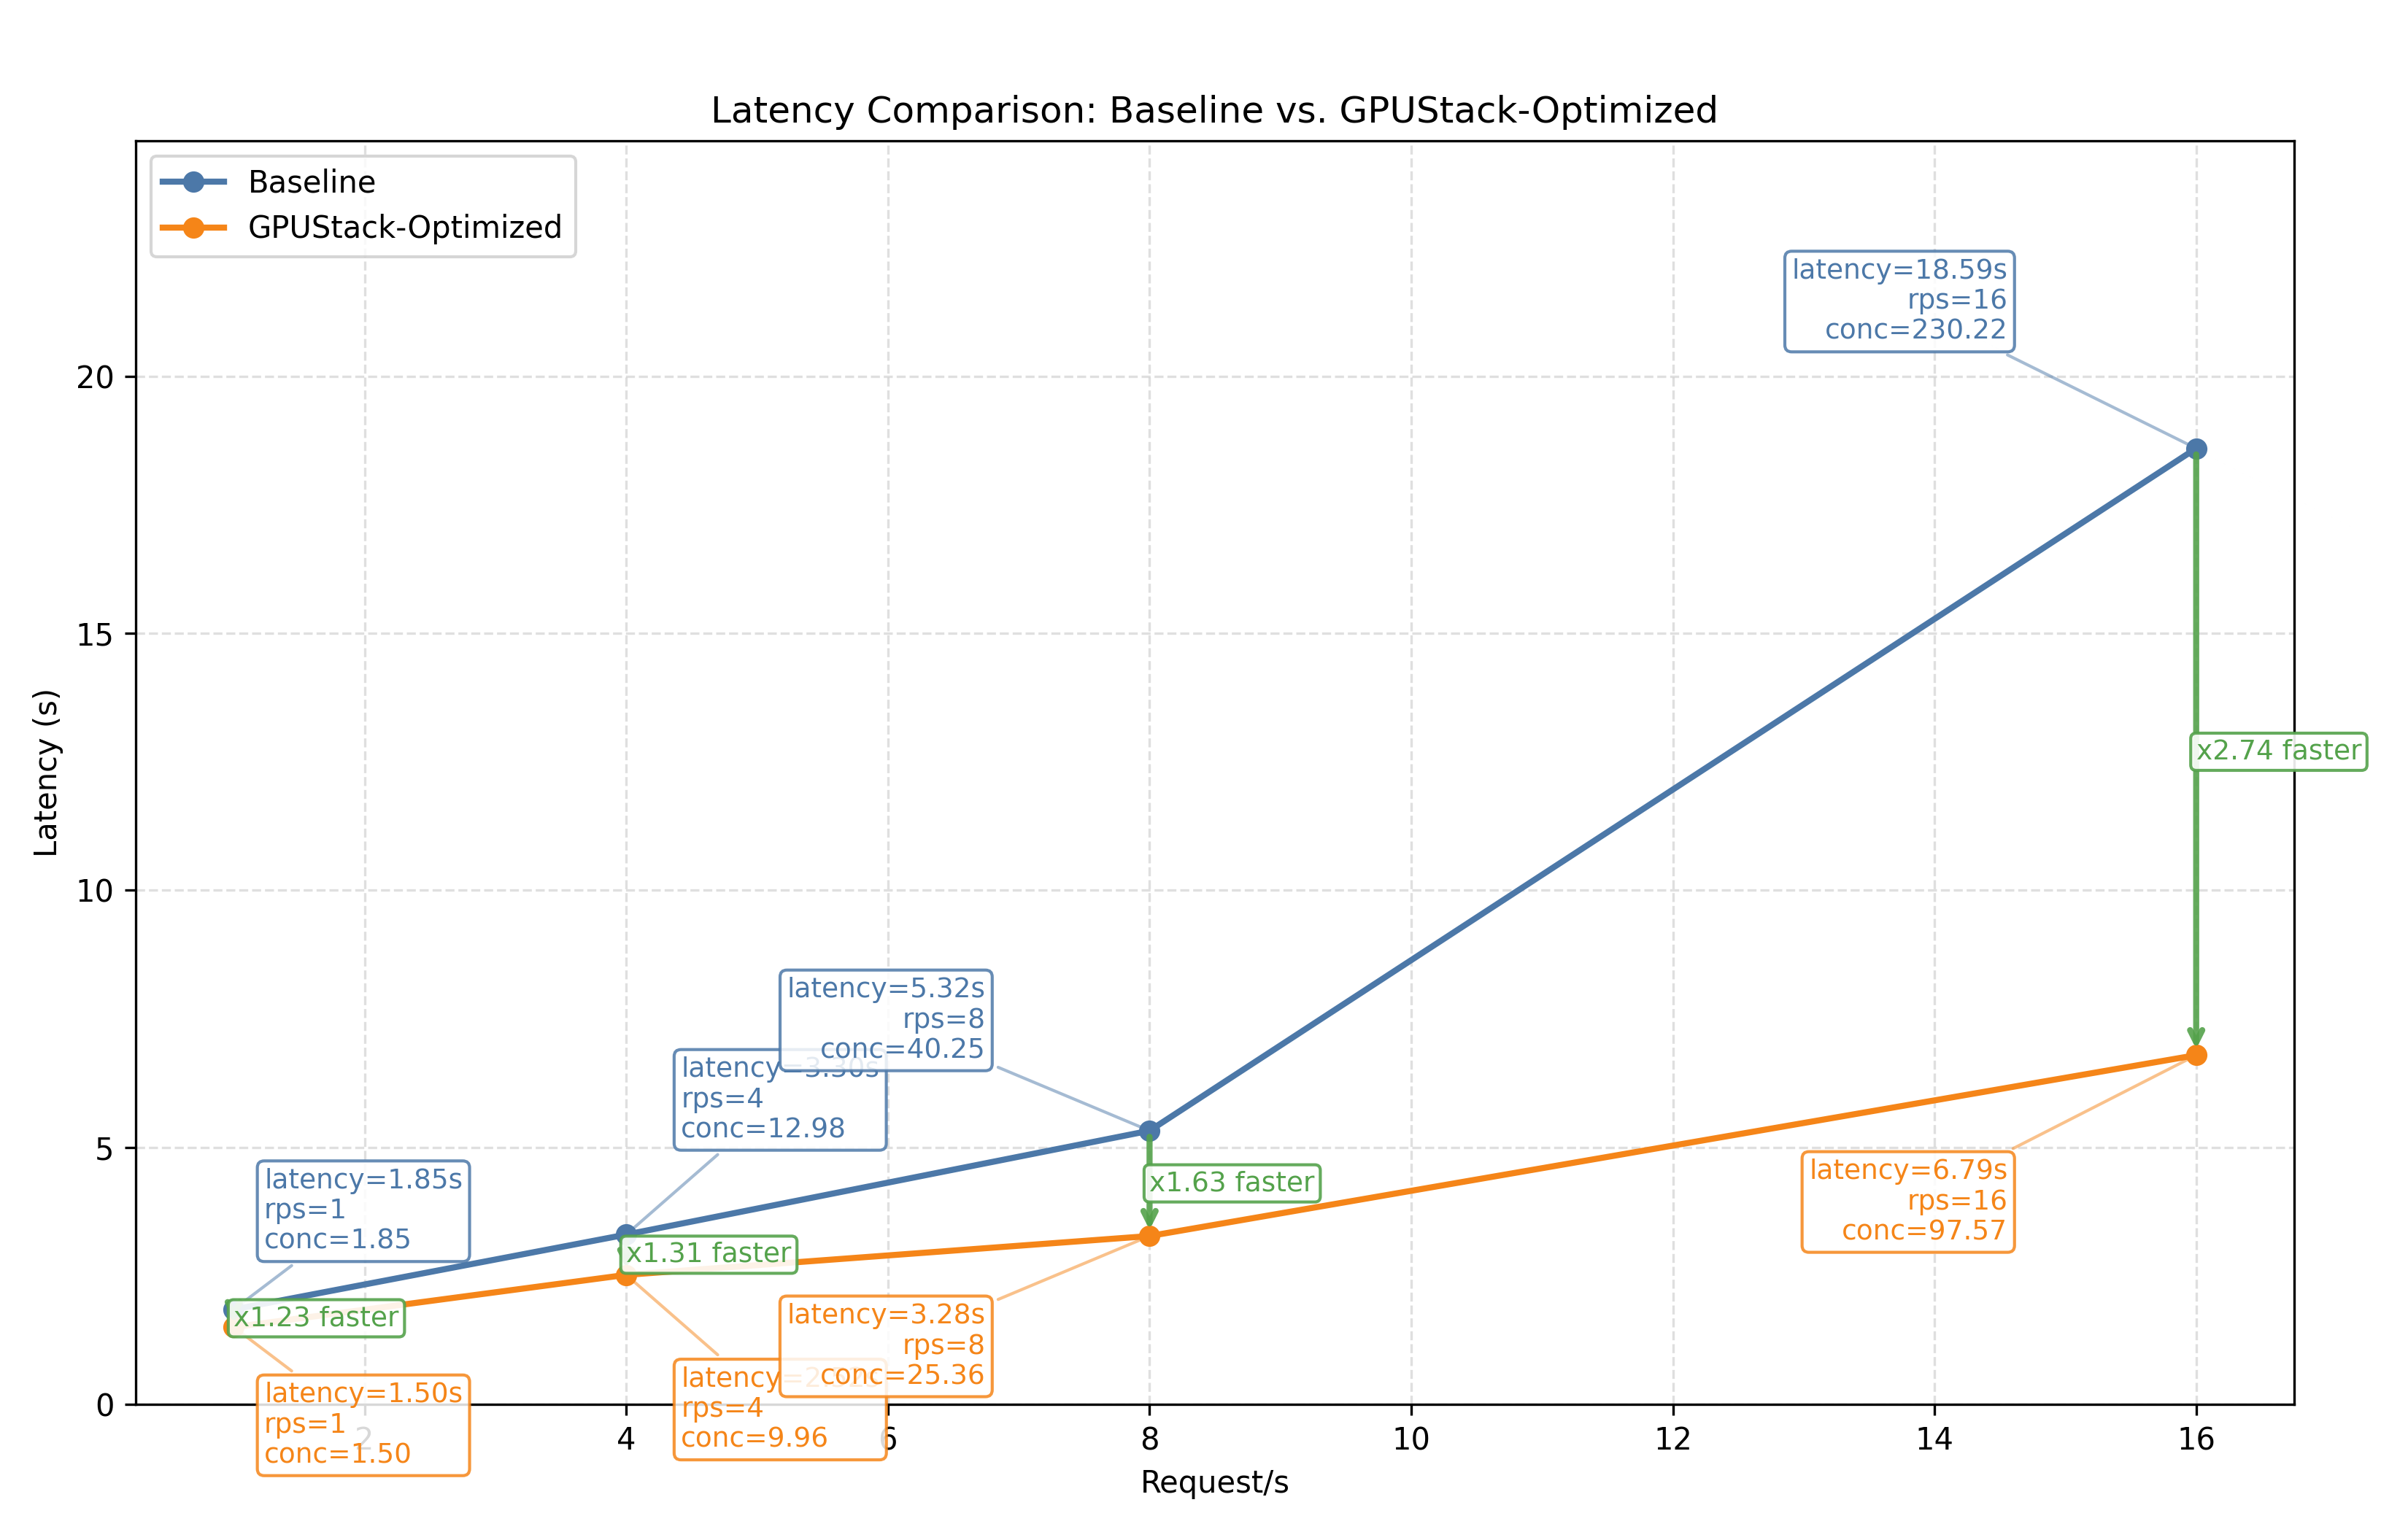
Qwen/Qwen3.5-35B-A3B-FP8 在 NVIDIA H200 上的延迟优化推荐配置:
推理服务命令
| vllm serve Qwen/Qwen3.5-35B-A3B-FP8 \
--reasoning-parser=qwen3 \
--speculative-config={"method":"mtp","num_speculative_tokens":1} \
--max-model-len=32768
|
优化前后的基准测试结果对比:
| 基准测试用例 | 基准配置(未做任何优化的 vLLM) | 优化后 |
| 请求速率 1 | Mean latency: 1.85s/req | Mean latency: 1.50s/req (1.23x,更快) |
| 请求速率 4 | Mean latency: 3.30s/req | Mean latency: 2.52s/req (1.31x,更快) |
| 请求速率 8 | Mean latency: 5.32s/req | Mean latency: 3.28s/req (1.63x,更快) |
| 请求速率 16 | Mean latency: 18.59s/req | Mean latency: 6.79s/req (2.74x,更快) |
说明
- 基准测试未覆盖所有可能的优化组合。例如,我们会选择默认配置下表现最好的推理引擎作为后续调优的起点。这种剪枝方式得到的是局部最优解,未必是全局最优解。
- 其他优化方法取决于具体使用场景,包括最大批大小、调度配置、扩展 KV cache、CUDA graph 等。本文结论可作为进一步针对性优化的起点。
- 测试基于特定的硬件和软件环境。推理引擎的改进可能带来新的结论。
- 量化可能影响准确率,但对于大多数模型,FP8 量化的准确率下降可控制在 1% 以内。详情参见评估结果。因此,强烈建议在低延迟推理服务场景中使用 FP8 量化。
- 推测解码能够显著降低低并发请求的延迟,但加速效果取决于基准测试数据集的数据分布和草稿模型的选择。例如,本测试所选的草稿模型使用英文数据训练,在其他语言上的表现可能不够理想。
如有遗漏或需要根据最新变化更新的内容,请告诉我们。
实验环境
模型
Qwen/Qwen3.5-35B-A3B
硬件
NVIDIA H200
引擎版本
- vLLM v0.17.1
- SGLang v0.5.9
基准测试方法
本项目使用 GPUStack 的一键基准测试功能评估推理服务工作负载。本文中的基准测试均通过该流程执行。
GPUStack 的基准测试通过封装项目 benchmark-runner,基于 guidellm 实现。
对于以下基准测试配置,GPUStack 负责模型部署、基准测试任务提交和结果收集。
基准测试配置
ShareGPT 8RPS
| dataset_name: ShareGPT
request_rate: 8
total_requests: 1000
|
ShareGPT 1RPS
| dataset_name: ShareGPT
request_rate: 1
total_requests: 1000
|
ShareGPT 4RPS
| dataset_name: ShareGPT
request_rate: 4
total_requests: 1000
|
ShareGPT 16RPS
| dataset_name: ShareGPT
request_rate: 16
total_requests: 1000
|
开源工具替代方案
如果不使用 GPUStack,可以直接执行 guidellm benchmark 命令替代 GPUStack 基准测试流程。
对于包含 dataset_name: ShareGPT 的测试配置:
| guidellm benchmark \
--target ${target} \
--profile constant \
--rate ${request_rate} \
--max-requests ${total_requests} \
--processor ${model_path} \
--data ./ShareGPT_V3_unfiltered_cleaned_split.json
|
实验结果
选择推理引擎
vLLM
- 测试配置:
ShareGPT 8RPS - 后端参数:
| --reasoning-parser=qwen3
--max-model-len=32768
|
基准测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 59
Benchmark duration (s): 132.25
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.56
Output token throughput (tok/s): 2137.15
Peak output token throughput (tok/s): 1410355.61
Peak concurrent requests: 59.00
Total Token throughput (tok/s): 4734.87
----------------------Latency---------------------
Mean Latency(s): 5.32
Median Latency(s): 4.72
P95 Latency(s): 13.39
P99 Latency(s): 16.27
---------------Time to First Token----------------
Mean TTFT (ms): 68.48
Median TTFT (ms): 62.59
P95 TTFT (ms): 102.52
P99 TTFT (ms): 131.38
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 2.35
Median TPOT (ms): 0.20
P95 TPOT (ms): 18.88
P99 TPOT (ms): 20.04
---------------Inter-token Latency----------------
Mean ITL (ms): 2.11
Median ITL (ms): 0.00
P95 ITL (ms): 18.78
P99 ITL (ms): 19.94
==================================================
|
SGLang
- 测试配置:
ShareGPT 8RPS - 后端参数:
| --reasoning-parser=qwen3
--context-length=32768
|
基准测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 246
Benchmark duration (s): 148.88
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 6.72
Output token throughput (tok/s): 1896.19
Peak output token throughput (tok/s): 36196.65
Peak concurrent requests: 246.00
Total Token throughput (tok/s): 4201.01
----------------------Latency---------------------
Mean Latency(s): 25.15
Median Latency(s): 23.44
P95 Latency(s): 50.27
P99 Latency(s): 61.67
---------------Time to First Token----------------
Mean TTFT (ms): 6456.42
Median TTFT (ms): 6537.59
P95 TTFT (ms): 12387.08
P99 TTFT (ms): 12670.79
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 89.37
Median TPOT (ms): 82.58
P95 TPOT (ms): 134.49
P99 TPOT (ms): 222.06
---------------Inter-token Latency----------------
Mean ITL (ms): 66.66
Median ITL (ms): 68.70
P95 ITL (ms): 93.84
P99 ITL (ms): 125.45
==================================================
|
- 汇总:
vLLM Mean Latency = 5.32s, SGLang Mean Latency = 25.15s. vLLM 性能更优,差值为 19.83s (速度提升至 4.73x). TTFT = 68.48 ms 与 6456.42 ms, 减少 6387.94 ms (速度提升至 94.29x); TPOT = 2.35 ms 与 89.37 ms, 减少 87.02 ms (速度提升至 38.10x).
量化
- 测试配置:
ShareGPT 8RPS - 后端参数:
| --reasoning-parser=qwen3
--max-model-len=32768
|
基准测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 42
Benchmark duration (s): 130.13
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.68
Output token throughput (tok/s): 2194.80
Peak output token throughput (tok/s): 716367.44
Peak concurrent requests: 42.00
Total Token throughput (tok/s): 4862.60
----------------------Latency---------------------
Mean Latency(s): 3.53
Median Latency(s): 3.09
P95 Latency(s): 8.98
P99 Latency(s): 10.58
---------------Time to First Token----------------
Mean TTFT (ms): 51.56
Median TTFT (ms): 43.82
P95 TTFT (ms): 91.52
P99 TTFT (ms): 107.55
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.61
Median TPOT (ms): 0.14
P95 TPOT (ms): 12.48
P99 TPOT (ms): 13.57
---------------Inter-token Latency----------------
Mean ITL (ms): 1.43
Median ITL (ms): 0.00
P95 ITL (ms): 12.41
P99 ITL (ms): 13.52
==================================================
|
CUDA Graph && 量化
大小 256
- 测试配置:
ShareGPT 8RPS - 后端参数:
| --reasoning-parser=qwen3
--max-cudagraph-capture-size=256
--max-model-len=32768
|
基准测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 43
Benchmark duration (s): 130.15
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.68
Output token throughput (tok/s): 2179.71
Peak output token throughput (tok/s): 634473.24
Peak concurrent requests: 43.00
Total Token throughput (tok/s): 4829.15
----------------------Latency---------------------
Mean Latency(s): 3.66
Median Latency(s): 3.21
P95 Latency(s): 9.22
P99 Latency(s): 11.00
---------------Time to First Token----------------
Mean TTFT (ms): 55.07
Median TTFT (ms): 44.14
P95 TTFT (ms): 94.53
P99 TTFT (ms): 109.17
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.54
Median TPOT (ms): 0.15
P95 TPOT (ms): 12.82
P99 TPOT (ms): 13.89
---------------Inter-token Latency----------------
Mean ITL (ms): 1.35
Median ITL (ms): 0.00
P95 ITL (ms): 12.71
P99 ITL (ms): 13.81
==================================================
|
大小 512
- 测试配置:
ShareGPT 8RPS - 后端参数:
| --reasoning-parser=qwen3
--max-cudagraph-capture-size=512
--max-model-len=32768
|
基准测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 42
Benchmark duration (s): 130.15
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.68
Output token throughput (tok/s): 2180.27
Peak output token throughput (tok/s): 2532773.65
Peak concurrent requests: 42.00
Total Token throughput (tok/s): 4830.39
----------------------Latency---------------------
Mean Latency(s): 3.54
Median Latency(s): 3.11
P95 Latency(s): 8.97
P99 Latency(s): 10.69
---------------Time to First Token----------------
Mean TTFT (ms): 51.99
Median TTFT (ms): 44.02
P95 TTFT (ms): 92.66
P99 TTFT (ms): 110.20
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.77
Median TPOT (ms): 0.15
P95 TPOT (ms): 12.69
P99 TPOT (ms): 13.91
---------------Inter-token Latency----------------
Mean ITL (ms): 1.59
Median ITL (ms): 0.00
P95 ITL (ms): 12.59
P99 ITL (ms): 13.85
==================================================
|
- 汇总:
Size 512 Mean Latency = 3.54s, Size 256 Mean Latency = 3.66s. Size 512 性能更优,差值为 0.12s (速度提升至 1.03x). TTFT = 51.99 ms 与 55.07 ms, 减少 3.07 ms (速度提升至 1.06x); TPOT = 1.77 ms 与 1.54 ms, 增加 0.23 ms (耗时增加至 1.15x).
最大批处理 Token 数 && 量化
16k
- 测试配置:
ShareGPT 8RPS - 后端参数:
| --reasoning-parser=qwen3
--max-model-len=32768
--max-num-batched-tokens=16384
|
基准测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 59
Benchmark duration (s): 130.18
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.68
Output token throughput (tok/s): 2179.90
Peak output token throughput (tok/s): 13119091.07
Peak concurrent requests: 59.00
Total Token throughput (tok/s): 4829.57
----------------------Latency---------------------
Mean Latency(s): 3.82
Median Latency(s): 3.34
P95 Latency(s): 9.63
P99 Latency(s): 11.31
---------------Time to First Token----------------
Mean TTFT (ms): 179.88
Median TTFT (ms): 44.93
P95 TTFT (ms): 262.90
P99 TTFT (ms): 4297.33
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 2.28
Median TPOT (ms): 0.15
P95 TPOT (ms): 13.17
P99 TPOT (ms): 19.61
---------------Inter-token Latency----------------
Mean ITL (ms): 1.65
Median ITL (ms): 0.00
P95 ITL (ms): 12.74
P99 ITL (ms): 14.42
==================================================
|
32k
- 测试配置:
ShareGPT 8RPS - 后端参数:
| --reasoning-parser=qwen3
--max-model-len=32768
--max-num-batched-tokens=32768
|
基准测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 57
Benchmark duration (s): 130.14
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.68
Output token throughput (tok/s): 2216.28
Peak output token throughput (tok/s): 17112760.32
Peak concurrent requests: 57.00
Total Token throughput (tok/s): 4910.18
----------------------Latency---------------------
Mean Latency(s): 3.82
Median Latency(s): 3.36
P95 Latency(s): 9.55
P99 Latency(s): 11.33
---------------Time to First Token----------------
Mean TTFT (ms): 198.01
Median TTFT (ms): 44.82
P95 TTFT (ms): 239.63
P99 TTFT (ms): 4772.71
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 2.26
Median TPOT (ms): 0.15
P95 TPOT (ms): 13.35
P99 TPOT (ms): 21.22
---------------Inter-token Latency----------------
Mean ITL (ms): 1.56
Median ITL (ms): 0.00
P95 ITL (ms): 13.02
P99 ITL (ms): 14.55
==================================================
|
- 汇总:
32k Mean Latency = 3.82s, 16k Mean Latency = 3.82s. 32k 性能更优,差值为 0.00s (速度提升至 1.00x). TTFT = 198.01 ms 与 179.88 ms, 增加 18.12 ms (耗时增加至 1.10x); TPOT = 2.26 ms 与 2.28 ms, 减少 0.02 ms (速度提升至 1.01x).
- 测试配置:
ShareGPT 8RPS - 后端参数:
| --reasoning-parser=qwen3
--performance-mode=interactivity
--max-model-len=32768
|
基准测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 55
Benchmark duration (s): 129.88
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.70
Output token throughput (tok/s): 2187.29
Peak output token throughput (tok/s): 10792660.29
Peak concurrent requests: 55.00
Total Token throughput (tok/s): 4845.96
----------------------Latency---------------------
Mean Latency(s): 3.67
Median Latency(s): 3.25
P95 Latency(s): 9.10
P99 Latency(s): 11.00
---------------Time to First Token----------------
Mean TTFT (ms): 184.63
Median TTFT (ms): 43.80
P95 TTFT (ms): 311.58
P99 TTFT (ms): 4340.84
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 2.16
Median TPOT (ms): 0.15
P95 TPOT (ms): 13.05
P99 TPOT (ms): 20.02
---------------Inter-token Latency----------------
Mean ITL (ms): 1.51
Median ITL (ms): 0.00
P95 ITL (ms): 12.37
P99 ITL (ms): 15.66
==================================================
|
前缀缓存 && 量化
- 测试配置:
ShareGPT 8RPS - 后端参数:
| --reasoning-parser=qwen3
--max-model-len=32768
--enable-prefix-caching
|
基准测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 44
Benchmark duration (s): 130.20
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.68
Output token throughput (tok/s): 2179.34
Peak output token throughput (tok/s): 1595392.00
Peak concurrent requests: 44.00
Total Token throughput (tok/s): 4828.33
----------------------Latency---------------------
Mean Latency(s): 3.70
Median Latency(s): 3.24
P95 Latency(s): 9.43
P99 Latency(s): 11.34
---------------Time to First Token----------------
Mean TTFT (ms): 58.68
Median TTFT (ms): 44.61
P95 TTFT (ms): 125.39
P99 TTFT (ms): 249.12
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.81
Median TPOT (ms): 0.15
P95 TPOT (ms): 12.83
P99 TPOT (ms): 14.84
---------------Inter-token Latency----------------
Mean ITL (ms): 1.60
Median ITL (ms): 0.00
P95 ITL (ms): 12.75
P99 ITL (ms): 14.80
==================================================
|
推测解码 && 量化
- 测试配置:
ShareGPT 8RPS - 后端参数:
| --reasoning-parser=qwen3
--speculative-config={"method":"mtp","num_speculative_tokens":1}
--max-model-len=32768
|
基准测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 57
Benchmark duration (s): 129.19
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.74
Output token throughput (tok/s): 2203.31
Peak output token throughput (tok/s): 8794775.78
Peak concurrent requests: 57.00
Total Token throughput (tok/s): 4881.45
----------------------Latency---------------------
Mean Latency(s): 3.28
Median Latency(s): 2.85
P95 Latency(s): 8.22
P99 Latency(s): 10.49
---------------Time to First Token----------------
Mean TTFT (ms): 263.11
Median TTFT (ms): 60.45
P95 TTFT (ms): 891.65
P99 TTFT (ms): 5402.99
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 2.34
Median TPOT (ms): 0.21
P95 TPOT (ms): 11.39
P99 TPOT (ms): 22.27
---------------Inter-token Latency----------------
Mean ITL (ms): 1.41
Median ITL (ms): 0.00
P95 ITL (ms): 10.58
P99 ITL (ms): 14.34
==================================================
|
优化选项汇总
| 基准测试用例 | 组别 | 优化后 | 基准配置 | 对比 |
| ShareGPT 8RPS (r=8) | 选择推理引擎 | 5.32s | 5.32s | (1.00x,更快) |
| ShareGPT 8RPS (r=8) | 量化 | 3.53s | 5.32s | (1.51x,更快) |
| ShareGPT 8RPS (r=8) | CUDA Graph && 量化 | 3.54s | 5.32s | (1.50x,更快) |
| ShareGPT 8RPS (r=8) | 最大批处理 Token 数 && 量化 | 3.82s | 5.32s | (1.39x,更快) |
| ShareGPT 8RPS (r=8) | 性能模式 && 量化 | 3.67s | 5.32s | (1.45x,更快) |
| ShareGPT 8RPS (r=8) | 前缀缓存 && 量化 | 3.70s | 5.32s | (1.44x,更快) |
| ShareGPT 8RPS (r=8) | 推测解码 && 量化 | 3.28s | 5.32s | (1.63x,更快) |
其他基准测试用例
请求速率 1
- 基准配置的后端参数:
| --reasoning-parser=qwen3
--max-model-len=32768
|
基准配置的测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 6
Benchmark duration (s): 1000.76
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 1.00
Output token throughput (tok/s): 281.70
Peak output token throughput (tok/s): 205535.27
Peak concurrent requests: 6.00
Total Token throughput (tok/s): 624.11
----------------------Latency---------------------
Mean Latency(s): 1.85
Median Latency(s): 1.57
P95 Latency(s): 4.80
P99 Latency(s): 5.90
---------------Time to First Token----------------
Mean TTFT (ms): 46.01
Median TTFT (ms): 35.63
P95 TTFT (ms): 90.77
P99 TTFT (ms): 98.52
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.06
Median TPOT (ms): 0.12
P95 TPOT (ms): 6.90
P99 TPOT (ms): 7.56
---------------Inter-token Latency----------------
Mean ITL (ms): 0.90
Median ITL (ms): 0.00
P95 ITL (ms): 6.81
P99 ITL (ms): 7.50
==================================================
|
- 优化后的后端参数:
| --reasoning-parser=qwen3
--speculative-config={"method":"mtp","num_speculative_tokens":1}
--max-model-len=32768
|
优化后的测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 5
Benchmark duration (s): 1000.01
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 1.00
Output token throughput (tok/s): 281.71
Peak output token throughput (tok/s): 160685.52
Peak concurrent requests: 5.00
Total Token throughput (tok/s): 624.13
----------------------Latency---------------------
Mean Latency(s): 1.50
Median Latency(s): 1.31
P95 Latency(s): 3.88
P99 Latency(s): 4.65
---------------Time to First Token----------------
Mean TTFT (ms): 66.56
Median TTFT (ms): 55.47
P95 TTFT (ms): 128.15
P99 TTFT (ms): 145.32
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 0.89
Median TPOT (ms): 0.17
P95 TPOT (ms): 5.38
P99 TPOT (ms): 5.89
---------------Inter-token Latency----------------
Mean ITL (ms): 0.66
Median ITL (ms): 0.00
P95 ITL (ms): 5.25
P99 ITL (ms): 5.75
==================================================
|
请求速率 4
- 基准配置的后端参数:
| --reasoning-parser=qwen3
--max-model-len=32768
|
基准配置的测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 34
Benchmark duration (s): 254.48
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 3.93
Output token throughput (tok/s): 1119.46
Peak output token throughput (tok/s): 12576036.09
Peak concurrent requests: 34.00
Total Token throughput (tok/s): 2480.18
----------------------Latency---------------------
Mean Latency(s): 3.30
Median Latency(s): 2.84
P95 Latency(s): 8.64
P99 Latency(s): 10.14
---------------Time to First Token----------------
Mean TTFT (ms): 126.16
Median TTFT (ms): 42.08
P95 TTFT (ms): 96.81
P99 TTFT (ms): 3590.00
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 2.02
Median TPOT (ms): 0.14
P95 TPOT (ms): 11.71
P99 TPOT (ms): 15.87
---------------Inter-token Latency----------------
Mean ITL (ms): 1.57
Median ITL (ms): 0.00
P95 ITL (ms): 11.49
P99 ITL (ms): 13.24
==================================================
|
- 优化后的后端参数:
| --reasoning-parser=qwen3
--speculative-config={"method":"mtp","num_speculative_tokens":1}
--max-model-len=32768
|
优化后的测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 35
Benchmark duration (s): 253.07
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 3.95
Output token throughput (tok/s): 1126.78
Peak output token throughput (tok/s): 14184016.34
Peak concurrent requests: 35.00
Total Token throughput (tok/s): 2496.38
----------------------Latency---------------------
Mean Latency(s): 2.52
Median Latency(s): 2.13
P95 Latency(s): 6.48
P99 Latency(s): 10.07
---------------Time to First Token----------------
Mean TTFT (ms): 221.71
Median TTFT (ms): 62.58
P95 TTFT (ms): 143.76
P99 TTFT (ms): 5977.29
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.78
Median TPOT (ms): 0.21
P95 TPOT (ms): 8.39
P99 TPOT (ms): 20.07
---------------Inter-token Latency----------------
Mean ITL (ms): 0.99
Median ITL (ms): 0.00
P95 ITL (ms): 7.98
P99 ITL (ms): 9.26
==================================================
|
请求速率 8
- 基准配置的后端参数:
| --reasoning-parser=qwen3
--max-model-len=32768
|
基准配置的测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 59
Benchmark duration (s): 132.25
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.56
Output token throughput (tok/s): 2137.15
Peak output token throughput (tok/s): 1410355.61
Peak concurrent requests: 59.00
Total Token throughput (tok/s): 4734.87
----------------------Latency---------------------
Mean Latency(s): 5.32
Median Latency(s): 4.72
P95 Latency(s): 13.39
P99 Latency(s): 16.27
---------------Time to First Token----------------
Mean TTFT (ms): 68.48
Median TTFT (ms): 62.59
P95 TTFT (ms): 102.52
P99 TTFT (ms): 131.38
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 2.35
Median TPOT (ms): 0.20
P95 TPOT (ms): 18.88
P99 TPOT (ms): 20.04
---------------Inter-token Latency----------------
Mean ITL (ms): 2.11
Median ITL (ms): 0.00
P95 ITL (ms): 18.78
P99 ITL (ms): 19.94
==================================================
|
- 优化后的后端参数:
| --reasoning-parser=qwen3
--speculative-config={"method":"mtp","num_speculative_tokens":1}
--max-model-len=32768
|
优化后的测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 57
Benchmark duration (s): 129.19
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.74
Output token throughput (tok/s): 2203.31
Peak output token throughput (tok/s): 8794775.78
Peak concurrent requests: 57.00
Total Token throughput (tok/s): 4881.45
----------------------Latency---------------------
Mean Latency(s): 3.28
Median Latency(s): 2.85
P95 Latency(s): 8.22
P99 Latency(s): 10.49
---------------Time to First Token----------------
Mean TTFT (ms): 263.11
Median TTFT (ms): 60.45
P95 TTFT (ms): 891.65
P99 TTFT (ms): 5402.99
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 2.34
Median TPOT (ms): 0.21
P95 TPOT (ms): 11.39
P99 TPOT (ms): 22.27
---------------Inter-token Latency----------------
Mean ITL (ms): 1.41
Median ITL (ms): 0.00
P95 ITL (ms): 10.58
P99 ITL (ms): 14.34
==================================================
|
请求速率 16
- 基准配置的后端参数:
| --reasoning-parser=qwen3
--max-model-len=32768
|
基准配置的测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 447
Benchmark duration (s): 80.77
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 12.38
Output token throughput (tok/s): 3499.91
Peak output token throughput (tok/s): 4256990.61
Peak concurrent requests: 447.00
Total Token throughput (tok/s): 7754.06
----------------------Latency---------------------
Mean Latency(s): 18.59
Median Latency(s): 16.18
P95 Latency(s): 43.61
P99 Latency(s): 53.53
---------------Time to First Token----------------
Mean TTFT (ms): 232.24
Median TTFT (ms): 229.86
P95 TTFT (ms): 402.69
P99 TTFT (ms): 465.50
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 8.90
Median TPOT (ms): 0.67
P95 TPOT (ms): 68.77
P99 TPOT (ms): 94.53
---------------Inter-token Latency----------------
Mean ITL (ms): 8.11
Median ITL (ms): 0.00
P95 ITL (ms): 68.39
P99 ITL (ms): 93.98
==================================================
|
- 优化后的后端参数:
| --reasoning-parser=qwen3
--speculative-config={"method":"mtp","num_speculative_tokens":1}
--max-model-len=32768
|
优化后的测试结果
| ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 145
Benchmark duration (s): 69.63
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 14.36
Output token throughput (tok/s): 4070.93
Peak output token throughput (tok/s): 3898930.48
Peak concurrent requests: 145.00
Total Token throughput (tok/s): 9019.16
----------------------Latency---------------------
Mean Latency(s): 6.79
Median Latency(s): 5.91
P95 Latency(s): 16.32
P99 Latency(s): 21.54
---------------Time to First Token----------------
Mean TTFT (ms): 150.30
Median TTFT (ms): 133.22
P95 TTFT (ms): 293.44
P99 TTFT (ms): 345.17
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 3.23
Median TPOT (ms): 0.42
P95 TPOT (ms): 25.40
P99 TPOT (ms): 28.30
---------------Inter-token Latency----------------
Mean ITL (ms): 2.70
Median ITL (ms): 0.00
P95 ITL (ms): 25.13
P99 ITL (ms): 28.02
==================================================
|