跳转至

NVIDIA H200 GPUs 上的 GLM-4.x 吞吐量优化

结论

glm-4.6-h200

GLM-4.x (4.5、4.6 和 4.7) 在 H200 GPUs 上的吞吐量优化推荐配置:

推理服务命令
python3 -m sglang.launch_server --model zai-org/GLM-4.6-FP8 --tp 4 --tool-call-parser glm --reasoning-parser glm45

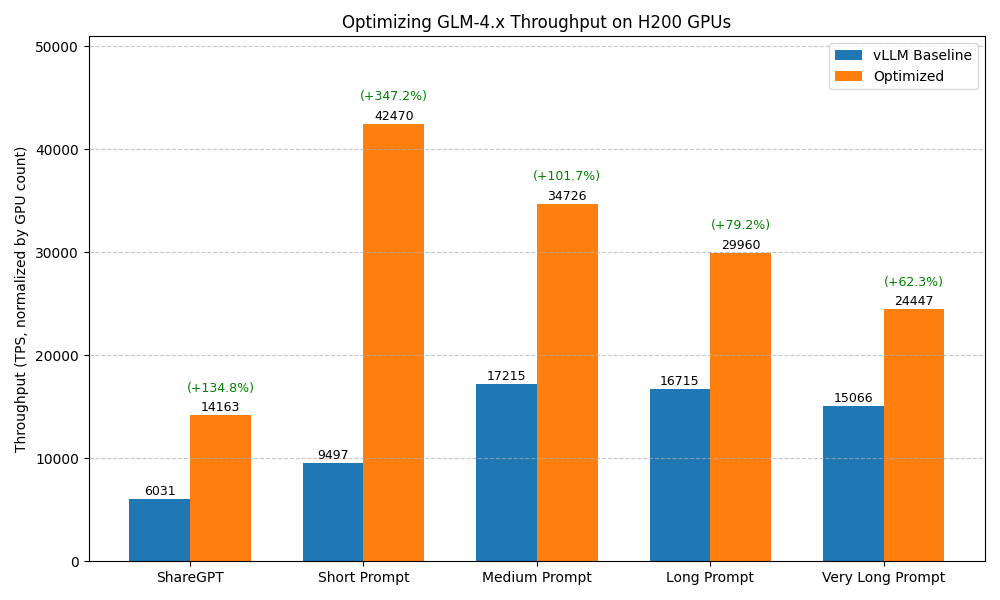
优化前后的基准测试结果对比:

基准测试用例 基准配置(未做任何优化的 vLLM) 优化后(换算为相同 GPU 数量)
ShareGPT Total TPS: 6030.90
Mean TPOT(ms): 197.85
Total TPS: 7081.34x2 (+134.8%)
Mean TPOT(ms): 256.43
短提示词 Total TPS: 9497.19
Mean TPOT(ms): 351.26
Total TPS: 21234.81x2 (+347.2%)
Mean TPOT(ms): 800.25
中等长度提示词 Total TPS: 17214.85
Mean TPOT(ms): 269.75
Total TPS: 17363.22x2 (+101.7%)
Mean TPOT(ms): 144.82
长提示词 Total TPS: 16714.91
Mean TPOT(ms): 205.69
Total TPS: 14979.90x2 (+79.2%)
Mean TPOT(ms): 97.74
超长提示词 Total TPS: 15066.09
Mean TPOT(ms): 479.17
Total TPS: 12223.53x2 (+62.3%)
Mean TPOT(ms): 191.61

说明

  1. 基准测试未覆盖所有可能的优化组合。例如,我们会选择默认配置下表现最好的推理引擎作为后续调优的起点。这种剪枝方式得到的是局部最优解,未必是全局最优解。
  2. 其他优化方法取决于具体使用场景,包括最大批大小、调度配置、扩展 KV cache、CUDA graph 等。本文结论可作为进一步针对性优化的起点。
  3. 测试基于特定的硬件和软件环境。推理引擎的改进可能带来新的结论。
  4. 量化可能影响准确率,但对于大多数模型,FP8 量化的准确率下降可控制在 1% 以内。详情参见评估结果。因此,强烈建议在高吞吐量推理服务场景中使用 FP8 量化。

如有遗漏或需要根据最新变化更新的内容,请告诉我们。

优化目标

在高并发请求场景下实现高吞吐量。

实验环境

模型

zai-org/GLM-4.6

硬件

单节点配备 8 × NVIDIA H200 SXM GPU。

引擎版本

  • vLLM: v0.11.0
  • SGLang: v0.5.3
  • TensorRT-LLM: v1.0.0

基准测试数据集

  1. ShareGPT
  2. 不同序列长度的随机数据集:
    • 超长提示词:32000 输入 tokens,100 输出 tokens
    • 长提示词:4000 输入 tokens,200 输出 tokens
    • 中等长度提示词:2000 输入 tokens,100 输出 tokens
    • 短提示词:128 输入 tokens,4 输出 tokens

基准测试脚本

使用 vLLM bench CLI 工具对模型性能进行基准测试。运行基准测试的命令如下:

1
2
3
4
5
6
7
8
# Prepare the ShareGPT dataset
wget https://huggingface.co/datasets/anon8231489123/ShareGPT_Vicuna_unfiltered/resolve/main/ShareGPT_V3_unfiltered_cleaned_split.json

# Benchmark on ShareGPT dataset
vllm bench serve --model zai-org/GLM-4.6 --backend openai-chat --endpoint /v1/chat/completions --dataset-name sharegpt --dataset-path ShareGPT_V3_unfiltered_cleaned_split.json --num-prompts 1000

# Benchmark on random dataset (fixed seed for reproducibility)
vllm bench serve --model zai-org/GLM-4.6 --backend openai-chat --endpoint /v1/chat/completions --dataset-name random --random-input-len 4000 --random-output-len 200 --num-prompts 500 --seed 42

实验结果

1. 选择推理引擎

vLLM

推理服务脚本
vllm serve zai-org/GLM-4.6 -tp 8
基准测试结果
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  68.67
Total input tokens:                      214465
Total generated tokens:                  199702
Request throughput (req/s):              14.56
Output token throughput (tok/s):         2907.97
Peak output token throughput (tok/s):    7158.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          6030.90
---------------Time to First Token----------------
Mean TTFT (ms):                          15339.53
Median TTFT (ms):                        15377.50
P99 TTFT (ms):                           21078.26
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          197.85
Median TPOT (ms):                        145.75
P99 TPOT (ms):                           411.50
---------------Inter-token Latency----------------
Mean ITL (ms):                           109.47
Median ITL (ms):                         68.98
P99 ITL (ms):                            413.20
==================================================
SGLang

推理服务脚本
python3 -m sglang.launch_server --model-path zai-org/GLM-4.6 --host 0.0.0.0 --port 8000 --tp-size 8
基准测试结果
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  59.37
Total input tokens:                      214465
Total generated tokens:                  199904
Request throughput (req/s):              16.84
Output token throughput (tok/s):         3366.90
Peak output token throughput (tok/s):    7570.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          6979.05
---------------Time to First Token----------------
Mean TTFT (ms):                          6044.62
Median TTFT (ms):                        5851.20
P99 TTFT (ms):                           10817.86
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          282.87
Median TPOT (ms):                        148.97
P99 TPOT (ms):                           1610.70
---------------Inter-token Latency----------------
Mean ITL (ms):                           113.29
Median ITL (ms):                         64.03
P99 ITL (ms):                            369.42
==================================================

结果:SGLang(6979.05 tok/s) > vLLM (6030.90 tok/s) > TensorRT-LLM (不支持)

2. SGLang 中的 量化

FP8

推理服务脚本
python3 -m sglang.launch_server --model-path zai-org/GLM-4.6-FP8 --host 0.0.0.0 --port 8000 --tp-size 8
基准测试结果
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  52.72
Total input tokens:                      214465
Total generated tokens:                  199904
Request throughput (req/s):              18.97
Output token throughput (tok/s):         3791.55
Peak output token throughput (tok/s):    8987.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          7859.29
---------------Time to First Token----------------
Mean TTFT (ms):                          5085.56
Median TTFT (ms):                        4847.02
P99 TTFT (ms):                           10068.82
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          271.63
Median TPOT (ms):                        144.47
P99 TPOT (ms):                           1542.73
---------------Inter-token Latency----------------
Mean ITL (ms):                           105.34
Median ITL (ms):                         52.76
P99 ITL (ms):                            321.65
==================================================

3. SGLang 中的 并行策略

TP8

推理服务脚本
python3 -m sglang.launch_server --model-path zai-org/GLM-4.6-FP8 --host 0.0.0.0 --port 8000 --tp-size 8
基准测试结果
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  52.72
Total input tokens:                      214465
Total generated tokens:                  199904
Request throughput (req/s):              18.97
Output token throughput (tok/s):         3791.55
Peak output token throughput (tok/s):    8987.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          7859.29
---------------Time to First Token----------------
Mean TTFT (ms):                          5085.56
Median TTFT (ms):                        4847.02
P99 TTFT (ms):                           10068.82
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          271.63
Median TPOT (ms):                        144.47
P99 TPOT (ms):                           1542.73
---------------Inter-token Latency----------------
Mean ITL (ms):                           105.34
Median ITL (ms):                         52.76
P99 ITL (ms):                            321.65
==================================================

TP4

推理服务脚本
python3 -m sglang.launch_server --model-path zai-org/GLM-4.6-FP8 --host 0.0.0.0 --port 8000 --tp-size 4
基准测试结果
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  58.52
Total input tokens:                      214465
Total generated tokens:                  199904
Request throughput (req/s):              17.09
Output token throughput (tok/s):         3416.25
Peak output token throughput (tok/s):    7602.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          7081.34
---------------Time to First Token----------------
Mean TTFT (ms):                          5786.78
Median TTFT (ms):                        5769.81
P99 TTFT (ms):                           10134.80
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          256.43
Median TPOT (ms):                        144.11
P99 TPOT (ms):                           1451.02
---------------Inter-token Latency----------------
Mean ITL (ms):                           109.76
Median ITL (ms):                         62.64
P99 ITL (ms):                            330.68
==================================================

TP4+EP4

推理服务脚本
python3 -m sglang.launch_server --model-path zai-org/GLM-4.6-FP8 --host 0.0.0.0 --port 8000 --tp-size 4 --ep-size 4
基准测试结果
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  62.06
Total input tokens:                      214465
Total generated tokens:                  199904
Request throughput (req/s):              16.11
Output token throughput (tok/s):         3221.11
Peak output token throughput (tok/s):    8209.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          6676.84
---------------Time to First Token----------------
Mean TTFT (ms):                          6632.87
Median TTFT (ms):                        6433.53
P99 TTFT (ms):                           11461.66
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          284.20
Median TPOT (ms):                        157.89
P99 TPOT (ms):                           1629.92
---------------Inter-token Latency----------------
Mean ITL (ms):                           117.77
Median ITL (ms):                         61.25
P99 ITL (ms):                            406.32
==================================================

优化选项汇总

优化选项 吞吐量提升
引擎选择 +15.7%
量化 +12.6%
并行策略 +80.2%

其他基准测试用例

我们进一步对优化后的配置进行了基准测试,评估其在不同工作负载下的泛化表现。

基准配置的推理服务脚本
vllm serve zai-org/GLM-4.6 -tp 8
基准配置的测试结果
# random 32K input
============ Serving Benchmark Result ============
Successful requests:                     100
Benchmark duration (s):                  213.02
Total input tokens:                      3200000
Total generated tokens:                  9406
Request throughput (req/s):              0.47
Output token throughput (tok/s):         44.16
Peak output token throughput (tok/s):    489.00
Peak concurrent requests:                100.00
Total Token throughput (tok/s):          15066.09
---------------Time to First Token----------------
Mean TTFT (ms):                          105089.84
Median TTFT (ms):                        104737.57
P99 TTFT (ms):                           208225.57
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          479.17
Median TPOT (ms):                        541.92
P99 TPOT (ms):                           544.17
---------------Inter-token Latency----------------
Mean ITL (ms):                           474.58
Median ITL (ms):                         529.63
P99 ITL (ms):                            637.86
==================================================

# random 4K input
============ Serving Benchmark Result ============
Successful requests:                     500
Benchmark duration (s):                  125.61
Total input tokens:                      1999787
Total generated tokens:                  99801
Request throughput (req/s):              3.98
Output token throughput (tok/s):         794.52
Peak output token throughput (tok/s):    3810.00
Peak concurrent requests:                500.00
Total Token throughput (tok/s):          16714.91
---------------Time to First Token----------------
Mean TTFT (ms):                          57737.75
Median TTFT (ms):                        59379.10
P99 TTFT (ms):                           116713.01
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          205.69
Median TPOT (ms):                        241.12
P99 TPOT (ms):                           260.89
---------------Inter-token Latency----------------
Mean ITL (ms):                           205.05
Median ITL (ms):                         59.67
P99 ITL (ms):                            424.92
==================================================

# random 2K input
============ Serving Benchmark Result ============
Successful requests:                     500
Benchmark duration (s):                  60.96
Total input tokens:                      999429
Total generated tokens:                  50000
Request throughput (req/s):              8.20
Output token throughput (tok/s):         820.20
Peak output token throughput (tok/s):    5415.00
Peak concurrent requests:                500.00
Total Token throughput (tok/s):          17214.85
---------------Time to First Token----------------
Mean TTFT (ms):                          30215.66
Median TTFT (ms):                        29924.42
P99 TTFT (ms):                           55334.09
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          269.75
Median TPOT (ms):                        283.63
P99 TPOT (ms):                           407.32
---------------Inter-token Latency----------------
Mean ITL (ms):                           267.55
Median ITL (ms):                         402.36
P99 ITL (ms):                            417.66
==================================================

# random 128 input
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  13.89
Total input tokens:                      127881
Total generated tokens:                  4000
Request throughput (req/s):              72.01
Output token throughput (tok/s):         288.05
Peak output token throughput (tok/s):    2063.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          9497.19
---------------Time to First Token----------------
Mean TTFT (ms):                          11467.27
Median TTFT (ms):                        10707.53
P99 TTFT (ms):                           13722.66
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          351.26
Median TPOT (ms):                        397.14
P99 TPOT (ms):                           409.34
---------------Inter-token Latency----------------
Mean ITL (ms):                           263.45
Median ITL (ms):                         389.46
P99 ITL (ms):                            443.88
==================================================

# ShareGPT batch size 4
============ Serving Benchmark Result ============
Successful requests:                     100
Maximum request concurrency:             4
Benchmark duration (s):                  103.11
Total input tokens:                      22992
Total generated tokens:                  21794
Request throughput (req/s):              0.97
Output token throughput (tok/s):         211.38
Peak output token throughput (tok/s):    232.00
Peak concurrent requests:                9.00
Total Token throughput (tok/s):          434.37
---------------Time to First Token----------------
Mean TTFT (ms):                          70.16
Median TTFT (ms):                        62.63
P99 TTFT (ms):                           148.47
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          18.11
Median TPOT (ms):                        17.80
P99 TPOT (ms):                           23.44
---------------Inter-token Latency----------------
Mean ITL (ms):                           17.85
Median ITL (ms):                         17.55
P99 ITL (ms):                            26.92
==================================================
优化后的推理服务脚本
python3 -m sglang.launch_server --model zai-org/GLM-4.6-FP8 --tp 4 \
    --tool-call-parser glm --reasoning-parser glm45
优化后的测试结果
# random 32K input
============ Serving Benchmark Result ============
Successful requests:                     100
Benchmark duration (s):                  262.58
Total input tokens:                      3200000
Total generated tokens:                  9703
Request throughput (req/s):              0.38
Output token throughput (tok/s):         36.95
Peak output token throughput (tok/s):    390.00
Peak concurrent requests:                100.00
Total Token throughput (tok/s):          12223.53
---------------Time to First Token----------------
Mean TTFT (ms):                          129699.21
Median TTFT (ms):                        129839.73
P99 TTFT (ms):                           257123.03
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          191.61
Median TPOT (ms):                        181.54
P99 TPOT (ms):                           350.40
---------------Inter-token Latency----------------
Mean ITL (ms):                           189.68
Median ITL (ms):                         40.53
P99 ITL (ms):                            71.16
==================================================

# random 4K input
============ Serving Benchmark Result ============
Successful requests:                     500
Benchmark duration (s):                  140.16
Total input tokens:                      1999787
Total generated tokens:                  99801
Request throughput (req/s):              3.57
Output token throughput (tok/s):         712.05
Peak output token throughput (tok/s):    2688.00
Peak concurrent requests:                500.00
Total Token throughput (tok/s):          14979.90
---------------Time to First Token----------------
Mean TTFT (ms):                          65196.25
Median TTFT (ms):                        67840.59
P99 TTFT (ms):                           131861.02
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          97.74
Median TPOT (ms):                        94.74
P99 TPOT (ms):                           149.34
---------------Inter-token Latency----------------
Mean ITL (ms):                           97.55
Median ITL (ms):                         47.60
P99 ITL (ms):                            314.57
==================================================

# random 2K input
============ Serving Benchmark Result ============
Successful requests:                     500
Benchmark duration (s):                  60.44
Total input tokens:                      999429
Total generated tokens:                  50000
Request throughput (req/s):              8.27
Output token throughput (tok/s):         827.27
Peak output token throughput (tok/s):    4460.00
Peak concurrent requests:                500.00
Total Token throughput (tok/s):          17363.22
---------------Time to First Token----------------
Mean TTFT (ms):                          27600.49
Median TTFT (ms):                        29627.26
P99 TTFT (ms):                           56644.81
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          144.82
Median TPOT (ms):                        142.76
P99 TPOT (ms):                           250.18
---------------Inter-token Latency----------------
Mean ITL (ms):                           143.46
Median ITL (ms):                         57.80
P99 ITL (ms):                            145.06
==================================================

# random 128 input
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  6.21
Total input tokens:                      127881
Total generated tokens:                  4000
Request throughput (req/s):              161.01
Output token throughput (tok/s):         644.06
Peak output token throughput (tok/s):    1924.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          21234.81
---------------Time to First Token----------------
Mean TTFT (ms):                          3551.50
Median TTFT (ms):                        3313.50
P99 TTFT (ms):                           5528.41
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          800.25
Median TPOT (ms):                        936.39
P99 TPOT (ms):                           1413.56
---------------Inter-token Latency----------------
Mean ITL (ms):                           600.19
Median ITL (ms):                         0.01
P99 ITL (ms):                            3985.12
==================================================