跳转至

NVIDIA A100 GPUs 上的 GLM-4.5-Air 吞吐量优化

结论

glm-4.5-air-a100

GLM-4.5-Air 在 A100 GPUs 上的吞吐量优化推荐配置:

推理服务命令
python3 -m sglang.launch_server --model-path zai-org/GLM-4.5-Air \
--tp-size 4 --ep-size 4 --tool-call-parser glm --reasoning-parser glm45

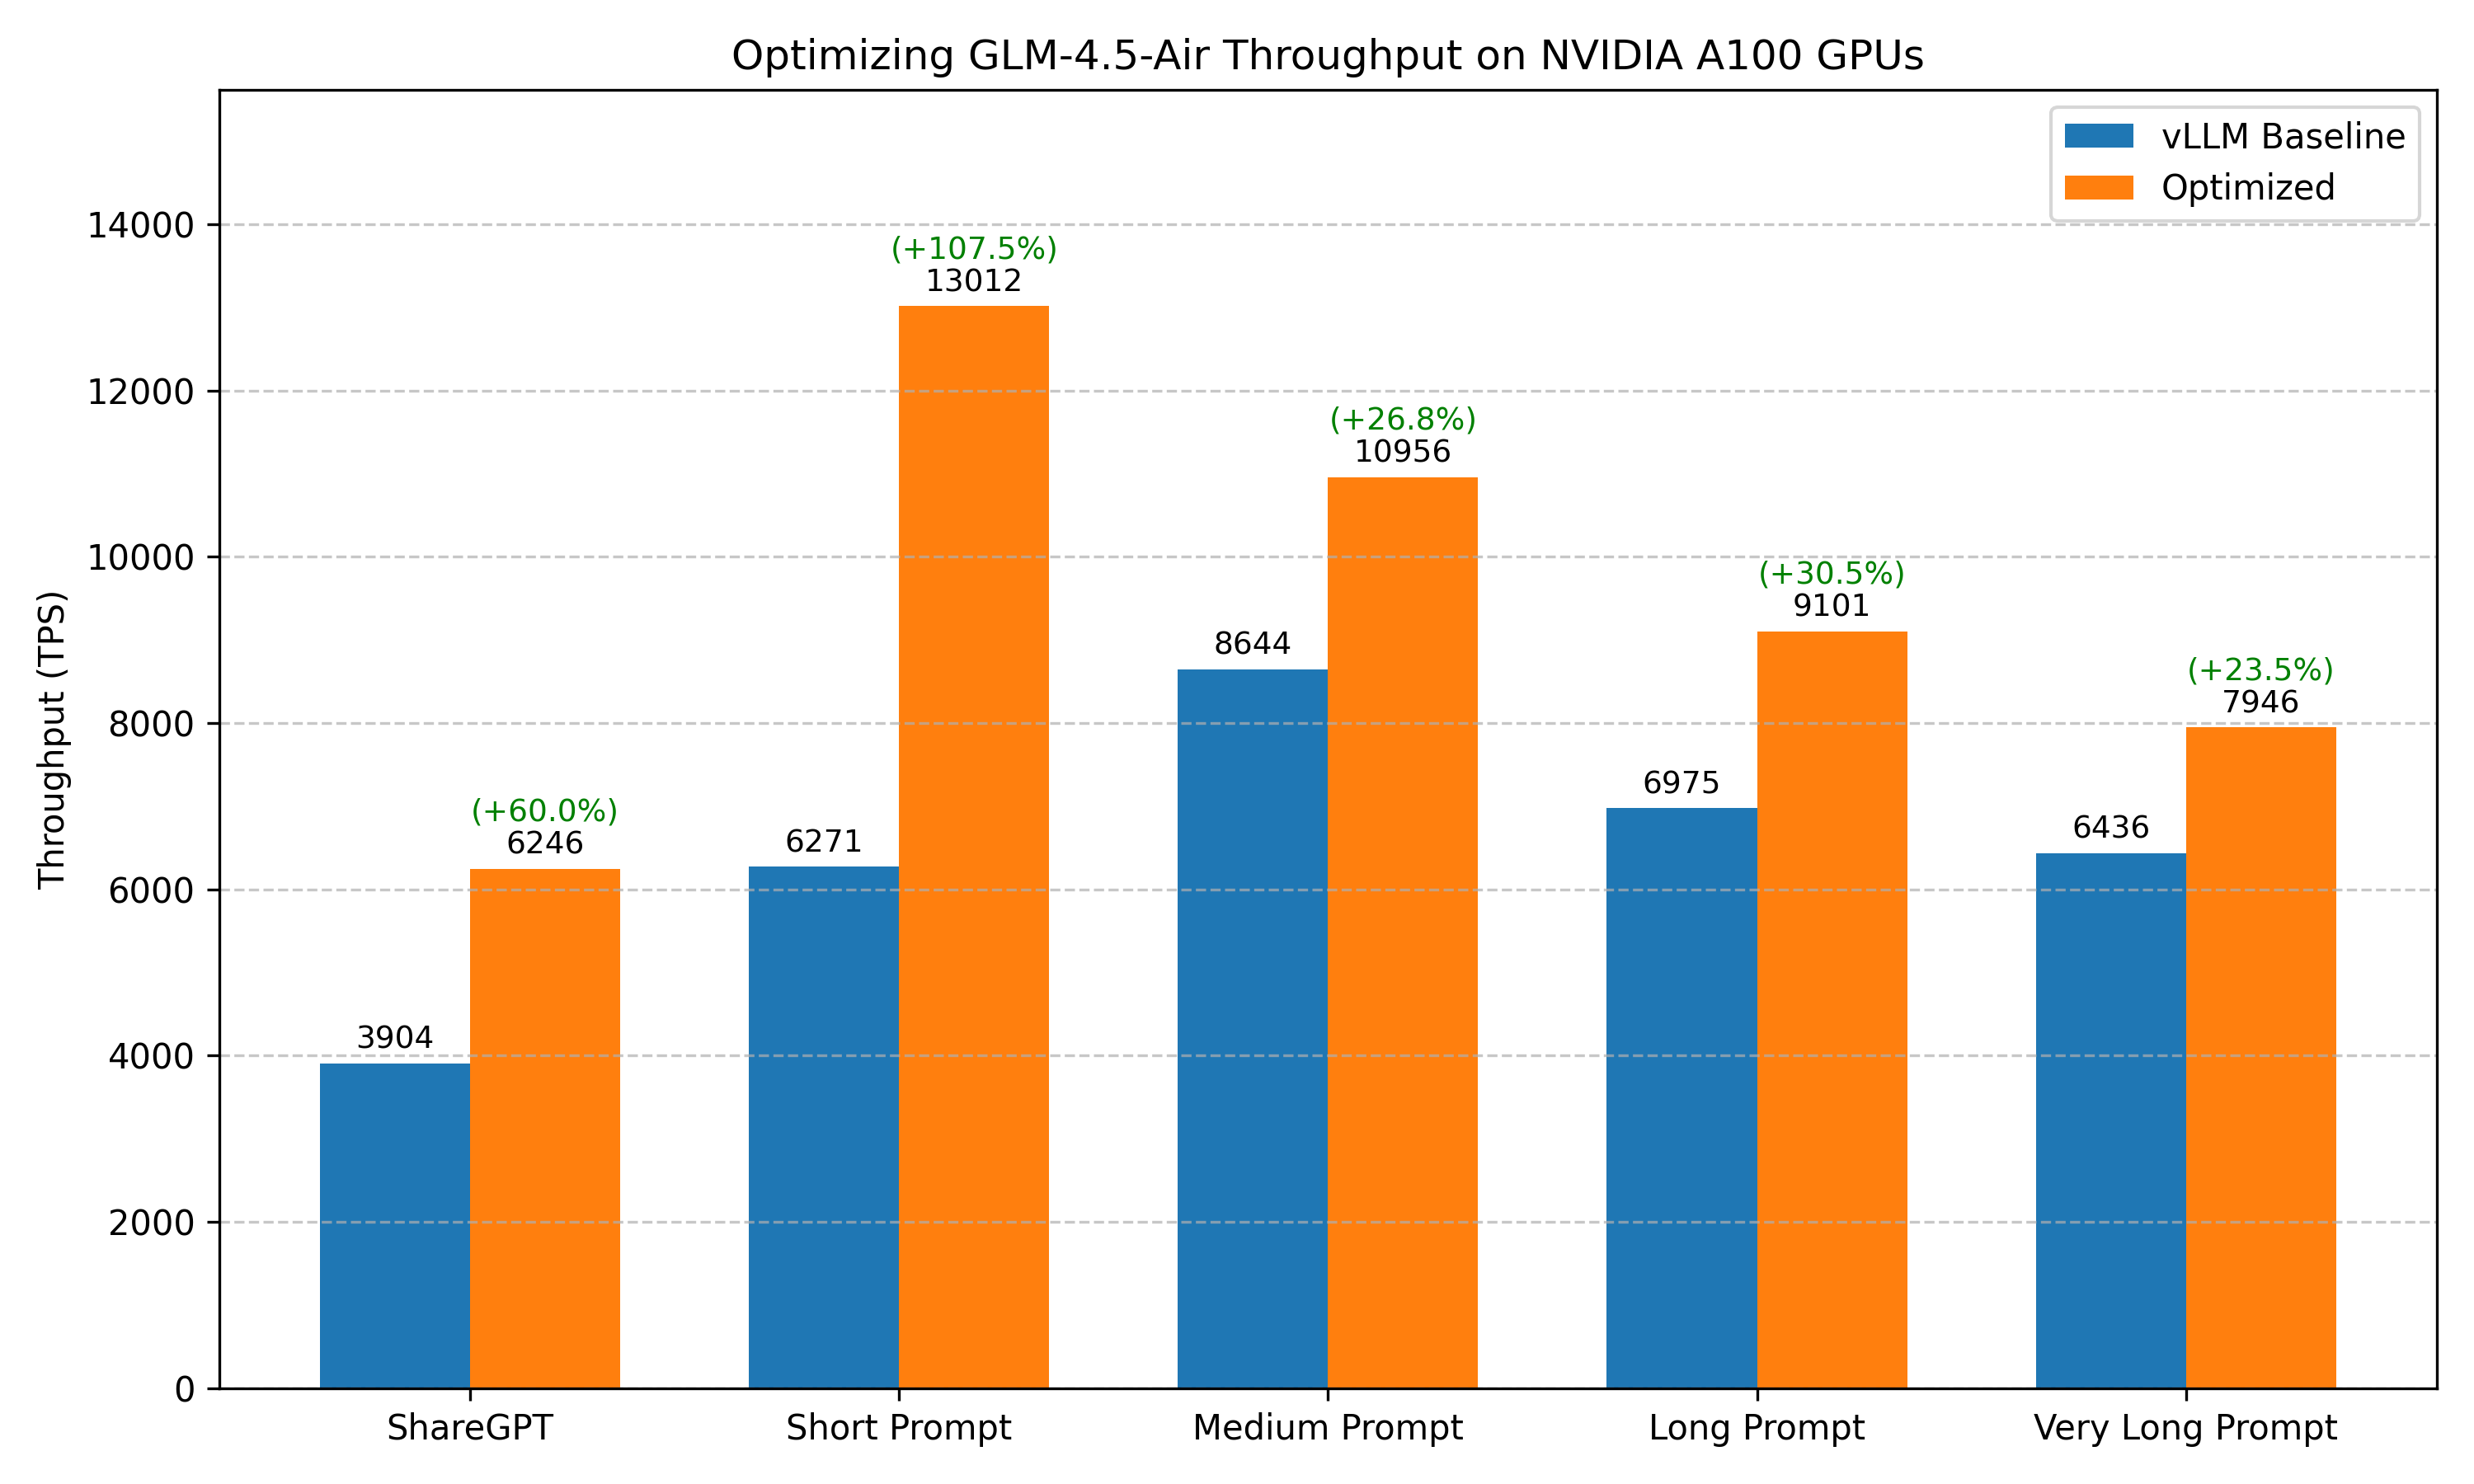
优化前后的基准测试结果对比:

基准测试用例 基准配置(未做任何优化的 vLLM) 优化后(换算为相同 GPU 数量)
ShareGPT Total TPS: 3903.44
Mean TPOT(ms): 104.59
Total TPS: 6245.77 (+60.0%)
Mean TPOT(ms): 309.31
短提示词 Total TPS: 6271.24
Mean TPOT(ms): 153.00
Total TPS: 13012.20 (+107.5%)
Mean TPOT(ms): 1246.57
中等长度提示词 Total TPS: 8643.75
Mean TPOT(ms): 204.31
Total TPS: 10956.49 (+26.8%)
Mean TPOT(ms): 165.34
长提示词 Total TPS: 6975.10
Mean TPOT(ms): 267.38
Total TPS: 9100.71 (+30.5%)
Mean TPOT(ms): 124.68
超长提示词 Total TPS: 6435.97
Mean TPOT(ms): 305.47
Total TPS: 7945.66 (+23.5%)
Mean TPOT(ms): 276.41

说明

  1. 基准测试未覆盖所有可能的优化组合。例如,我们会选择默认配置下表现最好的推理引擎作为后续调优的起点。这种剪枝方式得到的是局部最优解,未必是全局最优解。
  2. 其他优化方法取决于具体使用场景,包括最大批大小、调度配置、扩展 KV cache、CUDA graph 等。本文结论可作为进一步针对性优化的起点。
  3. 测试基于特定的硬件和软件环境。推理引擎的改进可能带来新的结论。

如有遗漏或需要根据最新变化更新的内容,请告诉我们。

优化目标

在高并发请求场景下实现高吞吐量。

实验环境

模型

zai-org/GLM-4.5-Air

硬件

单节点配备 4 × NVIDIA A100 SXM 80GB GPU。

引擎版本

  • vLLM: v0.11.0
  • SGLang: v0.5.4.post2
  • TensorRT-LLM: v1.2.0rc1

基准测试数据集

  1. ShareGPT
  2. 不同序列长度的随机数据集:
    • 超长提示词:32000 输入 tokens,100 输出 tokens
    • 长提示词:4000 输入 tokens,200 输出 tokens
    • 中等长度提示词:2000 输入 tokens,100 输出 tokens
    • 短提示词:128 输入 tokens,4 输出 tokens

基准测试脚本

使用 vLLM bench CLI 工具对模型性能进行基准测试。运行基准测试的命令如下:

1
2
3
4
5
6
7
8
# Prepare the ShareGPT dataset
wget https://huggingface.co/datasets/anon8231489123/ShareGPT_Vicuna_unfiltered/resolve/main/ShareGPT_V3_unfiltered_cleaned_split.json

# Benchmark on ShareGPT dataset
vllm bench serve --model zai-org/GLM-4.5-Air --backend openai-chat --endpoint /v1/chat/completions --dataset-name sharegpt --dataset-path ShareGPT_V3_unfiltered_cleaned_split.json --num-prompts 1000

# Benchmark on random dataset (fixed seed for reproducibility)
vllm bench serve --model zai-org/GLM-4.5-Air --backend openai-chat --endpoint /v1/chat/completions --dataset-name random --random-input-len 4000 --random-output-len 200 --num-prompts 500 --seed 42

实验结果

1. 选择推理引擎

vLLM

推理服务脚本
vllm serve zai-org/GLM-4.5-Air -tp 4
基准测试结果
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  106.15
Total input tokens:                      214465
Total generated tokens:                  199904
Request throughput (req/s):              9.42
Output token throughput (tok/s):         1883.14
Peak output token throughput (tok/s):    3380.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          3903.44
---------------Time to First Token----------------
Mean TTFT (ms):                          38971.22
Median TTFT (ms):                        37502.20
P99 TTFT (ms):                           76635.16
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          104.59
Median TPOT (ms):                        101.18
P99 TPOT (ms):                           210.38
---------------Inter-token Latency----------------
Mean ITL (ms):                           91.67
Median ITL (ms):                         87.56
P99 ITL (ms):                            178.94
==================================================
SGLang

推理服务脚本
python3 -m sglang.launch_server --model-path zai-org/GLM-4.5-Air --tp-size 4
基准测试结果
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  67.25
Total input tokens:                      214465
Total generated tokens:                  199873
Request throughput (req/s):              14.87
Output token throughput (tok/s):         2971.88
Peak output token throughput (tok/s):    11709.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          6160.72
---------------Time to First Token----------------
Mean TTFT (ms):                          14772.52
Median TTFT (ms):                        14625.90
P99 TTFT (ms):                           22760.64
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          328.21
Median TPOT (ms):                        129.31
P99 TPOT (ms):                           2061.59
---------------Inter-token Latency----------------
Mean ITL (ms):                           109.79
Median ITL (ms):                         67.14
P99 ITL (ms):                            411.08
==================================================

结果:SGLang(6160.72 tok/s) > vLLM (3903.44 tok/s) > TensorRT-LLM (不支持)

2. SGLang 中的 量化

FP8

推理服务脚本
python3 -m sglang.launch_server --model zai-org/GLM-4.5-Air-FP8 --tp-size 4
基准测试结果
# Crash. FP8 not supported on A100

3. SGLang 中的 并行策略

PP4

推理服务脚本
python3 -m sglang.launch_server --model zai-org/GLM-4.5-Air --pp-size 8
基准测试结果
# Crash. PP not supported for this setup.

TP4+EP4

推理服务脚本
python3 -m sglang.launch_server --model-path zai-org/GLM-4.5-Air  --tp-size 4 --ep-size 4
基准测试结果
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  66.34
Total input tokens:                      214465
Total generated tokens:                  199904
Request throughput (req/s):              15.07
Output token throughput (tok/s):         3013.15
Peak output token throughput (tok/s):    9933.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          6245.77
---------------Time to First Token----------------
Mean TTFT (ms):                          8445.43
Median TTFT (ms):                        8321.65
P99 TTFT (ms):                           15245.84
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          309.31
Median TPOT (ms):                        130.15
P99 TPOT (ms):                           1969.56
---------------Inter-token Latency----------------
Mean ITL (ms):                           112.44
Median ITL (ms):                         75.24
P99 ITL (ms):                            484.22
==================================================

4. SGLang 中的 注意力后端

在此配置下,SGLang 的默认注意力后端为 flashinfer。

triton

推理服务脚本
python3 -m sglang.launch_server --model-path zai-org/GLM-4.5-Air  --tp-size 4 --ep-size 4 --attention-backend triton
基准测试结果
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  68.84
Total input tokens:                      214465
Total generated tokens:                  199904
Request throughput (req/s):              14.53
Output token throughput (tok/s):         2904.08
Peak output token throughput (tok/s):    9443.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          6019.69
---------------Time to First Token----------------
Mean TTFT (ms):                          9348.81
Median TTFT (ms):                        9050.60
P99 TTFT (ms):                           17294.26
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          373.94
Median TPOT (ms):                        141.96
P99 TPOT (ms):                           2701.08
---------------Inter-token Latency----------------
Mean ITL (ms):                           120.58
Median ITL (ms):                         74.19
P99 ITL (ms):                            413.30
==================================================

fa3

推理服务脚本
python3 -m sglang.launch_server --model-path zai-org/GLM-4.5-Air  --tp-size 4 --ep-size 4 --attention-backend fa3
基准测试结果
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  67.66
Total input tokens:                      214465
Total generated tokens:                  199904
Request throughput (req/s):              14.78
Output token throughput (tok/s):         2954.39
Peak output token throughput (tok/s):    8239.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          6123.98
---------------Time to First Token----------------
Mean TTFT (ms):                          8260.21
Median TTFT (ms):                        8222.20
P99 TTFT (ms):                           15115.68
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          310.40
Median TPOT (ms):                        133.38
P99 TPOT (ms):                           2082.45
---------------Inter-token Latency----------------
Mean ITL (ms):                           114.41
Median ITL (ms):                         78.46
P99 ITL (ms):                            397.40
==================================================

5. SGLang 中的 CUDA Graph 调优

推理服务脚本
python3 -m sglang.launch_server --model-path zai-org/GLM-4.5-Air  --tp-size 4 --ep-size 4 --cuda-graph-max-bs 512
基准测试结果
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  66.38
Total input tokens:                      214465
Total generated tokens:                  199904
Request throughput (req/s):              15.06
Output token throughput (tok/s):         3011.43
Peak output token throughput (tok/s):    10146.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          6242.21
---------------Time to First Token----------------
Mean TTFT (ms):                          8458.72
Median TTFT (ms):                        8006.49
P99 TTFT (ms):                           15322.87
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          311.99
Median TPOT (ms):                        131.91
P99 TPOT (ms):                           1946.11
---------------Inter-token Latency----------------
Mean ITL (ms):                           112.67
Median ITL (ms):                         73.66
P99 ITL (ms):                            516.14
==================================================

优化选项汇总

优化选项 吞吐量提升
引擎选择 +57.8%
量化 -
并行策略 +1.4%
注意力后端 -
CUDA Graph 调优 -

其他基准测试用例

我们进一步对优化后的配置进行了基准测试,评估其在不同工作负载下的泛化表现。

基准配置的推理服务脚本
vllm serve zai-org/GLM-4.5-Air -tp 4
基准配置的测试结果
# random 32K input
============ Serving Benchmark Result ============
Successful requests:                     100
Benchmark duration (s):                  498.76
Total input tokens:                      3200000
Total generated tokens:                  9987
Request throughput (req/s):              0.20
Output token throughput (tok/s):         20.02
Peak output token throughput (tok/s):    218.00
Peak concurrent requests:                100.00
Total Token throughput (tok/s):          6435.97
---------------Time to First Token----------------
Mean TTFT (ms):                          248013.29
Median TTFT (ms):                        248015.97
P99 TTFT (ms):                           491884.32
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          305.47
Median TPOT (ms):                        317.93
P99 TPOT (ms):                           319.14
---------------Inter-token Latency----------------
Mean ITL (ms):                           303.40
Median ITL (ms):                         309.84
P99 ITL (ms):                            406.26
==================================================

# random 4K input
============ Serving Benchmark Result ============
Successful requests:                     500
Benchmark duration (s):                  300.98
Total input tokens:                      1999787
Total generated tokens:                  99547
Request throughput (req/s):              1.66
Output token throughput (tok/s):         330.75
Peak output token throughput (tok/s):    1743.00
Peak concurrent requests:                500.00
Total Token throughput (tok/s):          6975.10
---------------Time to First Token----------------
Mean TTFT (ms):                          142573.31
Median TTFT (ms):                        141422.49
P99 TTFT (ms):                           289825.31
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          267.38
Median TPOT (ms):                        295.72
P99 TPOT (ms):                           300.72
---------------Inter-token Latency----------------
Mean ITL (ms):                           266.48
Median ITL (ms):                         295.37
P99 ITL (ms):                            307.18
==================================================

# random 2K input
============ Serving Benchmark Result ============
Successful requests:                     500
Benchmark duration (s):                  121.41
Total input tokens:                      999429
Total generated tokens:                  50000
Request throughput (req/s):              4.12
Output token throughput (tok/s):         411.83
Peak output token throughput (tok/s):    1796.00
Peak concurrent requests:                500.00
Total Token throughput (tok/s):          8643.75
---------------Time to First Token----------------
Mean TTFT (ms):                          60300.00
Median TTFT (ms):                        60039.46
P99 TTFT (ms):                           116422.28
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          204.31
Median TPOT (ms):                        224.99
P99 TPOT (ms):                           225.56
---------------Inter-token Latency----------------
Mean ITL (ms):                           202.57
Median ITL (ms):                         224.72
P99 ITL (ms):                            230.94
==================================================

# random 128 input
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  21.03
Total input tokens:                      127881
Total generated tokens:                  4000
Request throughput (req/s):              47.55
Output token throughput (tok/s):         190.21
Peak output token throughput (tok/s):    952.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          6271.24
---------------Time to First Token----------------
Mean TTFT (ms):                          16583.77
Median TTFT (ms):                        16009.09
P99 TTFT (ms):                           20726.61
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          153.00
Median TPOT (ms):                        153.83
P99 TPOT (ms):                           173.39
---------------Inter-token Latency----------------
Mean ITL (ms):                           114.74
Median ITL (ms):                         153.44
P99 ITL (ms):                            192.15
==================================================
优化后的推理服务脚本
python3 -m sglang.launch_server --model GLM-4.5-Air --tp-size 4 --ep-size 4 \
    --tool-call-parser glm --reasoning-parser glm45
优化后的测试结果
# random 32K input
============ Serving Benchmark Result ============
Successful requests:                     100
Benchmark duration (s):                  403.99
Total input tokens:                      3200000
Total generated tokens:                  9931
Request throughput (req/s):              0.25
Output token throughput (tok/s):         24.58
Peak output token throughput (tok/s):    332.00
Peak concurrent requests:                100.00
Total Token throughput (tok/s):          7945.66
---------------Time to First Token----------------
Mean TTFT (ms):                          200446.56
Median TTFT (ms):                        199894.57
P99 TTFT (ms):                           397275.29
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          276.41
Median TPOT (ms):                        295.02
P99 TPOT (ms):                           410.95
---------------Inter-token Latency----------------
Mean ITL (ms):                           271.13
Median ITL (ms):                         32.39
P99 ITL (ms):                            3555.22
==================================================

# random 4K input
============ Serving Benchmark Result ============
Successful requests:                     500
Benchmark duration (s):                  230.67
Total input tokens:                      1999787
Total generated tokens:                  99437
Request throughput (req/s):              2.17
Output token throughput (tok/s):         431.09
Peak output token throughput (tok/s):    1680.00
Peak concurrent requests:                500.00
Total Token throughput (tok/s):          9100.71
---------------Time to First Token----------------
Mean TTFT (ms):                          109316.41
Median TTFT (ms):                        113614.39
P99 TTFT (ms):                           222368.09
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          124.68
Median TPOT (ms):                        124.45
P99 TPOT (ms):                           179.33
---------------Inter-token Latency----------------
Mean ITL (ms):                           123.34
Median ITL (ms):                         59.70
P99 ITL (ms):                            294.40
==================================================

# random 2K input
============ Serving Benchmark Result ============
Successful requests:                     500
Benchmark duration (s):                  95.78
Total input tokens:                      999429
Total generated tokens:                  49964
Request throughput (req/s):              5.22
Output token throughput (tok/s):         521.66
Peak output token throughput (tok/s):    3160.00
Peak concurrent requests:                500.00
Total Token throughput (tok/s):          10956.49
---------------Time to First Token----------------
Mean TTFT (ms):                          45224.78
Median TTFT (ms):                        44492.00
P99 TTFT (ms):                           91909.36
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          165.34
Median TPOT (ms):                        163.74
P99 TPOT (ms):                           281.83
---------------Inter-token Latency----------------
Mean ITL (ms):                           162.06
Median ITL (ms):                         63.35
P99 ITL (ms):                            166.19
==================================================

# random 128 input
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  10.14
Total input tokens:                      127881
Total generated tokens:                  4000
Request throughput (req/s):              98.67
Output token throughput (tok/s):         394.66
Peak output token throughput (tok/s):    2166.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          13012.20
---------------Time to First Token----------------
Mean TTFT (ms):                          5882.75
Median TTFT (ms):                        5678.55
P99 TTFT (ms):                           9321.13
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          1246.57
Median TPOT (ms):                        1420.02
P99 TPOT (ms):                           2379.65
---------------Inter-token Latency----------------
Mean ITL (ms):                           747.94
Median ITL (ms):                         59.22
P99 ITL (ms):                            6782.02
==================================================