Ana içeriğe geç

NVIDIA A100 GPU üzerinde Qwen3-235B-A22B işlem hacmi optimizasyonu

Sonuç

qwen3-235b-a22b-a100

A100 GPU üzerinde Qwen3-235B-A22B-Instruct-2507 işlem hacmini optimize etmek için önerilen yapılandırma:

Model sunum komutu
vllm serve Qwen/Qwen3-235B-A22B-Instruct-2507-FP8 -tp 4

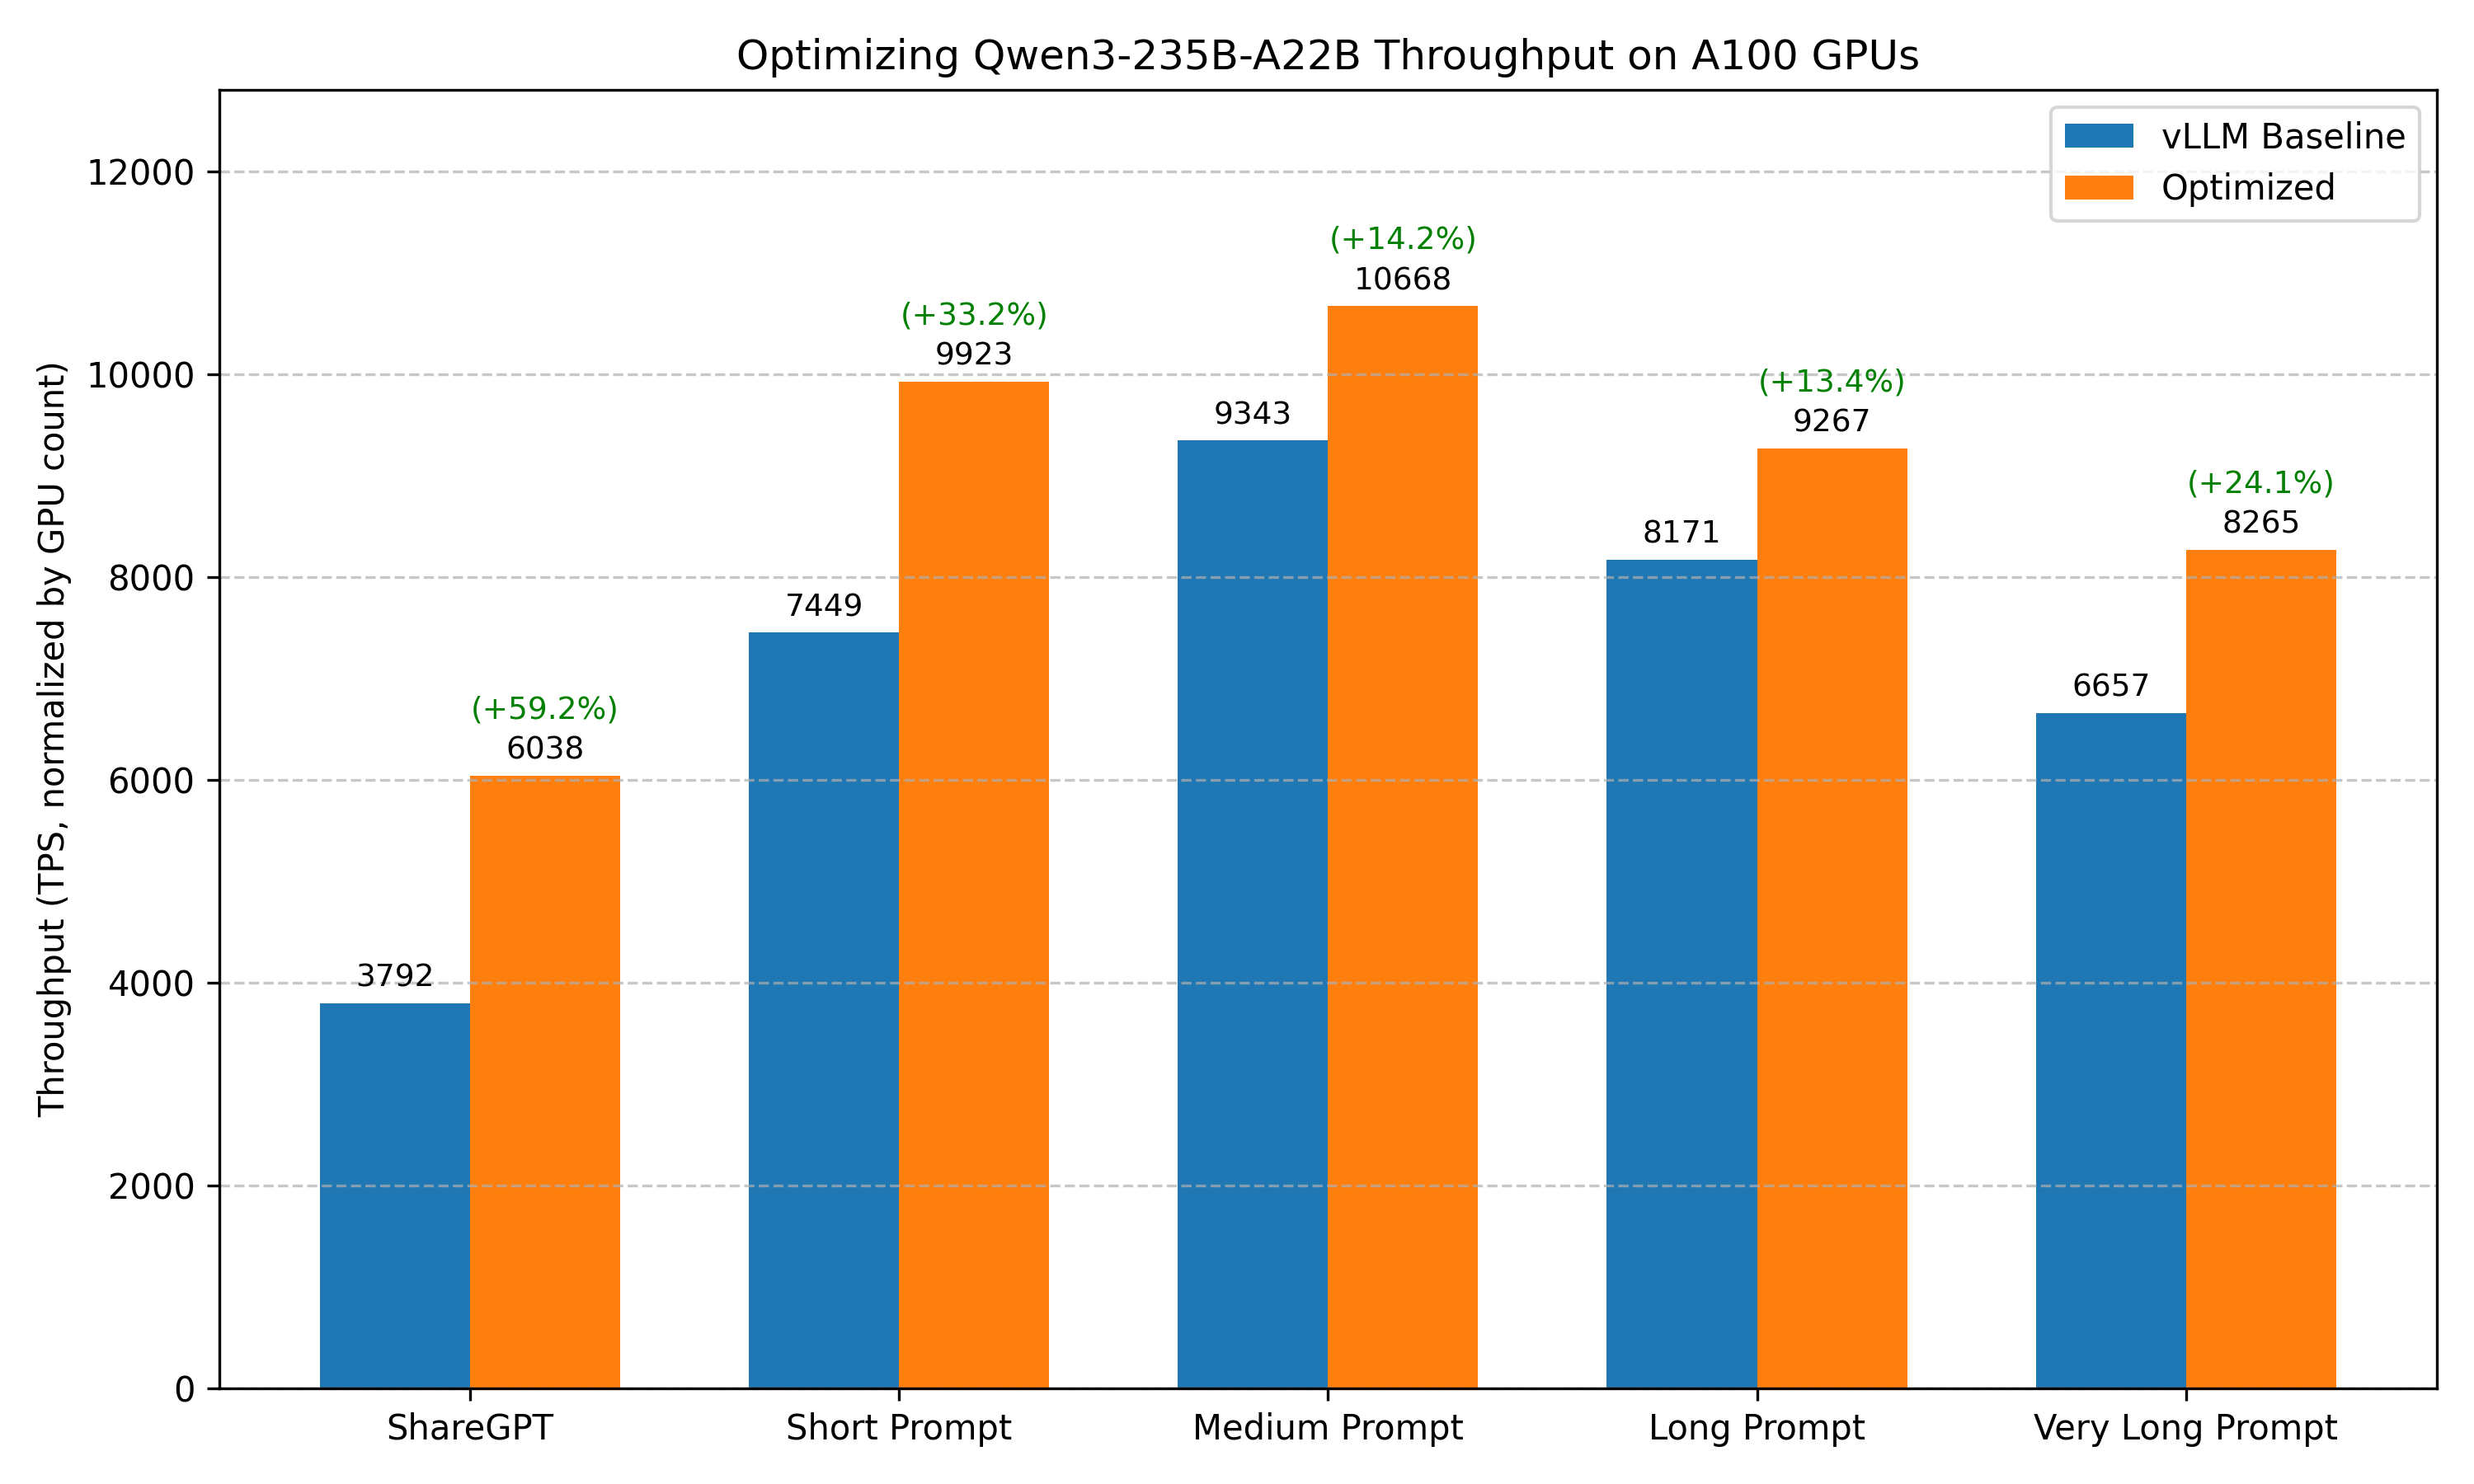
Optimizasyon öncesi ve sonrası benchmark sonuçlarının karşılaştırması:

Benchmark senaryosu temel yapılandırma (optimizasyonsuz vLLM) Optimize edilmiş
ShareGPT Toplam TPS: 3792.50
Ortalama TPOT(ms): 123.36
Toplam TPS: 3019.19x2 (+59.2%)
Ortalama TPOT(ms): 150.72
Kısa istem Toplam TPS: 7449.43
Ortalama TPOT(ms): 155.16
Toplam TPS: 4961.66x2 (+33.2%)
Ortalama TPOT(ms): 265.87
Orta uzunlukta istem Toplam TPS: 9342.67
Ortalama TPOT(ms): 190.79
Toplam TPS: 5333.91x2 (+14.2%)
Ortalama TPOT(ms): 342.39
Uzun istem Toplam TPS: 8170.72
Ortalama TPOT(ms): 205.64
Toplam TPS: 4633.41x2 (+13.4%)
Ortalama TPOT(ms): 347.13
Çok uzun istem Toplam TPS: 6657.49
Ortalama TPOT(ms): 298.86
Toplam TPS: 4132.51x2 (+24.1%)
Ortalama TPOT(ms): 481.71

Not

  1. Benchmark testlerimiz olası tüm optimizasyon birleşimlerini kapsamaz. Örneğin, varsayılan yapılandırmasında en iyi performansı gösteren çıkarım motorunu sonraki ayarlamalar için başlangıç noktası olarak seçeriz. Bu eleme yaklaşımı yerel bir optimum verir; bu, genel optimum olmayabilir.
  2. En büyük toplu iş boyutu, zamanlama yapılandırması, genişletilmiş KV önbelleği, CUDA graph, Torch Compile gibi belirli kullanım senaryolarına bağlı başka optimizasyonlar da vardır. Bu belgedeki sonuçlar, daha hedefli optimizasyonlar için başlangıç noktası olabilir.
  3. Testler belirli donanım ve yazılım yapılandırmalarında yürütülmüştür. Çıkarım motorlarındaki gelişmeler sonuçları değiştirebilir.
  4. Nicemleme doğruluğu etkileyebilir; ancak FP8 nicemleme çoğu modelde %1'den az doğruluk kaybı sağlayabilir. Ayrıntılar için değerlendirme sonuçlarına bakın. Bu nedenle yüksek işlem hacimli sunum senaryolarında FP8 nicemleme önemle önerilir.

Eksik noktalar veya yeni değişiklikleri yansıtacak güncellemeler varsa bize bildirin.

Optimizasyon hedefi

Yüksek eş zamanlı isteklerde yüksek işlem hacmi sağlar.

Deney kurulumu

Model

Qwen3-235B-A22B-Instruct-2507

Donanım

Tek düğümde 8 × NVIDIA A100 SXM 80GB GPU.

Motor sürümü

  • vLLM: v0.11.0
  • SGLang: v0.5.5.post1

Benchmark veri kümesi

  1. ShareGPT
  2. Farklı dizi uzunluklarına sahip rastgele veri kümesi:
    • Çok uzun istem: 32000 giriş token'ı, 100 çıkış token'ı
    • Uzun istem: 4000 giriş token'ı, 200 çıkış token'ı
    • Orta uzunlukta istem: 2000 giriş token'ı, 100 çıkış token'ı
    • Kısa istem: 128 giriş token'ı, 4 çıkış token'ı

Benchmark betiği

Model performansını ölçmek için vLLM bench CLI aracını kullanıyoruz. Benchmark şu komutla çalıştırılır:

1
2
3
4
5
6
7
8
# Prepare the ShareGPT dataset
wget https://huggingface.co/datasets/anon8231489123/ShareGPT_Vicuna_unfiltered/resolve/main/ShareGPT_V3_unfiltered_cleaned_split.json

# Benchmark on ShareGPT dataset
vllm bench serve --model Qwen/Qwen3-235B-A22B-Instruct-2507 --backend openai-chat --endpoint /v1/chat/completions --dataset-name sharegpt --dataset-path ShareGPT_V3_unfiltered_cleaned_split.json --num-prompts 1000

# Benchmark on random dataset (fixed seed for reproducibility)
vllm bench serve --model Qwen/Qwen3-235B-A22B-Instruct-2507 --backend openai-chat --endpoint /v1/chat/completions --dataset-name random --random-input-len 4000 --random-output-len 200 --num-prompts 500 --seed 42

Deney sonuçları

1. Çıkarım motoru seçimi

vLLM

Model sunum betiği
vllm serve Qwen/Qwen3-235B-A22B-Instruct-2507 -tp 8
Benchmark sonucu
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  109.00
Total input tokens:                      217393
Total generated tokens:                  196004
Request throughput (req/s):              9.17
Output token throughput (tok/s):         1798.14
Peak output token throughput (tok/s):    3297.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          3792.50
---------------Time to First Token----------------
Mean TTFT (ms):                          38065.91
Median TTFT (ms):                        37597.63
P99 TTFT (ms):                           77082.58
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          123.36
Median TPOT (ms):                        103.68
P99 TPOT (ms):                           448.36
---------------Inter-token Latency----------------
Mean ITL (ms):                           100.76
Median ITL (ms):                         86.83
P99 ITL (ms):                            185.41
==================================================
SGLang

Model sunum betiği
python3 -m sglang.launch_server --model-path Qwen/Qwen3-235B-A22B-Instruct-2507 --tp-size 8
Benchmark sonucu
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  89.35
Total input tokens:                      217393
Total generated tokens:                  196763
Request throughput (req/s):              11.19
Output token throughput (tok/s):         2202.21
Peak output token throughput (tok/s):    4926.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          4635.31
---------------Time to First Token----------------
Mean TTFT (ms):                          21130.67
Median TTFT (ms):                        15483.85
P99 TTFT (ms):                           51960.77
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          235.10
Median TPOT (ms):                        163.74
P99 TPOT (ms):                           1171.03
---------------Inter-token Latency----------------
Mean ITL (ms):                           136.35
Median ITL (ms):                         86.55
P99 ITL (ms):                            500.15
==================================================

Sonuç: SGLang(4635.31 tok/s) > vLLM (3792.50 tok/s)

2. vLLM için Quantization

A100 GPU'larda FP8 nicemlemeli SGLang çalışmaz. vLLM, Marlin çekirdeğiyle A100 GPU'larda w8a16 nicemlemesini destekler.

vLLM FP8

Model sunum betiği
# TP8 only is not compatible for the model weight. Use EP as well.
vllm serve Qwen/Qwen3-235B-A22B-Instruct-2507-FP8 -tp 8 --enable-expert-parallel
Benchmark sonucu
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  110.68
Total input tokens:                      217393
Total generated tokens:                  196648
Request throughput (req/s):              9.04
Output token throughput (tok/s):         1776.73
Peak output token throughput (tok/s):    3106.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          3740.89
---------------Time to First Token----------------
Mean TTFT (ms):                          37366.87
Median TTFT (ms):                        35525.98
P99 TTFT (ms):                           78616.18
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          115.74
Median TPOT (ms):                        109.21
P99 TPOT (ms):                           228.96
---------------Inter-token Latency----------------
Mean ITL (ms):                           101.28
Median ITL (ms):                         91.72
P99 ITL (ms):                            235.47
==================================================

3. vLLM için Paralellik

TP4

Model sunum betiği
vllm serve Qwen/Qwen3-235B-A22B-Instruct-2507-FP8 -tp 4
Benchmark sonucu
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  136.64
Total input tokens:                      217393
Total generated tokens:                  195140
Request throughput (req/s):              7.32
Output token throughput (tok/s):         1428.16
Peak output token throughput (tok/s):    2852.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          3019.19
---------------Time to First Token----------------
Mean TTFT (ms):                          45879.29
Median TTFT (ms):                        43216.75
P99 TTFT (ms):                           99903.30
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          150.72
Median TPOT (ms):                        143.39
P99 TPOT (ms):                           297.17
---------------Inter-token Latency----------------
Mean ITL (ms):                           131.17
Median ITL (ms):                         119.69
P99 ITL (ms):                            311.46
==================================================

TP4 EP4

Model sunum betiği
vllm serve Qwen/Qwen3-235B-A22B-Instruct-2507-FP8 -tp 4 --enable-expert-parallel
Benchmark sonucu
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  146.74
Total input tokens:                      217393
Total generated tokens:                  195590
Request throughput (req/s):              6.81
Output token throughput (tok/s):         1332.94
Peak output token throughput (tok/s):    2501.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          2814.47
---------------Time to First Token----------------
Mean TTFT (ms):                          48930.06
Median TTFT (ms):                        45498.27
P99 TTFT (ms):                           106740.39
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          161.49
Median TPOT (ms):                        154.84
P99 TPOT (ms):                           329.32
---------------Inter-token Latency----------------
Mean ITL (ms):                           140.35
Median ITL (ms):                         128.38
P99 ITL (ms):                            340.60
==================================================

4. vLLM için Toplu işteki en fazla token sayısı

Model sunum betiği
vllm serve Qwen/Qwen3-235B-A22B-Instruct-2507-FP8 -tp 4 --max-num-batched-tokens 4096
Benchmark sonucu
# --max-num-batched-tokens 4096
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  136.64
Total input tokens:                      217393
Total generated tokens:                  195953
Request throughput (req/s):              7.32
Output token throughput (tok/s):         1434.07
Peak output token throughput (tok/s):    2784.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          3025.05
---------------Time to First Token----------------
Mean TTFT (ms):                          45389.84
Median TTFT (ms):                        41651.71
P99 TTFT (ms):                           98975.37
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          155.37
Median TPOT (ms):                        142.48
P99 TPOT (ms):                           509.56
---------------Inter-token Latency----------------
Mean ITL (ms):                           131.19
Median ITL (ms):                         114.03
P99 ITL (ms):                            395.26
==================================================

# --max-num-batched-tokens 8192
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  137.59
Total input tokens:                      217393
Total generated tokens:                  195781
Request throughput (req/s):              7.27
Output token throughput (tok/s):         1422.97
Peak output token throughput (tok/s):    2724.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          3003.01
---------------Time to First Token----------------
Mean TTFT (ms):                          45405.05
Median TTFT (ms):                        41603.31
P99 TTFT (ms):                           99900.26
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          157.10
Median TPOT (ms):                        143.37
P99 TPOT (ms):                           561.98
---------------Inter-token Latency----------------
Mean ITL (ms):                           132.24
Median ITL (ms):                         120.38
P99 ITL (ms):                            306.32
==================================================

Optimizasyon seçeneklerinin özeti

Optimizasyon seçeneği İşlem hacmi iyileşmesi
Motor seçimi +22.2%
Quantization -
Paralellik +59.2%
Dikkat arka ucu -
Toplu işteki en fazla token sayısı -

Diğer benchmark senaryoları

Optimize edilmiş yapılandırmanın farklı iş yüklerine genellenebilirliğini değerlendirmek için ek benchmark testleri yaptık.

Temel model sunum betiği
vllm serve Qwen/Qwen3-235B-A22B-Instruct-2507 -tp 8
Temel benchmark sonuçları
# random 32K input
============ Serving Benchmark Result ============
Successful requests:                     100
Benchmark duration (s):                  481.89
Total input tokens:                      3200000
Total generated tokens:                  8191
Request throughput (req/s):              0.21
Output token throughput (tok/s):         17.00
Peak output token throughput (tok/s):    140.00
Peak concurrent requests:                100.00
Total Token throughput (tok/s):          6657.49
---------------Time to First Token----------------
Mean TTFT (ms):                          240229.05
Median TTFT (ms):                        240137.10
P99 TTFT (ms):                           475251.39
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          298.86
Median TPOT (ms):                        307.94
P99 TPOT (ms):                           311.82
---------------Inter-token Latency----------------
Mean ITL (ms):                           295.13
Median ITL (ms):                         303.36
P99 ITL (ms):                            370.10
==================================================

# random 4K input
============ Serving Benchmark Result ============
Successful requests:                     500
Benchmark duration (s):                  255.70
Total input tokens:                      1997942
Total generated tokens:                  91352
Request throughput (req/s):              1.96
Output token throughput (tok/s):         357.26
Peak output token throughput (tok/s):    1403.00
Peak concurrent requests:                500.00
Total Token throughput (tok/s):          8170.72
---------------Time to First Token----------------
Mean TTFT (ms):                          122190.64
Median TTFT (ms):                        121615.01
P99 TTFT (ms):                           244882.42
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          205.64
Median TPOT (ms):                        220.33
P99 TPOT (ms):                           237.80
---------------Inter-token Latency----------------
Mean ITL (ms):                           204.69
Median ITL (ms):                         239.57
P99 ITL (ms):                            246.21
==================================================

# random 2K input
============ Serving Benchmark Result ============
Successful requests:                     500
Benchmark duration (s):                  112.15
Total input tokens:                      998175
Total generated tokens:                  49632
Request throughput (req/s):              4.46
Output token throughput (tok/s):         442.54
Peak output token throughput (tok/s):    1691.00
Peak concurrent requests:                500.00
Total Token throughput (tok/s):          9342.67
---------------Time to First Token----------------
Mean TTFT (ms):                          54722.50
Median TTFT (ms):                        54532.60
P99 TTFT (ms):                           106756.03
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          190.79
Median TPOT (ms):                        208.61
P99 TPOT (ms):                           209.09
---------------Inter-token Latency----------------
Mean ITL (ms):                           189.23
Median ITL (ms):                         208.52
P99 ITL (ms):                            211.58
==================================================

# random 128 input
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  17.68
Total input tokens:                      127698
Total generated tokens:                  4000
Request throughput (req/s):              56.56
Output token throughput (tok/s):         226.26
Peak output token throughput (tok/s):    948.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          7449.43
---------------Time to First Token----------------
Mean TTFT (ms):                          12767.63
Median TTFT (ms):                        12409.68
P99 TTFT (ms):                           17339.37
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          155.16
Median TPOT (ms):                        158.22
P99 TPOT (ms):                           168.04
---------------Inter-token Latency----------------
Mean ITL (ms):                           116.37
Median ITL (ms):                         157.64
P99 ITL (ms):                            179.04
==================================================
Optimize edilmiş model sunum betiği
vllm serve Qwen/Qwen3-235B-A22B-Instruct-2507-FP8 -tp 4
Optimize edilmiş benchmark sonuçları
# random 32K input
============ Serving Benchmark Result ============
Successful requests:                     100
Benchmark duration (s):                  776.36
Total input tokens:                      3200000
Total generated tokens:                  8300
Request throughput (req/s):              0.13
Output token throughput (tok/s):         10.69
Peak output token throughput (tok/s):    152.00
Peak concurrent requests:                100.00
Total Token throughput (tok/s):          4132.51
---------------Time to First Token----------------
Mean TTFT (ms):                          387908.55
Median TTFT (ms):                        387968.52
P99 TTFT (ms):                           766523.82
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          481.71
Median TPOT (ms):                        496.29
P99 TPOT (ms):                           513.27
---------------Inter-token Latency----------------
Mean ITL (ms):                           476.10
Median ITL (ms):                         490.85
P99 ITL (ms):                            612.03
==================================================

# random 4K input
============ Serving Benchmark Result ============
Successful requests:                     500
Benchmark duration (s):                  450.71
Total input tokens:                      1997942
Total generated tokens:                  90389
Request throughput (req/s):              1.11
Output token throughput (tok/s):         200.55
Peak output token throughput (tok/s):    1066.00
Peak concurrent requests:                500.00
Total Token throughput (tok/s):          4633.41
---------------Time to First Token----------------
Mean TTFT (ms):                          216485.01
Median TTFT (ms):                        215365.76
P99 TTFT (ms):                           436587.02
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          347.13
Median TPOT (ms):                        371.93
P99 TPOT (ms):                           412.29
---------------Inter-token Latency----------------
Mean ITL (ms):                           344.46
Median ITL (ms):                         425.81
P99 ITL (ms):                            436.76
==================================================

# random 2K input
============ Serving Benchmark Result ============
Successful requests:                     500
Benchmark duration (s):                  196.42
Total input tokens:                      998175
Total generated tokens:                  49495
Request throughput (req/s):              2.55
Output token throughput (tok/s):         251.99
Peak output token throughput (tok/s):    1116.00
Peak concurrent requests:                500.00
Total Token throughput (tok/s):          5333.91
---------------Time to First Token----------------
Mean TTFT (ms):                          95261.76
Median TTFT (ms):                        94982.78
P99 TTFT (ms):                           189238.63
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          342.39
Median TPOT (ms):                        376.64
P99 TPOT (ms):                           377.99
---------------Inter-token Latency----------------
Mean ITL (ms):                           339.59
Median ITL (ms):                         376.62
P99 ITL (ms):                            380.69
==================================================

# random 128 input
============ Serving Benchmark Result ============
Successful requests:                     1000
Benchmark duration (s):                  26.54
Total input tokens:                      127698
Total generated tokens:                  4000
Request throughput (req/s):              37.67
Output token throughput (tok/s):         150.70
Peak output token throughput (tok/s):    311.00
Peak concurrent requests:                1000.00
Total Token throughput (tok/s):          4961.66
---------------Time to First Token----------------
Mean TTFT (ms):                          17260.17
Median TTFT (ms):                        17240.71
P99 TTFT (ms):                           26154.32
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms):                          265.87
Median TPOT (ms):                        272.95
P99 TPOT (ms):                           278.77
---------------Inter-token Latency----------------
Mean ITL (ms):                           199.40
Median ITL (ms):                         272.50
P99 ITL (ms):                            288.23
==================================================