ASCEND 910B NPU 上での Qwen3-8B のスループット最適化 結論
ASCEND 910B NPU 上で Qwen3-8B のスループットを最適化するための推奨設定:
推論サービスのコマンド # This is a simplified vLLM-like command. GPUStack maps arguments to the
# corresponding MindIE JSON configuration and runs with mindieservice_daemon.
serve vllm-ascend/Qwen3-8B-W8A8 --enable-prefix-caching
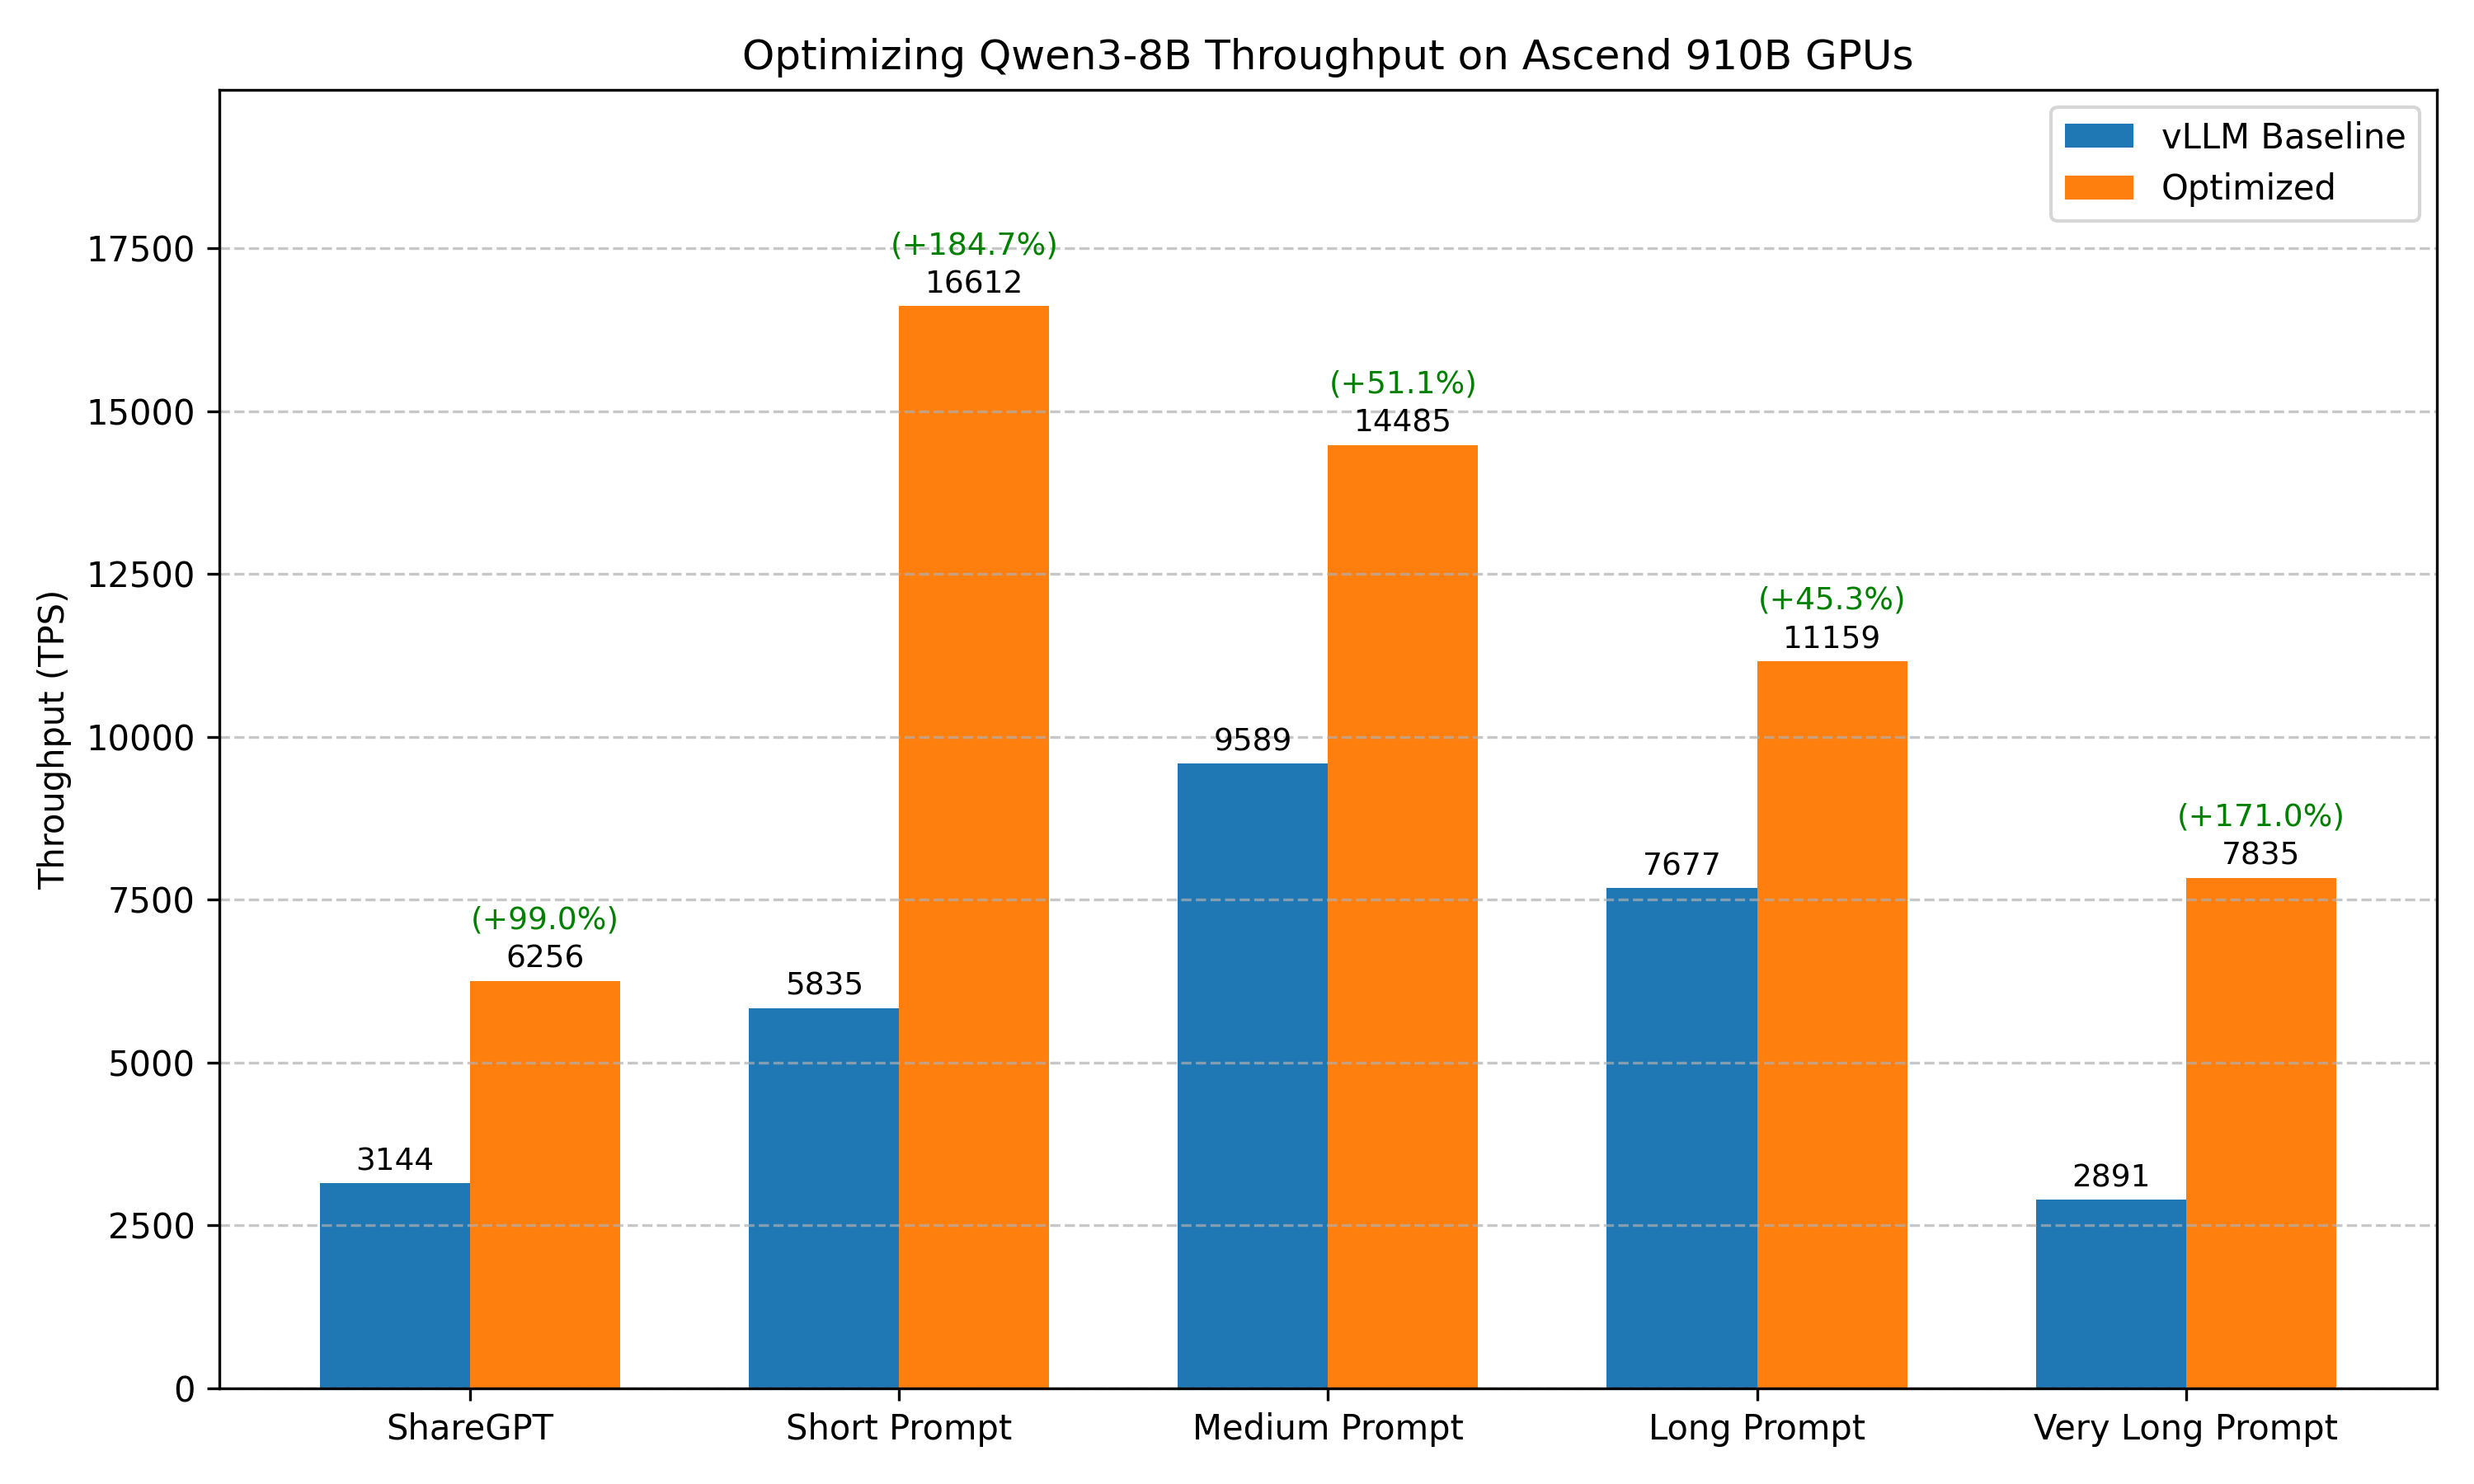
最適化前後のベンチマーク結果の比較:
ベンチマークケース 基準設定(最適化なしの vLLM) 最適化後 ShareGPT 合計 TPS: 3143.94 合計 TPS: 6256.39 (+99.0%) 短いプロンプト 合計 TPS: 5834.79 合計 TPS: 16611.86 (+184.7%) 中程度のプロンプト 合計 TPS: 9589.00 合計 TPS: 14484.86 (+51.1%) 長いプロンプト 合計 TPS: 7677.41 合計 TPS: 11159.01 (+45.4%) 非常に長いプロンプト 合計 TPS: 2890.64 合計 TPS: 7835.01 (+171.1%)
注記
本ベンチマークは、考えられるすべての最適化の組み合わせを網羅していません。たとえば、デフォルト設定で最も性能が高い推論エンジンを選び、それを追加調整の出発点としています。このような候補の絞り込みで得られるのは局所最適解であり、大域最適解とは限りません。 最大バッチサイズ、スケジューリング設定、拡張 KV キャッシュ、CUDA graph、Torch Compile など、利用シナリオに応じた最適化もあります。本書の結論は、用途に合わせてさらに最適化するための出発点として利用できます。 本テストは特定のハードウェアとソフトウェアの構成で実施しています。推論エンジンの進化により、結論が変わる可能性があります。 記載漏れや最新の変更を反映すべき点があれば、お知らせください 。
最適化の目標 高並列度のリクエストで高スループットを実現します。
実験環境 モデル Qwen/Qwen3-30B-A3B
ハードウェア 単一の Ascend 910B NPU。
エンジンのバージョン vLLM-Ascend: v0.9.1 MindIE: 2.1RC1 ベンチマークデータセット ShareGPT シーケンス長を変えたランダムデータセット: 非常に長いプロンプト: 32000 入力トークン, 100 出力トークン 長いプロンプト: 4000 入力トークン, 200 出力トークン 中程度のプロンプト: 2000 入力トークン, 100 出力トークン 短いプロンプト: 128 入力トークン, 4 出力トークン ベンチマークスクリプト モデルの性能評価には vLLM bench CLI ツールを使用します。ベンチマークを実行するコマンドは次のとおりです:
# Prepare the ShareGPT dataset
https://huggingface.co/datasets/anon8231489123/ShareGPT_Vicuna_unfiltered/resolve/main/ShareGPT_V3_unfiltered_cleaned_split.json
# Benchmark on ShareGPT dataset
bench serve --model Qwen/Qwen3-8B --backend openai-chat --endpoint /v1/chat/completions --dataset-name sharegpt --dataset-path ShareGPT_V3_unfiltered_cleaned_split.json --num-prompts 1000
# Benchmark on random dataset (fixed seed for reproducibility)
bench serve --model Qwen/Qwen3-8B --backend openai-chat --endpoint /v1/chat/completions --dataset-name random --random-input-len 4000 --random-output-len 200 --num-prompts 500 --seed 42
実験結果 1. 推論エンジンの選択 vLLM
推論サービスのスクリプト ベンチマーク結果
MindIE
推論サービスのスクリプト # This is a simplified vLLM-like command. GPUStack maps arguments to the
# corresponding MindIE JSON configuration and runs with mindieservice_daemon.
serve Qwen/Qwen3-8B
ベンチマーク結果
結果: MineIE (5634.4 tok/s) > vLLM (3143.94 tok/s)
2. 量子化:MindIE 推論サービスのスクリプト # This is a simplified vLLM-like command. GPUStack maps arguments to the
# corresponding MindIE JSON configuration and runs with mindieservice_daemon.
serve vllm-ascend/Qwen3-8B-W8A8
ベンチマーク結果
3. プレフィックスキャッシュの有効化:MindIE 推論サービスのスクリプト # This is a simplified vLLM-like command. GPUStack maps arguments to the
# corresponding MindIE JSON configuration and runs with mindieservice_daemon.
serve vllm-ascend/Qwen3-8B-W8A8 --enable-prefix-caching
ベンチマーク結果
4. バッチサイズの調整:MindIE 推論サービスのスクリプト # This is a simplified vLLM-like command. GPUStack maps arguments to the
# corresponding MindIE JSON configuration and runs with mindieservice_daemon.
serve vllm-ascend/Qwen3-8B-W8A8 --enable-prefix-caching --max-batch-size= 400 --max-prefill-batch-size= 200
ベンチマーク結果
最適化項目の一覧 最適化項目 スループット改善率 エンジンの選択 +79.2% 量子化 +7.2% プレフィックスキャッシュ +3.6% バッチサイズの調整 -
その他のベンチマークケース さらに、さまざまなワークロードに対する汎用性を評価するため、最適化済み設定でベンチマークを実施しました。
基準設定の推論スクリプト 基準設定のベンチマーク結果 # random 32K input
============ Serving Benchmark Result ============
requests: 100
duration ( s) : 1110 .48
input tokens: 3200000
generated tokens: 10000
throughput ( req/s) : 0 .09
token throughput ( tok/s) : 9 .01
output token throughput ( tok/s) : 147 .00
concurrent requests: 100 .00
Token throughput ( tok/s) : 2890 .64
to First Token----------------
TTFT ( ms) : 559550 .01
TTFT ( ms) : 561560 .86
TTFT ( ms) : 1096851 .78
per Output Token ( excl. 1st token) ------
TPOT ( ms) : 344 .18
TPOT ( ms) : 346 .89
TPOT ( ms) : 668 .43
Latency----------------
ITL ( ms) : 340 .74
ITL ( ms) : 48 .54
ITL ( ms) : 59 .04
==================================================
# random 4K input
============ Serving Benchmark Result ============
requests: 500
duration ( s) : 273 .17
input tokens: 1997463
generated tokens: 99812
throughput ( req/s) : 1 .83
token throughput ( tok/s) : 365 .38
output token throughput ( tok/s) : 1062 .00
concurrent requests: 500 .00
Token throughput ( tok/s) : 7677 .41
to First Token----------------
TTFT ( ms) : 132541 .20
TTFT ( ms) : 135284 .67
TTFT ( ms) : 262452 .37
per Output Token ( excl. 1st token) ------
TPOT ( ms) : 99 .26
TPOT ( ms) : 100 .01
TPOT ( ms) : 175 .24
Latency----------------
ITL ( ms) : 98 .69
ITL ( ms) : 55 .84
ITL ( ms) : 134 .52
==================================================
# random 2K input
============ Serving Benchmark Result ============
requests: 500
duration ( s) : 109 .30
input tokens: 998057
generated tokens: 50000
throughput ( req/s) : 4 .57
token throughput ( tok/s) : 457 .47
output token throughput ( tok/s) : 1904 .00
concurrent requests: 500 .00
Token throughput ( tok/s) : 9589 .00
to First Token----------------
TTFT ( ms) : 53978 .52
TTFT ( ms) : 57661 .39
TTFT ( ms) : 103428 .31
per Output Token ( excl. 1st token) ------
TPOT ( ms) : 140 .39
TPOT ( ms) : 142 .80
TPOT ( ms) : 275 .05
Latency----------------
ITL ( ms) : 139 .05
ITL ( ms) : 63 .53
ITL ( ms) : 627 .10
==================================================
# random 128 input
============ Serving Benchmark Result ============
requests: 1000
duration ( s) : 22 .59
input tokens: 127782
generated tokens: 4000
throughput ( req/s) : 44 .28
token throughput ( tok/s) : 177 .10
output token throughput ( tok/s) : 1280 .00
concurrent requests: 1000 .00
Token throughput ( tok/s) : 5834 .79
to First Token----------------
TTFT ( ms) : 18464 .39
TTFT ( ms) : 17489 .55
TTFT ( ms) : 22134 .55
per Output Token ( excl. 1st token) ------
TPOT ( ms) : 125 .55
TPOT ( ms) : 135 .76
TPOT ( ms) : 149 .27
Latency----------------
ITL ( ms) : 94 .16
ITL ( ms) : 83 .83
ITL ( ms) : 251 .91
==================================================
# ShareGPT batch size 4
============ Serving Benchmark Result ============
requests: 100
request concurrency: 4
duration ( s) : 275 .57
input tokens: 23260
generated tokens: 22061
throughput ( req/s) : 0 .36
token throughput ( tok/s) : 80 .06
output token throughput ( tok/s) : 92 .00
concurrent requests: 8 .00
Token throughput ( tok/s) : 164 .46
to First Token----------------
TTFT ( ms) : 145 .88
TTFT ( ms) : 142 .78
TTFT ( ms) : 201 .58
per Output Token ( excl. 1st token) ------
TPOT ( ms) : 47 .28
TPOT ( ms) : 47 .29
TPOT ( ms) : 50 .41
Latency----------------
ITL ( ms) : 47 .10
ITL ( ms) : 46 .72
ITL ( ms) : 91 .82
==================================================
最適化後の推論スクリプト # This is a simplified vLLM-like command. GPUStack maps arguments to the
# corresponding MindIE JSON configuration and runs with mindieservice_daemon.
serve vllm-ascend/Qwen3-8B-W8A8 --enable-prefix-caching
最適化後のベンチマーク結果 # random 32K input
============ Serving Benchmark Result ============
requests: 100
duration ( s) : 296 .36
input tokens: 3200000
generated tokens: 9693
throughput ( req/s) : 0 .34
token throughput ( tok/s) : 32 .71
output token throughput ( tok/s) : 330 .00
concurrent requests: 100 .00
Token throughput ( tok/s) : 10830 .52
to First Token----------------
TTFT ( ms) : 147133 .58
TTFT ( ms) : 147851 .57
TTFT ( ms) : 289974 .37
per Output Token ( excl. 1st token) ------
TPOT ( ms) : 242 .08
TPOT ( ms) : 232 .74
TPOT ( ms) : 741 .49
Latency----------------
ITL ( ms) : 225 .71
ITL ( ms) : 46 .46
ITL ( ms) : 56 .81
==================================================
# random 4K input
============ Serving Benchmark Result ============
requests: 500
duration ( s) : 157 .15
input tokens: 2000000
generated tokens: 99961
throughput ( req/s) : 3 .18
token throughput ( tok/s) : 636 .07
output token throughput ( tok/s) : 2142 .00
concurrent requests: 500 .00
Token throughput ( tok/s) : 13362 .49
to First Token----------------
TTFT ( ms) : 70716 .71
TTFT ( ms) : 74982 .88
TTFT ( ms) : 148427 .09
per Output Token ( excl. 1st token) ------
TPOT ( ms) : 130 .97
TPOT ( ms) : 134 .98
TPOT ( ms) : 208 .16
Latency----------------
ITL ( ms) : 130 .95
ITL ( ms) : 63 .84
ITL ( ms) : 489 .52
==================================================
# random 2K input
============ Serving Benchmark Result ============
requests: 500
duration ( s) : 67 .34
input tokens: 1000000
generated tokens: 49975
throughput ( req/s) : 7 .42
token throughput ( tok/s) : 742 .11
output token throughput ( tok/s) : 3000 .00
concurrent requests: 500 .00
Token throughput ( tok/s) : 15591 .71
to First Token----------------
TTFT ( ms) : 29078 .68
TTFT ( ms) : 32203 .66
TTFT ( ms) : 62077 .78
per Output Token ( excl. 1st token) ------
TPOT ( ms) : 194 .54
TPOT ( ms) : 192 .07
TPOT ( ms) : 358 .38
Latency----------------
ITL ( ms) : 194 .46
ITL ( ms) : 68 .54
ITL ( ms) : 4496 .71
==================================================
# random 128 input
============ Serving Benchmark Result ============
requests: 1000
duration ( s) : 8 .78
input tokens: 128000
generated tokens: 4000
throughput ( req/s) : 113 .94
token throughput ( tok/s) : 455 .76
output token throughput ( tok/s) : 2511 .00
concurrent requests: 1000 .00
Token throughput ( tok/s) : 15040 .15
to First Token----------------
TTFT ( ms) : 4491 .88
TTFT ( ms) : 4467 .47
TTFT ( ms) : 7693 .24
per Output Token ( excl. 1st token) ------
TPOT ( ms) : 1249 .72
TPOT ( ms) : 1258 .92
TPOT ( ms) : 2252 .88
Latency----------------
ITL ( ms) : 1249 .72
ITL ( ms) : 54 .67
ITL ( ms) : 6378 .56
==================================================
# ShareGPT batch size 4
============ Serving Benchmark Result ============
requests: 1000
request concurrency: 4
duration ( s) : 1292 .33
input tokens: 217393
generated tokens: 201773
throughput ( req/s) : 0 .77
token throughput ( tok/s) : 156 .13
output token throughput ( tok/s) : 200 .00
concurrent requests: 9 .00
Token throughput ( tok/s) : 324 .35
to First Token----------------
TTFT ( ms) : 112 .38
TTFT ( ms) : 111 .05
TTFT ( ms) : 154 .06
per Output Token ( excl. 1st token) ------
TPOT ( ms) : 25 .42
TPOT ( ms) : 24 .47
TPOT ( ms) : 35 .05
Latency----------------
ITL ( ms) : 25 .08
ITL ( ms) : 23 .05
ITL ( ms) : 79 .54
==================================================