Qwen3.5-9B gecikme optimizasyonu Sonuç
NVIDIA H100 80GB HBM3 üzerinde Qwen/Qwen3.5-9B gecikmesini optimize etmek için önerilen yapılandırma:
Model sunum komutu vllm serve Qwen/Qwen3.5-9B \
--reasoning-parser= qwen3 \
--max-model-len= 32768 \
--speculative-config={ "method" :"mtp" ,"num_speculative_tokens" :1} \
--language-model-only \
--performance-mode= interactivity
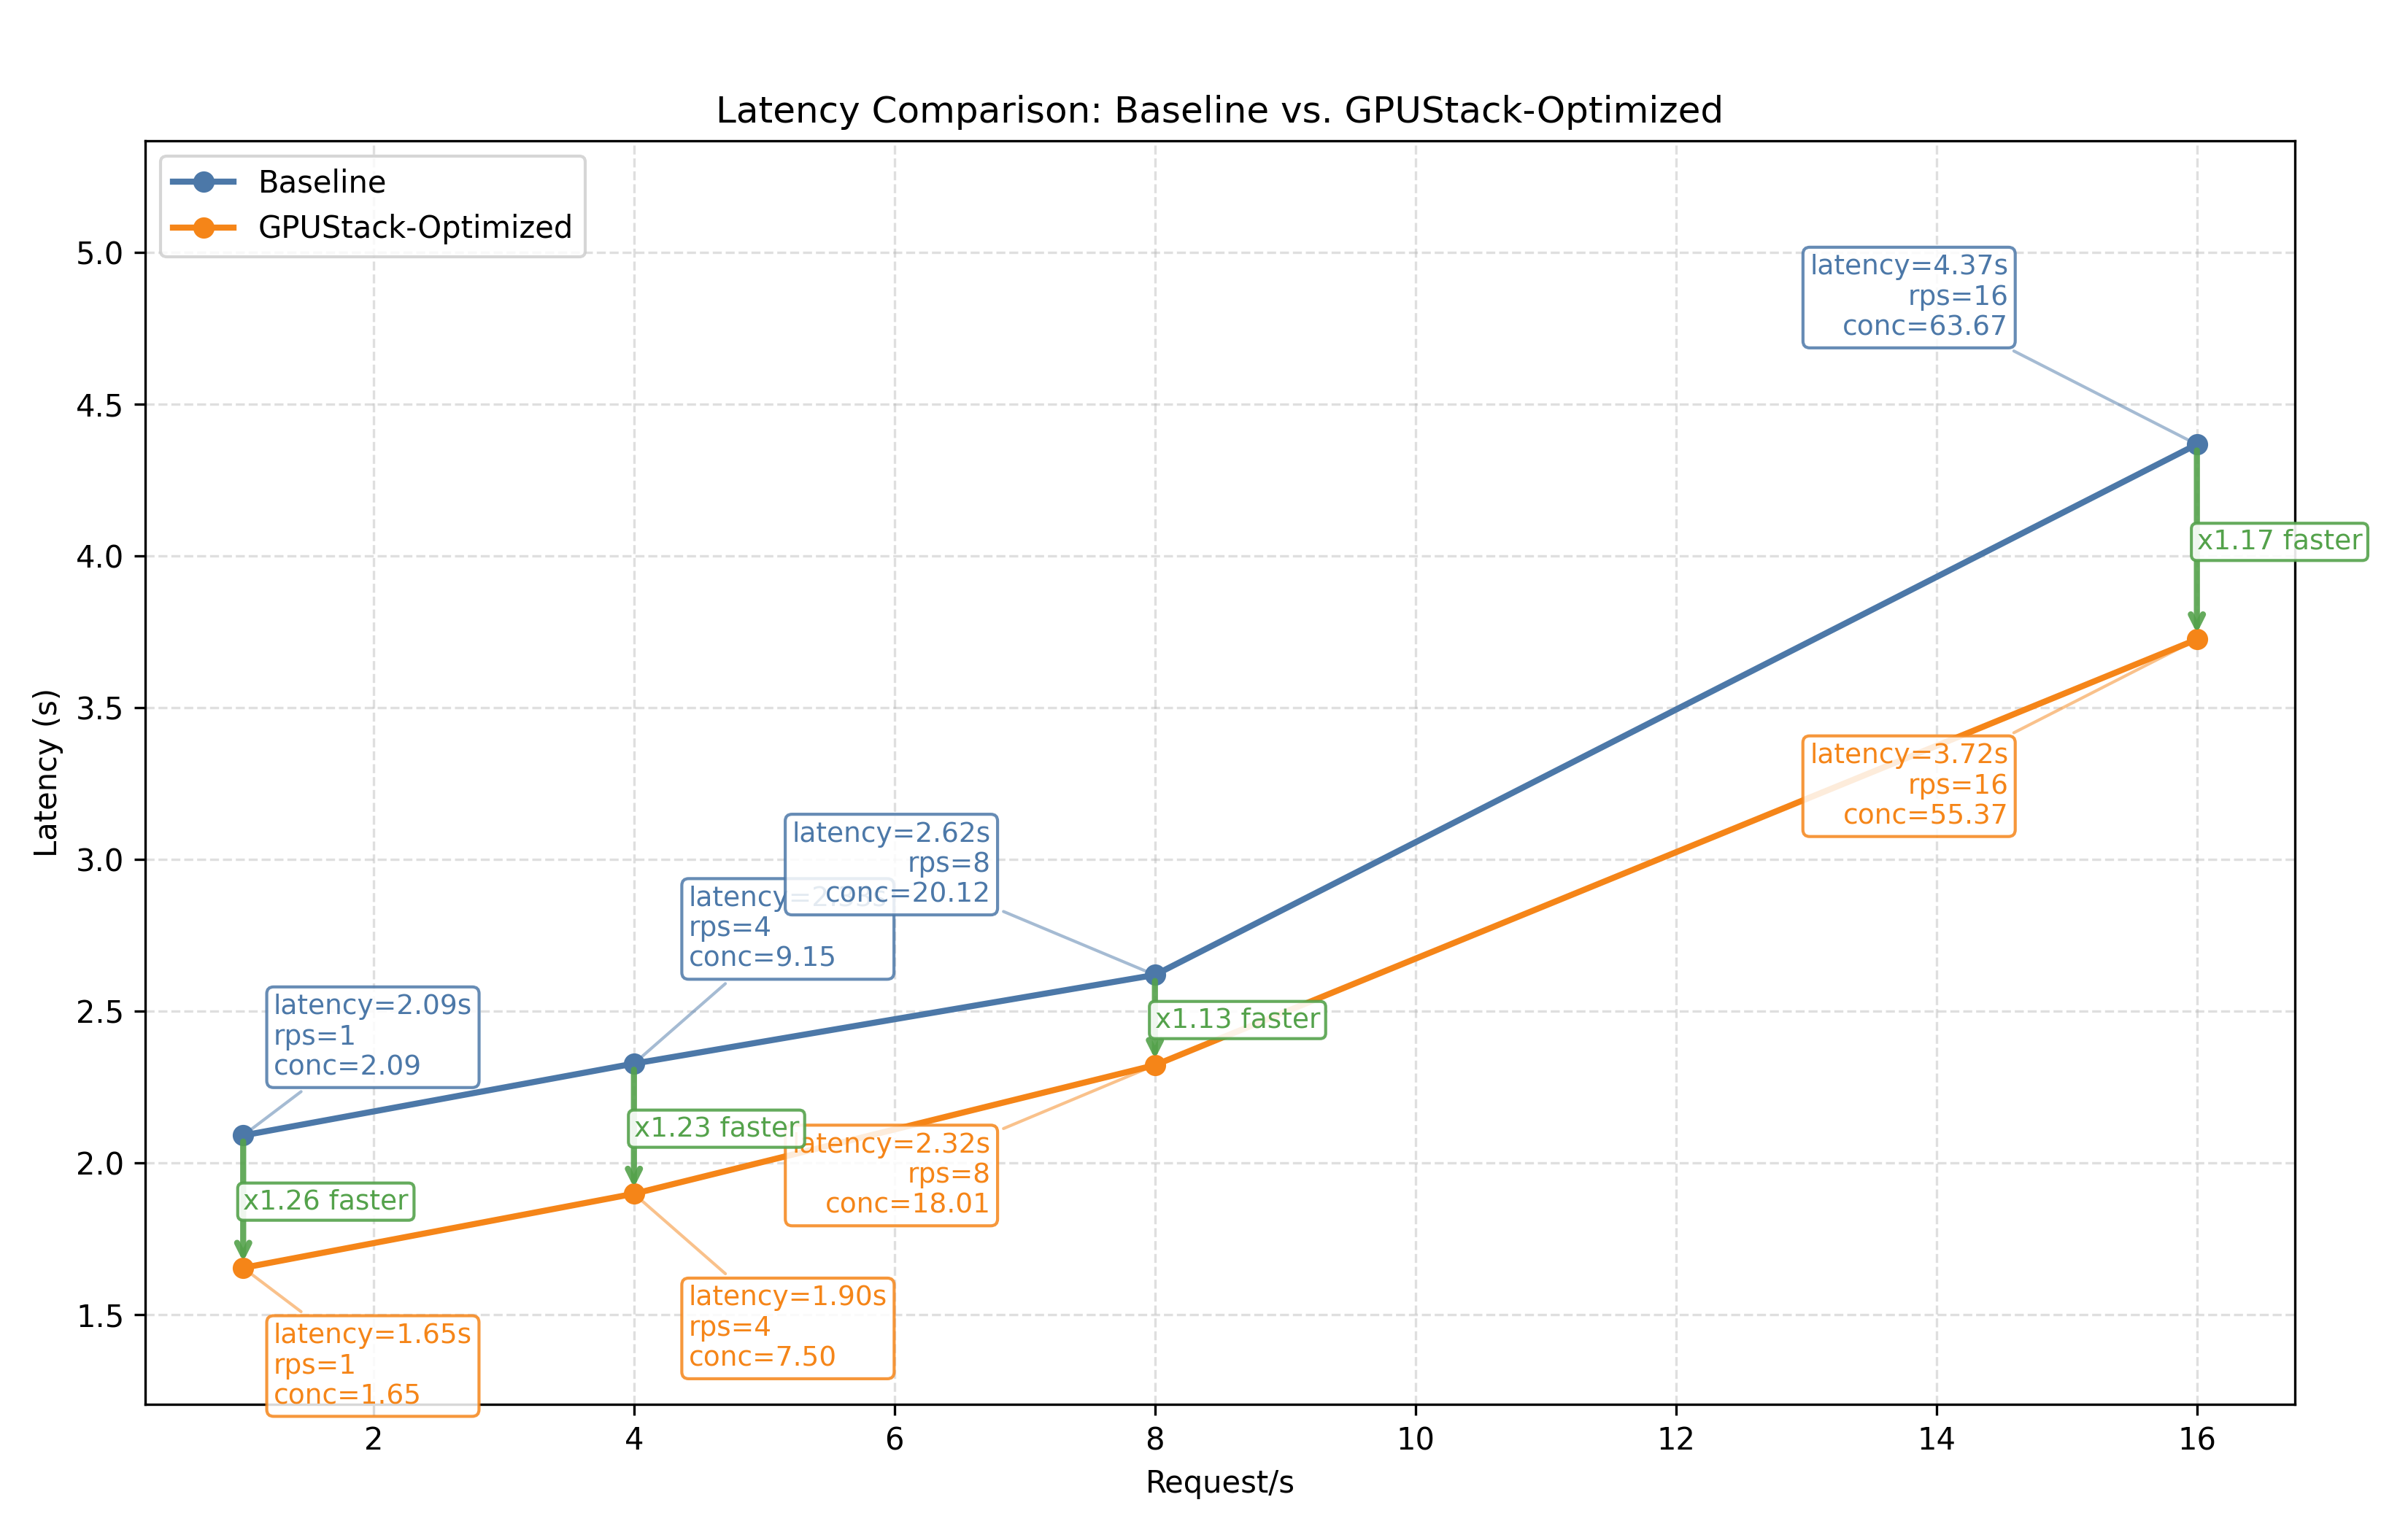
Optimizasyon öncesi ve sonrası benchmark sonuçlarının karşılaştırması:
Benchmark senaryosu Temel yapılandırma (optimizasyonsuz vLLM) Optimize edilmiş Rate 1 Ortalama gecikme: 2.09s/req Ortalama gecikme: 1.65s/req (1.26x faster) Rate 4 Ortalama gecikme: 2.33s/req Ortalama gecikme: 1.90s/req (1.23x faster) Rate 8 Ortalama gecikme: 2.62s/req Ortalama gecikme: 2.32s/req (1.13x faster) Rate 16 Ortalama gecikme: 4.37s/req Ortalama gecikme: 3.72s/req (1.17x faster)
Not
Benchmark testlerimiz olası tüm optimizasyon birleşimlerini kapsamaz. Örneğin, varsayılan yapılandırmasında en iyi performansı gösteren çıkarım motorunu sonraki ayarlamalar için başlangıç noktası olarak seçeriz. Bu eleme yaklaşımı yerel bir optimum verir; bu, genel optimum olmayabilir. En büyük toplu iş boyutu, zamanlama yapılandırması, genişletilmiş KV önbelleği, CUDA graph gibi belirli kullanım senaryolarına bağlı başka optimizasyonlar da vardır. Bu belgedeki sonuçlar, daha hedefli optimizasyonlar için başlangıç noktası olabilir. Testler belirli donanım ve yazılım yapılandırmalarında yürütülmüştür. Çıkarım motorlarındaki gelişmeler sonuçları değiştirebilir. Nicemleme doğruluğu etkileyebilir; ancak FP8 nicemleme çoğu modelde %1'den az doğruluk kaybı sağlayabilir. Ayrıntılar için değerlendirme sonuçlarına bakın. Bu nedenle düşük gecikmeli sunum senaryolarında FP8 nicemleme önemle önerilir. Spekülatif kod çözme, düşük eş zamanlılıktaki isteklerin gecikmesini önemli ölçüde azaltabilir. Ancak hızlanma, benchmark veri dağılımına ve taslak model seçimine bağlıdır. Örneğin burada seçilen taslak model İngilizce verilerle eğitilmiştir; diğer dillerde en iyi performansı vermeyebilir. Eksik noktalar veya yeni değişiklikleri yansıtacak güncellemeler varsa bize bildirin .
Deney kurulumu Model Qwen/Qwen3.5-9B
Donanım NVIDIA H100 80GB HBM3
Motor sürümü vLLM v0.17.1 SGLang v0.5.9 Benchmark yöntemi Bu projede model sunum iş yükleri için GPUStack'in tek tıklamalı benchmark özelliği kullanılır. Bu belgedeki benchmark testleri bu akışla yürütülmüştür.
GPUStack'in benchmark uygulaması guidellm üzerine, sarmalayıcı benchmark-runner projesi aracılığıyla kurulmuştur.
Aşağıda listelenen benchmark yapılandırmalarında model dağıtımı, benchmark işinin gönderilmesi ve sonuçların toplanması GPUStack tarafından yapılır.
Benchmark profilleri ShareGPT 8RPS dataset_name : ShareGPT
request_rate : 8
total_requests : 1000
ShareGPT 1RPS dataset_name : ShareGPT
request_rate : 1
total_requests : 1000
ShareGPT 4RPS dataset_name : ShareGPT
request_rate : 4
total_requests : 1000
ShareGPT 16RPS dataset_name : ShareGPT
request_rate : 16
total_requests : 1000
Açık kaynak araçlarla değiştirme GPUStack kullanmıyorsanız GPUStack benchmark akışını doğrudan guidellm benchmark komutlarıyla değiştirebilirsiniz.
dataset_name: ShareGPT kullanılan profiller için:
guidellm benchmark \
--target ${ target } \
--profile constant \
--rate ${ request_rate } \
--max-requests ${ total_requests } \
--processor ${ model_path } \
--data ./ShareGPT_V3_unfiltered_cleaned_split.json
Deney sonuçları Çıkarım motoru seçimi vLLM Profil: ShareGPT 8RPS Arka uç parametreleri: --reasoning-parser= qwen3
--max-model-len= 32768
Benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 31
Benchmark duration (s): 130.18
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.68
Output token throughput (tok/s): 2197.17
Peak output token throughput (tok/s): 2885041.51
Peak concurrent requests: 31.00
Total Token throughput (tok/s): 4867.84
----------------------Latency---------------------
Mean Latency(s): 2.62
Median Latency(s): 2.29
P95 Latency(s): 6.81
P99 Latency(s): 7.75
---------------Time to First Token----------------
Mean TTFT (ms): 41.12
Median TTFT (ms): 33.92
P95 TTFT (ms): 72.24
P99 TTFT (ms): 141.44
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.34
Median TPOT (ms): 0.11
P95 TPOT (ms): 9.18
P99 TPOT (ms): 10.07
---------------Inter-token Latency----------------
Mean ITL (ms): 1.19
Median ITL (ms): 0.00
P95 ITL (ms): 9.08
P99 ITL (ms): 10.04
==================================================
SGLang Profil: ShareGPT 8RPS Arka uç parametreleri: --reasoning-parser= qwen3
--context-length= 32768
Benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 96
Benchmark duration (s): 131.60
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.60
Output token throughput (tok/s): 2145.85
Peak output token throughput (tok/s): 33380.30
Peak concurrent requests: 96.00
Total Token throughput (tok/s): 4754.13
----------------------Latency---------------------
Mean Latency(s): 8.13
Median Latency(s): 6.94
P95 Latency(s): 20.20
P99 Latency(s): 26.21
---------------Time to First Token----------------
Mean TTFT (ms): 98.72
Median TTFT (ms): 51.48
P95 TTFT (ms): 212.72
P99 TTFT (ms): 460.47
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 28.88
Median TPOT (ms): 28.26
P95 TPOT (ms): 43.34
P99 TPOT (ms): 51.52
---------------Inter-token Latency----------------
Mean ITL (ms): 28.63
Median ITL (ms): 27.88
P95 ITL (ms): 43.23
P99 ITL (ms): 50.55
==================================================
Özet: vLLM Ortalama gecikme = 2.62s, SGLang Ortalama gecikme = 8.13s. vLLM, 5.51 s daha hızlıdır (3.10x daha hızlı). TTFT = 41.12 ms ile 98.72 ms, azalma: 57.60 ms (2.40x daha hızlı); TPOT = 1.34 ms ile 28.88 ms, azalma: 27.54 ms (21.62x daha hızlı). Önek önbelleği Profil: ShareGPT 8RPS Arka uç parametreleri: --reasoning-parser= qwen3
--max-model-len= 32768
--enable-prefix-caching
Benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 32
Benchmark duration (s): 130.23
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.68
Output token throughput (tok/s): 2212.47
Peak output token throughput (tok/s): 1443445.16
Peak concurrent requests: 32.00
Total Token throughput (tok/s): 4901.75
----------------------Latency---------------------
Mean Latency(s): 2.69
Median Latency(s): 2.36
P95 Latency(s): 6.95
P99 Latency(s): 7.94
---------------Time to First Token----------------
Mean TTFT (ms): 46.19
Median TTFT (ms): 34.75
P95 TTFT (ms): 90.30
P99 TTFT (ms): 233.30
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.38
Median TPOT (ms): 0.12
P95 TPOT (ms): 9.49
P99 TPOT (ms): 10.50
---------------Inter-token Latency----------------
Mean ITL (ms): 1.22
Median ITL (ms): 0.00
P95 ITL (ms): 9.35
P99 ITL (ms): 10.40
==================================================
En fazla toplu iş token'ı 16k Profil: ShareGPT 8RPS Arka uç parametreleri: --reasoning-parser= qwen3
--max-model-len= 32768
--max-num-batched-tokens= 16384
Benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 31
Benchmark duration (s): 130.20
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.68
Output token throughput (tok/s): 2220.17
Peak output token throughput (tok/s): 2763536.75
Peak concurrent requests: 31.00
Total Token throughput (tok/s): 4918.81
----------------------Latency---------------------
Mean Latency(s): 2.64
Median Latency(s): 2.30
P95 Latency(s): 6.87
P99 Latency(s): 7.79
---------------Time to First Token----------------
Mean TTFT (ms): 42.05
Median TTFT (ms): 34.13
P95 TTFT (ms): 76.02
P99 TTFT (ms): 190.03
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.26
Median TPOT (ms): 0.11
P95 TPOT (ms): 9.19
P99 TPOT (ms): 10.11
---------------Inter-token Latency----------------
Mean ITL (ms): 1.11
Median ITL (ms): 0.00
P95 ITL (ms): 9.13
P99 ITL (ms): 10.04
==================================================
32k Profil: ShareGPT 8RPS Arka uç parametreleri: --reasoning-parser= qwen3
--max-model-len= 32768
--max-num-batched-tokens= 32768
Benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 31
Benchmark duration (s): 130.20
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.68
Output token throughput (tok/s): 2196.67
Peak output token throughput (tok/s): 1167858.46
Peak concurrent requests: 31.00
Total Token throughput (tok/s): 4866.73
----------------------Latency---------------------
Mean Latency(s): 2.64
Median Latency(s): 2.31
P95 Latency(s): 6.88
P99 Latency(s): 7.81
---------------Time to First Token----------------
Mean TTFT (ms): 41.88
Median TTFT (ms): 34.03
P95 TTFT (ms): 76.91
P99 TTFT (ms): 164.85
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.38
Median TPOT (ms): 0.11
P95 TPOT (ms): 9.34
P99 TPOT (ms): 10.14
---------------Inter-token Latency----------------
Mean ITL (ms): 1.23
Median ITL (ms): 0.00
P95 ITL (ms): 9.20
P99 ITL (ms): 10.09
==================================================
Özet: 16k Ortalama gecikme = 2.64s, 32k Ortalama gecikme = 2.64s. 16k, 0.00 s daha hızlıdır (1.00x daha hızlı). TTFT = 42.05 ms ile 41.88 ms, artış: 0.17 ms (1.00x daha yavaş); TPOT = 1.26 ms ile 1.38 ms, azalma: 0.12 ms (1.10x daha hızlı). En fazla dizi sayısı Dizi sayısı 128 Profil: ShareGPT 8RPS Arka uç parametreleri: --reasoning-parser= qwen3
--max-model-len= 32768
--max-num-seqs= 128
Benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 31
Benchmark duration (s): 130.18
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.68
Output token throughput (tok/s): 2213.28
Peak output token throughput (tok/s): 3033763.06
Peak concurrent requests: 31.00
Total Token throughput (tok/s): 4903.53
----------------------Latency---------------------
Mean Latency(s): 2.66
Median Latency(s): 2.32
P95 Latency(s): 6.91
P99 Latency(s): 7.82
---------------Time to First Token----------------
Mean TTFT (ms): 44.11
Median TTFT (ms): 35.02
P95 TTFT (ms): 75.65
P99 TTFT (ms): 197.93
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.33
Median TPOT (ms): 0.11
P95 TPOT (ms): 9.53
P99 TPOT (ms): 10.28
---------------Inter-token Latency----------------
Mean ITL (ms): 1.17
Median ITL (ms): 0.00
P95 ITL (ms): 9.48
P99 ITL (ms): 10.23
==================================================
Dizi sayısı 256 Profil: ShareGPT 8RPS Arka uç parametreleri: --reasoning-parser= qwen3
--max-model-len= 32768
--max-num-seqs= 256
Benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 31
Benchmark duration (s): 130.18
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.68
Output token throughput (tok/s): 2196.96
Peak output token throughput (tok/s): 1994998.46
Peak concurrent requests: 31.00
Total Token throughput (tok/s): 4867.37
----------------------Latency---------------------
Mean Latency(s): 2.64
Median Latency(s): 2.30
P95 Latency(s): 6.82
P99 Latency(s): 7.79
---------------Time to First Token----------------
Mean TTFT (ms): 42.97
Median TTFT (ms): 34.30
P95 TTFT (ms): 77.05
P99 TTFT (ms): 187.56
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.32
Median TPOT (ms): 0.11
P95 TPOT (ms): 9.23
P99 TPOT (ms): 10.28
---------------Inter-token Latency----------------
Mean ITL (ms): 1.17
Median ITL (ms): 0.00
P95 ITL (ms): 9.16
P99 ITL (ms): 10.16
==================================================
Özet: Seqs 256 Ortalama gecikme = 2.64s, Seqs 128 Ortalama gecikme = 2.66s. Seqs 256, 0.02 s daha hızlıdır (1.01x daha hızlı). TTFT = 42.97 ms ile 44.11 ms, azalma: 1.13 ms (1.03x daha hızlı); TPOT = 1.32 ms ile 1.33 ms, azalma: 0.01 ms (1.01x daha hızlı). Spekülatif kod çözme Profil: ShareGPT 8RPS Arka uç parametreleri: --reasoning-parser= qwen3
--speculative-config={ "method" :"mtp" ,"num_speculative_tokens" :1}
--max-model-len= 32768
Benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 28
Benchmark duration (s): 129.03
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.75
Output token throughput (tok/s): 2224.24
Peak output token throughput (tok/s): 9620127.05
Peak concurrent requests: 28.00
Total Token throughput (tok/s): 4927.83
----------------------Latency---------------------
Mean Latency(s): 2.39
Median Latency(s): 2.08
P95 Latency(s): 6.12
P99 Latency(s): 7.17
---------------Time to First Token----------------
Mean TTFT (ms): 81.50
Median TTFT (ms): 55.93
P95 TTFT (ms): 96.41
P99 TTFT (ms): 788.19
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.29
Median TPOT (ms): 0.18
P95 TPOT (ms): 8.45
P99 TPOT (ms): 9.48
---------------Inter-token Latency----------------
Mean ITL (ms): 1.01
Median ITL (ms): 0.00
P95 ITL (ms): 8.31
P99 ITL (ms): 9.42
==================================================
Profil: ShareGPT 8RPS Arka uç parametreleri: --reasoning-parser= qwen3
--performance-mode= interactivity
--max-model-len= 32768
--speculative-config={ "method" :"mtp" ,"num_speculative_tokens" :1}
Benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 28
Benchmark duration (s): 129.07
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.75
Output token throughput (tok/s): 2214.80
Peak output token throughput (tok/s): 1904162.55
Peak concurrent requests: 28.00
Total Token throughput (tok/s): 4906.90
----------------------Latency---------------------
Mean Latency(s): 2.38
Median Latency(s): 2.09
P95 Latency(s): 6.09
P99 Latency(s): 7.20
---------------Time to First Token----------------
Mean TTFT (ms): 82.37
Median TTFT (ms): 55.71
P95 TTFT (ms): 96.16
P99 TTFT (ms): 960.28
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.42
Median TPOT (ms): 0.18
P95 TPOT (ms): 8.54
P99 TPOT (ms): 9.65
---------------Inter-token Latency----------------
Mean ITL (ms): 1.13
Median ITL (ms): 0.00
P95 ITL (ms): 8.39
P99 ITL (ms): 9.08
==================================================
Profil: ShareGPT 8RPS Arka uç parametreleri: --reasoning-parser= qwen3
--max-model-len= 32768
--speculative-config={ "method" :"mtp" ,"num_speculative_tokens" :1}
--language-model-only
--performance-mode= interactivity
Benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 27
Benchmark duration (s): 128.98
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.75
Output token throughput (tok/s): 2214.46
Peak output token throughput (tok/s): 4861500.66
Peak concurrent requests: 27.00
Total Token throughput (tok/s): 4906.15
----------------------Latency---------------------
Mean Latency(s): 2.32
Median Latency(s): 2.02
P95 Latency(s): 5.99
P99 Latency(s): 6.89
---------------Time to First Token----------------
Mean TTFT (ms): 80.63
Median TTFT (ms): 54.04
P95 TTFT (ms): 96.82
P99 TTFT (ms): 933.41
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.31
Median TPOT (ms): 0.17
P95 TPOT (ms): 8.19
P99 TPOT (ms): 9.47
---------------Inter-token Latency----------------
Mean ITL (ms): 1.02
Median ITL (ms): 0.00
P95 ITL (ms): 8.03
P99 ITL (ms): 8.91
==================================================
Optimizasyon seçeneklerinin özeti Benchmark senaryosu Grup Optimize edilmiş Temel yapılandırma Karşılaştırma ShareGPT 8RPS (r=8) Çıkarım motoru seçimi 2.62s 2.62s (1.00x faster) ShareGPT 8RPS (r=8) Önek önbelleği 2.69s 2.62s (1.03x slower) ShareGPT 8RPS (r=8) En fazla toplu iş token'ı 2.64s 2.62s (1.01x slower) ShareGPT 8RPS (r=8) En fazla dizi sayısı 2.64s 2.62s (1.01x slower) ShareGPT 8RPS (r=8) Spekülatif kod çözme 2.39s 2.62s (1.09x faster) ShareGPT 8RPS (r=8) Spekülatif kod çözme && Performans modu 2.38s 2.62s (1.10x faster) ShareGPT 8RPS (r=8) Spekülatif kod çözme && Performans modu && Dil modeli 2.32s 2.62s (1.13x faster)
Diğer benchmark senaryoları İstek hızı 1 Temel arka uç parametreleri: --reasoning-parser= qwen3
--max-model-len= 32768
Temel benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 6
Benchmark duration (s): 1001.23
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 1.00
Output token throughput (tok/s): 281.69
Peak output token throughput (tok/s): 211793.17
Peak concurrent requests: 6.00
Total Token throughput (tok/s): 624.09
----------------------Latency---------------------
Mean Latency(s): 2.09
Median Latency(s): 1.85
P95 Latency(s): 5.42
P99 Latency(s): 6.27
---------------Time to First Token----------------
Mean TTFT (ms): 37.03
Median TTFT (ms): 31.51
P95 TTFT (ms): 63.17
P99 TTFT (ms): 95.35
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 0.94
Median TPOT (ms): 0.10
P95 TPOT (ms): 7.38
P99 TPOT (ms): 7.51
---------------Inter-token Latency----------------
Mean ITL (ms): 0.81
Median ITL (ms): 0.00
P95 ITL (ms): 7.34
P99 ITL (ms): 7.47
==================================================
Optimize edilmiş arka uç parametreleri: --reasoning-parser= qwen3
--max-model-len= 32768
--speculative-config={ "method" :"mtp" ,"num_speculative_tokens" :1}
--language-model-only
--performance-mode= interactivity
Optimize edilmiş benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 5
Benchmark duration (s): 1000.35
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 1.00
Output token throughput (tok/s): 281.69
Peak output token throughput (tok/s): 271386.26
Peak concurrent requests: 5.00
Total Token throughput (tok/s): 624.08
----------------------Latency---------------------
Mean Latency(s): 1.65
Median Latency(s): 1.45
P95 Latency(s): 4.28
P99 Latency(s): 4.98
---------------Time to First Token----------------
Mean TTFT (ms): 54.58
Median TTFT (ms): 50.45
P95 TTFT (ms): 75.37
P99 TTFT (ms): 123.14
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 0.91
Median TPOT (ms): 0.15
P95 TPOT (ms): 5.90
P99 TPOT (ms): 6.22
---------------Inter-token Latency----------------
Mean ITL (ms): 0.72
Median ITL (ms): 0.00
P95 ITL (ms): 5.75
P99 ITL (ms): 6.14
==================================================
İstek hızı 4 Temel arka uç parametreleri: --reasoning-parser= qwen3
--max-model-len= 32768
Temel benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 15
Benchmark duration (s): 254.36
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 3.93
Output token throughput (tok/s): 1126.78
Peak output token throughput (tok/s): 800262.91
Peak concurrent requests: 15.00
Total Token throughput (tok/s): 2496.39
----------------------Latency---------------------
Mean Latency(s): 2.33
Median Latency(s): 2.06
P95 Latency(s): 5.96
P99 Latency(s): 6.94
---------------Time to First Token----------------
Mean TTFT (ms): 38.09
Median TTFT (ms): 31.67
P95 TTFT (ms): 67.05
P99 TTFT (ms): 109.44
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.15
Median TPOT (ms): 0.10
P95 TPOT (ms): 8.25
P99 TPOT (ms): 8.73
---------------Inter-token Latency----------------
Mean ITL (ms): 1.02
Median ITL (ms): 0.00
P95 ITL (ms): 8.19
P99 ITL (ms): 8.67
==================================================
Optimize edilmiş arka uç parametreleri: --reasoning-parser= qwen3
--max-model-len= 32768
--speculative-config={ "method" :"mtp" ,"num_speculative_tokens" :1}
--language-model-only
--performance-mode= interactivity
Optimize edilmiş benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 13
Benchmark duration (s): 253.27
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 3.95
Output token throughput (tok/s): 1126.67
Peak output token throughput (tok/s): 996666.30
Peak concurrent requests: 13.00
Total Token throughput (tok/s): 2496.15
----------------------Latency---------------------
Mean Latency(s): 1.90
Median Latency(s): 1.66
P95 Latency(s): 4.91
P99 Latency(s): 5.82
---------------Time to First Token----------------
Mean TTFT (ms): 57.94
Median TTFT (ms): 52.57
P95 TTFT (ms): 77.15
P99 TTFT (ms): 112.48
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 0.97
Median TPOT (ms): 0.16
P95 TPOT (ms): 6.79
P99 TPOT (ms): 7.25
---------------Inter-token Latency----------------
Mean ITL (ms): 0.76
Median ITL (ms): 0.00
P95 ITL (ms): 6.64
P99 ITL (ms): 7.11
==================================================
İstek hızı 8 Temel arka uç parametreleri: --reasoning-parser= qwen3
--max-model-len= 32768
Temel benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 31
Benchmark duration (s): 130.18
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.68
Output token throughput (tok/s): 2197.17
Peak output token throughput (tok/s): 2885041.51
Peak concurrent requests: 31.00
Total Token throughput (tok/s): 4867.84
----------------------Latency---------------------
Mean Latency(s): 2.62
Median Latency(s): 2.29
P95 Latency(s): 6.81
P99 Latency(s): 7.75
---------------Time to First Token----------------
Mean TTFT (ms): 41.12
Median TTFT (ms): 33.92
P95 TTFT (ms): 72.24
P99 TTFT (ms): 141.44
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.34
Median TPOT (ms): 0.11
P95 TPOT (ms): 9.18
P99 TPOT (ms): 10.07
---------------Inter-token Latency----------------
Mean ITL (ms): 1.19
Median ITL (ms): 0.00
P95 ITL (ms): 9.08
P99 ITL (ms): 10.04
==================================================
Optimize edilmiş arka uç parametreleri: --reasoning-parser= qwen3
--max-model-len= 32768
--speculative-config={ "method" :"mtp" ,"num_speculative_tokens" :1}
--language-model-only
--performance-mode= interactivity
Optimize edilmiş benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 27
Benchmark duration (s): 128.98
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 7.75
Output token throughput (tok/s): 2214.46
Peak output token throughput (tok/s): 4861500.66
Peak concurrent requests: 27.00
Total Token throughput (tok/s): 4906.15
----------------------Latency---------------------
Mean Latency(s): 2.32
Median Latency(s): 2.02
P95 Latency(s): 5.99
P99 Latency(s): 6.89
---------------Time to First Token----------------
Mean TTFT (ms): 80.63
Median TTFT (ms): 54.04
P95 TTFT (ms): 96.82
P99 TTFT (ms): 933.41
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.31
Median TPOT (ms): 0.17
P95 TPOT (ms): 8.19
P99 TPOT (ms): 9.47
---------------Inter-token Latency----------------
Mean ITL (ms): 1.02
Median ITL (ms): 0.00
P95 ITL (ms): 8.03
P99 ITL (ms): 8.91
==================================================
İstek hızı 16 Temel arka uç parametreleri: --reasoning-parser= qwen3
--max-model-len= 32768
Temel benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 97
Benchmark duration (s): 68.59
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 14.58
Output token throughput (tok/s): 4119.85
Peak output token throughput (tok/s): 4297231.71
Peak concurrent requests: 97.00
Total Token throughput (tok/s): 9127.56
----------------------Latency---------------------
Mean Latency(s): 4.37
Median Latency(s): 3.74
P95 Latency(s): 10.93
P99 Latency(s): 14.05
---------------Time to First Token----------------
Mean TTFT (ms): 63.36
Median TTFT (ms): 52.12
P95 TTFT (ms): 111.22
P99 TTFT (ms): 283.00
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 2.07
Median TPOT (ms): 0.17
P95 TPOT (ms): 16.46
P99 TPOT (ms): 18.09
---------------Inter-token Latency----------------
Mean ITL (ms): 1.85
Median ITL (ms): 0.00
P95 ITL (ms): 16.34
P99 ITL (ms): 17.94
==================================================
Optimize edilmiş arka uç parametreleri: --reasoning-parser= qwen3
--max-model-len= 32768
--speculative-config={ "method" :"mtp" ,"num_speculative_tokens" :1}
--language-model-only
--performance-mode= interactivity
Optimize edilmiş benchmark sonucu ============ Serving Benchmark Result ============
Successful requests: 1000
Maximum request concurrency: 77
Benchmark duration (s): 67.27
Total input tokens: 342058
Total generated tokens: 281412
Request throughput (req/s): 14.86
Output token throughput (tok/s): 4191.07
Peak output token throughput (tok/s): 3207595.57
Peak concurrent requests: 77.00
Total Token throughput (tok/s): 9285.35
----------------------Latency---------------------
Mean Latency(s): 3.72
Median Latency(s): 3.31
P95 Latency(s): 9.44
P99 Latency(s): 11.45
---------------Time to First Token----------------
Mean TTFT (ms): 81.88
Median TTFT (ms): 66.01
P95 TTFT (ms): 149.68
P99 TTFT (ms): 375.11
-----Time per Output Token (excl. 1st token)------
Mean TPOT (ms): 1.92
Median TPOT (ms): 0.22
P95 TPOT (ms): 13.69
P99 TPOT (ms): 15.01
---------------Inter-token Latency----------------
Mean ITL (ms): 1.63
Median ITL (ms): 0.00
P95 ITL (ms): 13.50
P99 ITL (ms): 14.78
==================================================