

Overview
GPUStack is an open-source GPU cluster manager for AI model serving and GPU instance provisioning. It configures and orchestrates inference engines — vLLM, SGLang, TensorRT-LLM, or your own — and lets you launch SSH-accessible GPU instances on demand.
-
Multi-Cluster GPU Management
Manages GPU clusters across on-premises servers, Kubernetes, and cloud providers. Supports GPU slicing for model deployments and GPU instances, with configurable VRAM and compute allocations.
-
Pluggable Inference Engines
Automatically configures high-performance inference engines such as vLLM, SGLang, and TensorRT-LLM. You can also add custom inference engines as needed.
-
Performance-Optimized Configurations
Offers pre-tuned modes for low latency or high throughput. Supports prefill/decode disaggregation, platform-managed shared KV cache, and speculative decoding.
-
Built-in Benchmarking
Sweeps concurrency or request-rate levels to compare throughput and latency, helping you select operating points that meet your performance goals.
-
GPU Instances
Launches SSH-accessible GPU instances on demand for development, fine-tuning, and interactive workloads.
-
Enterprise-Grade Operations
Offers support for automated failure recovery, load balancing, monitoring, authentication, and access control.
Architecture
GPUStack enables development teams, IT organizations, and service providers to deliver Model-as-a-Service at scale. It supports industry-standard APIs for LLM, voice, image, and video models. The platform includes built-in user authentication and access control, real-time monitoring of GPU performance and utilization, and detailed metering of token usage and API request rates.
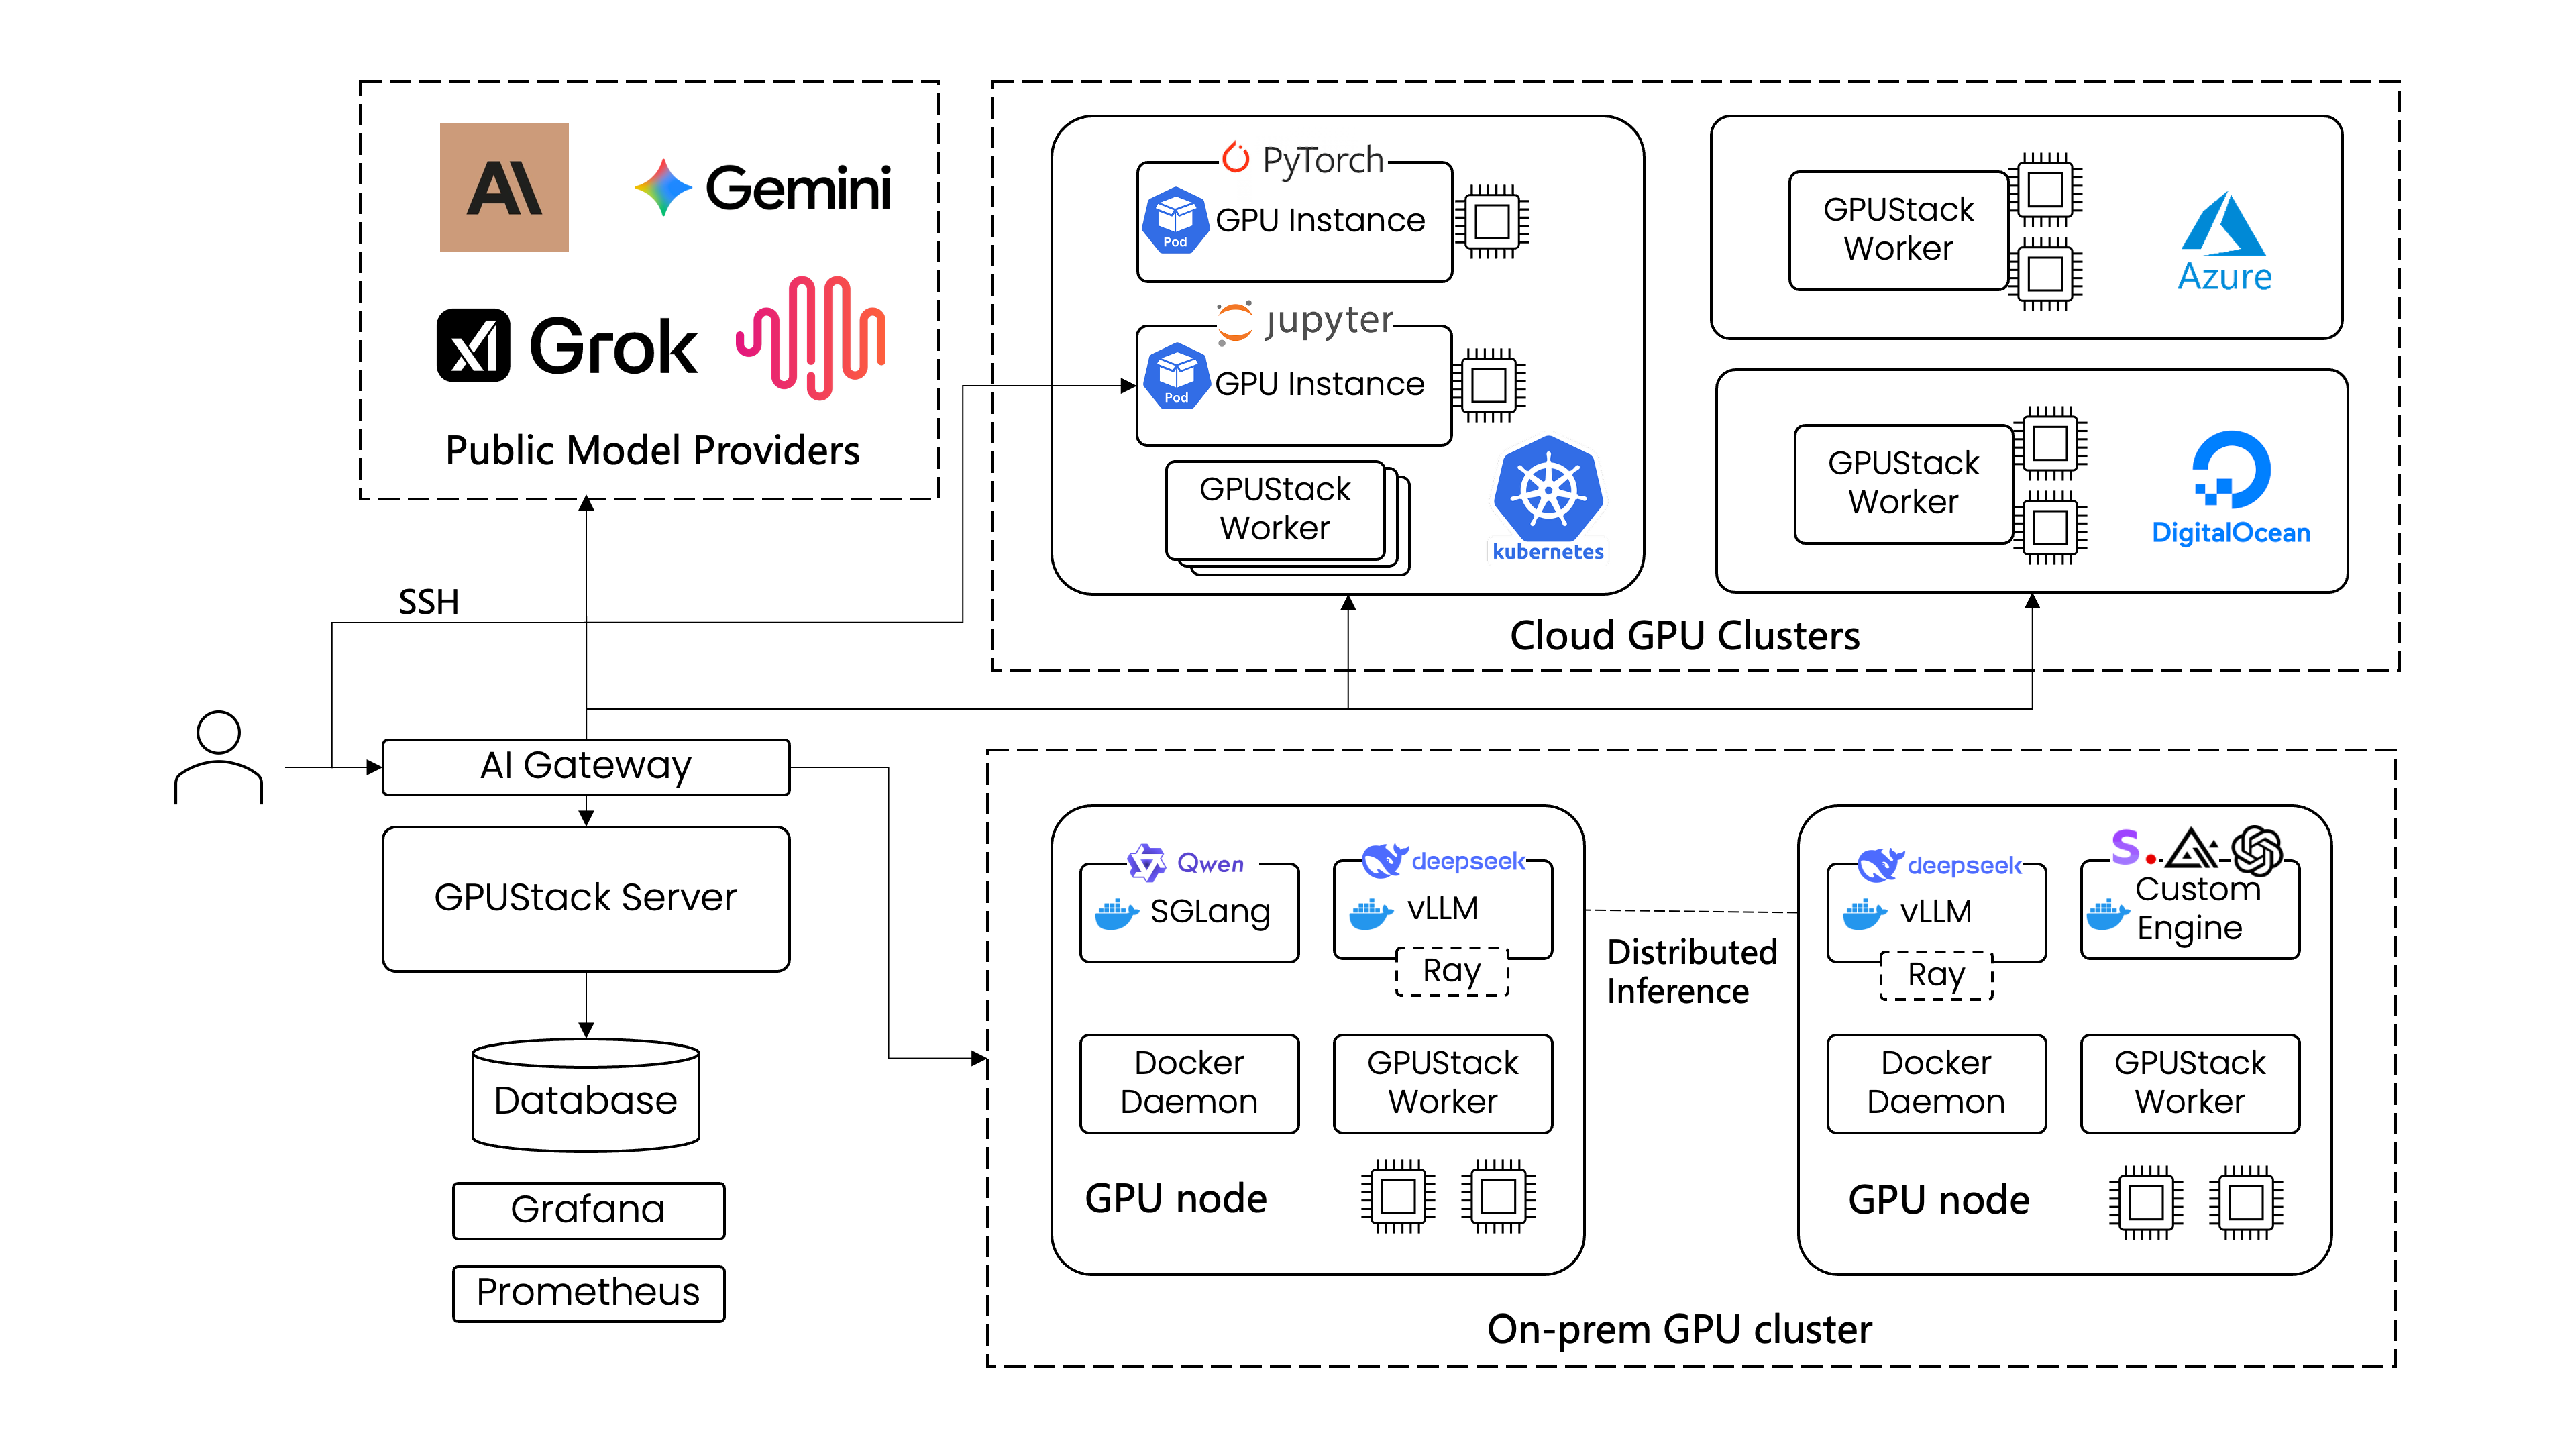
The figure below illustrates how a single GPUStack server can manage multiple GPU clusters across both on-premises and cloud environments. The GPUStack scheduler allocates GPUs to maximize resource utilization and selects the appropriate inference engines for optimal performance. Administrators also gain full visibility into system health and metrics through integrated Grafana and Prometheus dashboards.
Cluster Visibility at a Glance
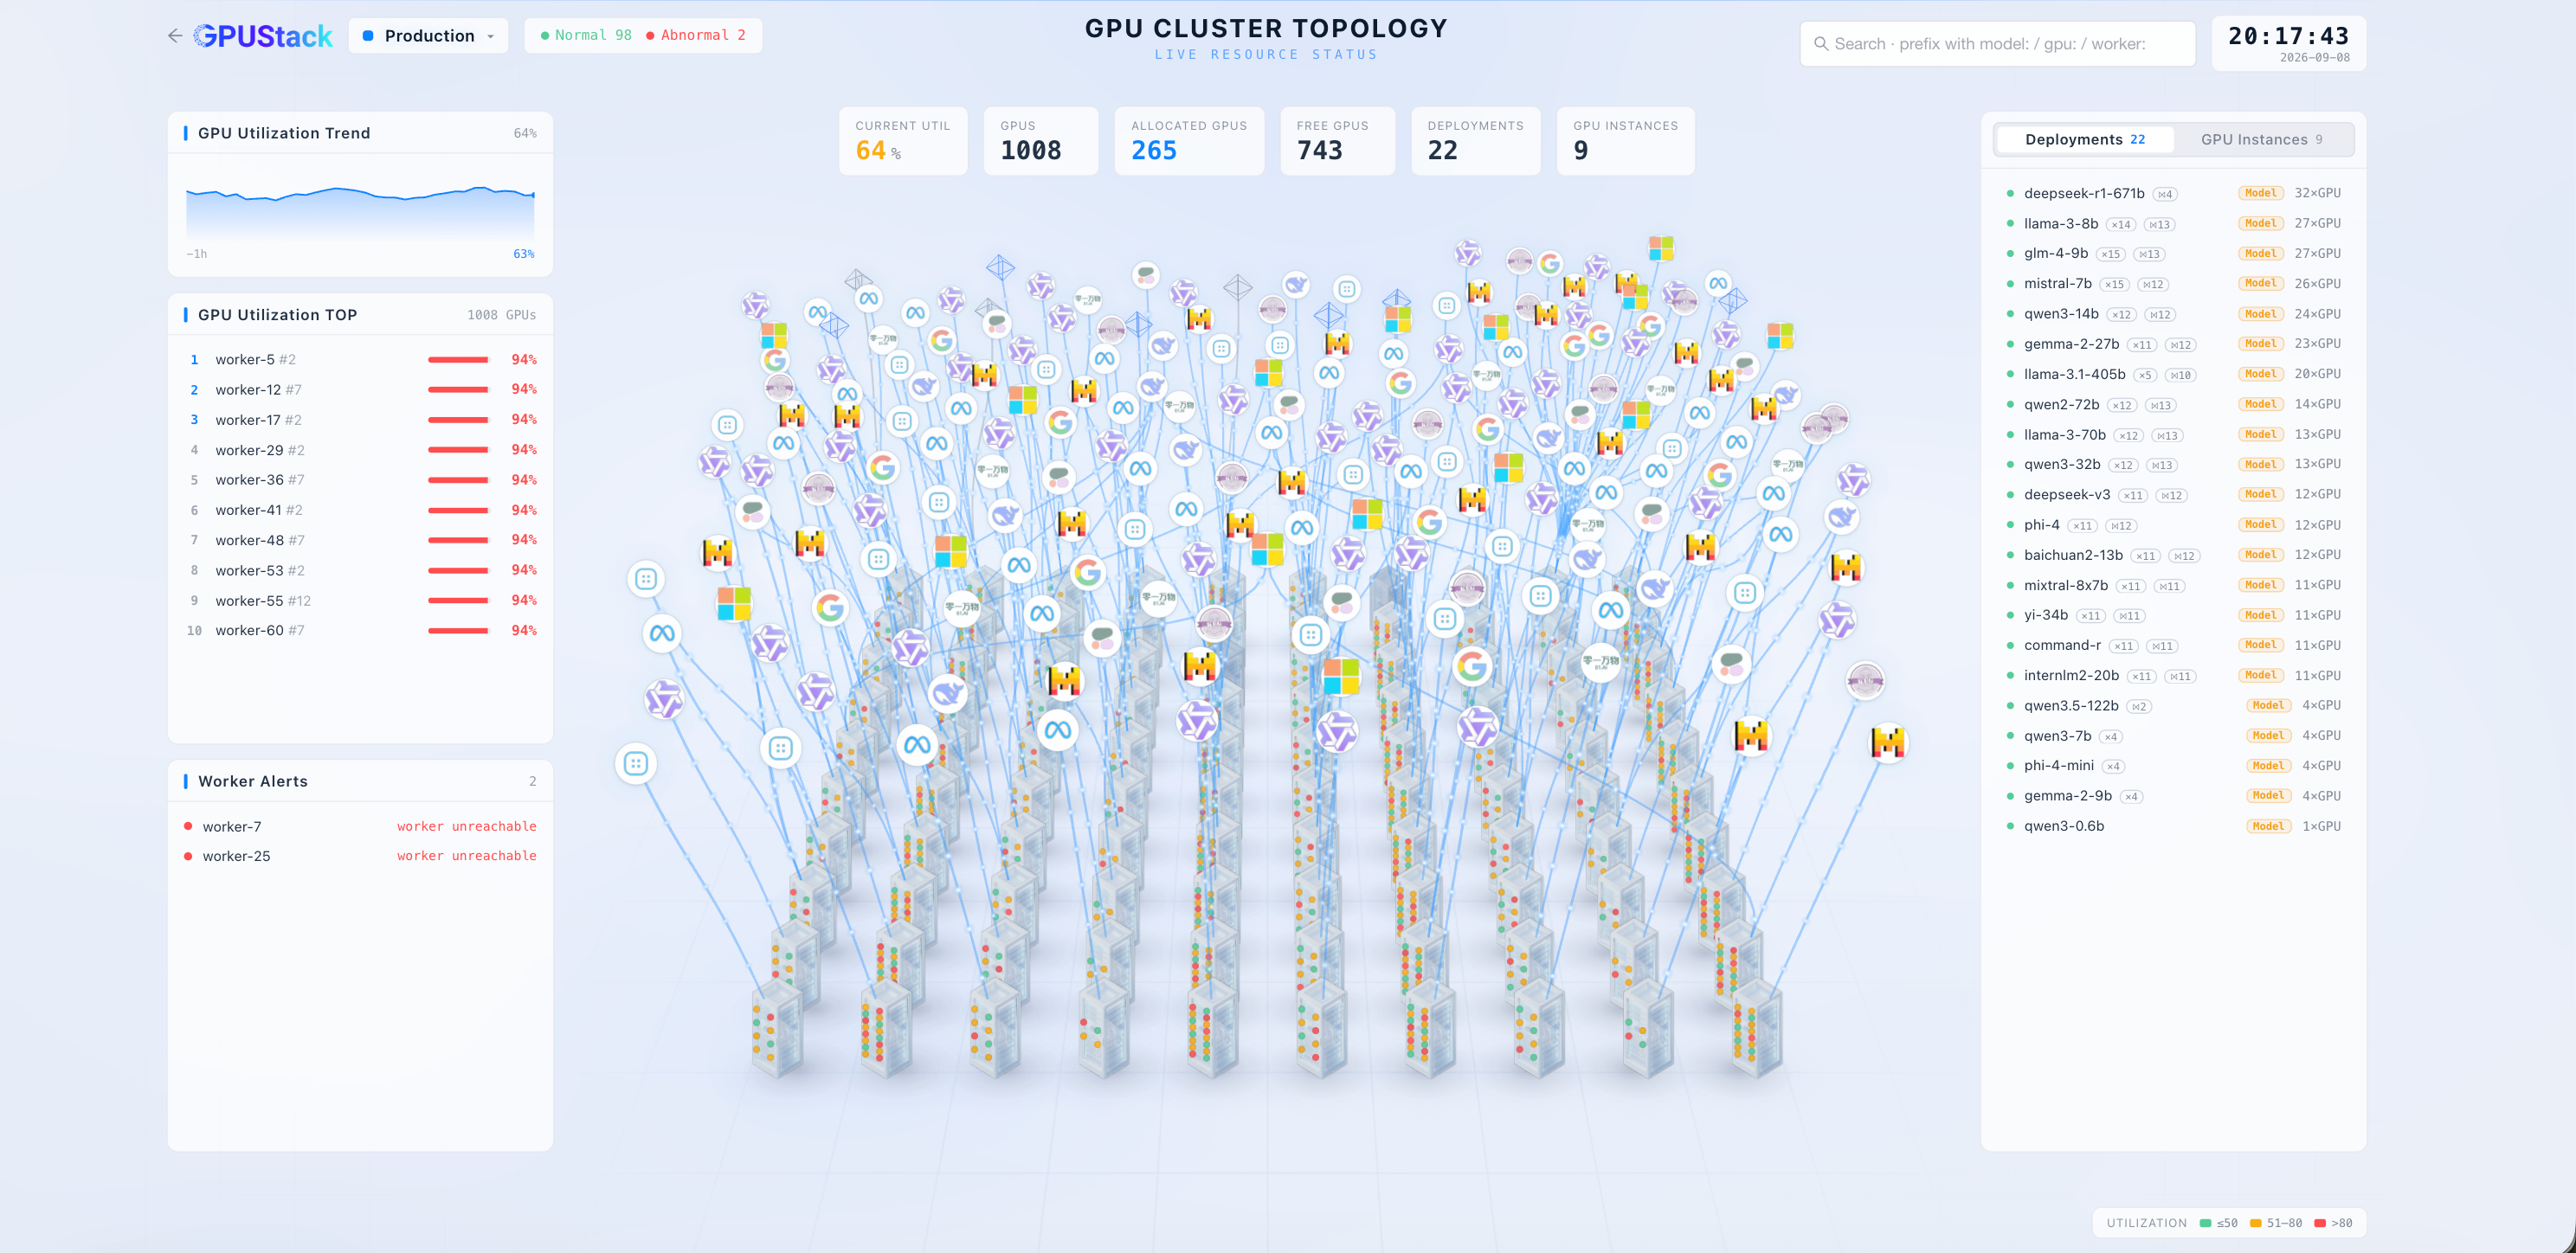
The GPU Cluster Topology view in GPUStack Enterprise provides a live, bird's-eye view of your entire fleet — every worker, GPU, and model deployment in one place, with real-time utilization, allocation, and health status.
Optimized Inference Performance
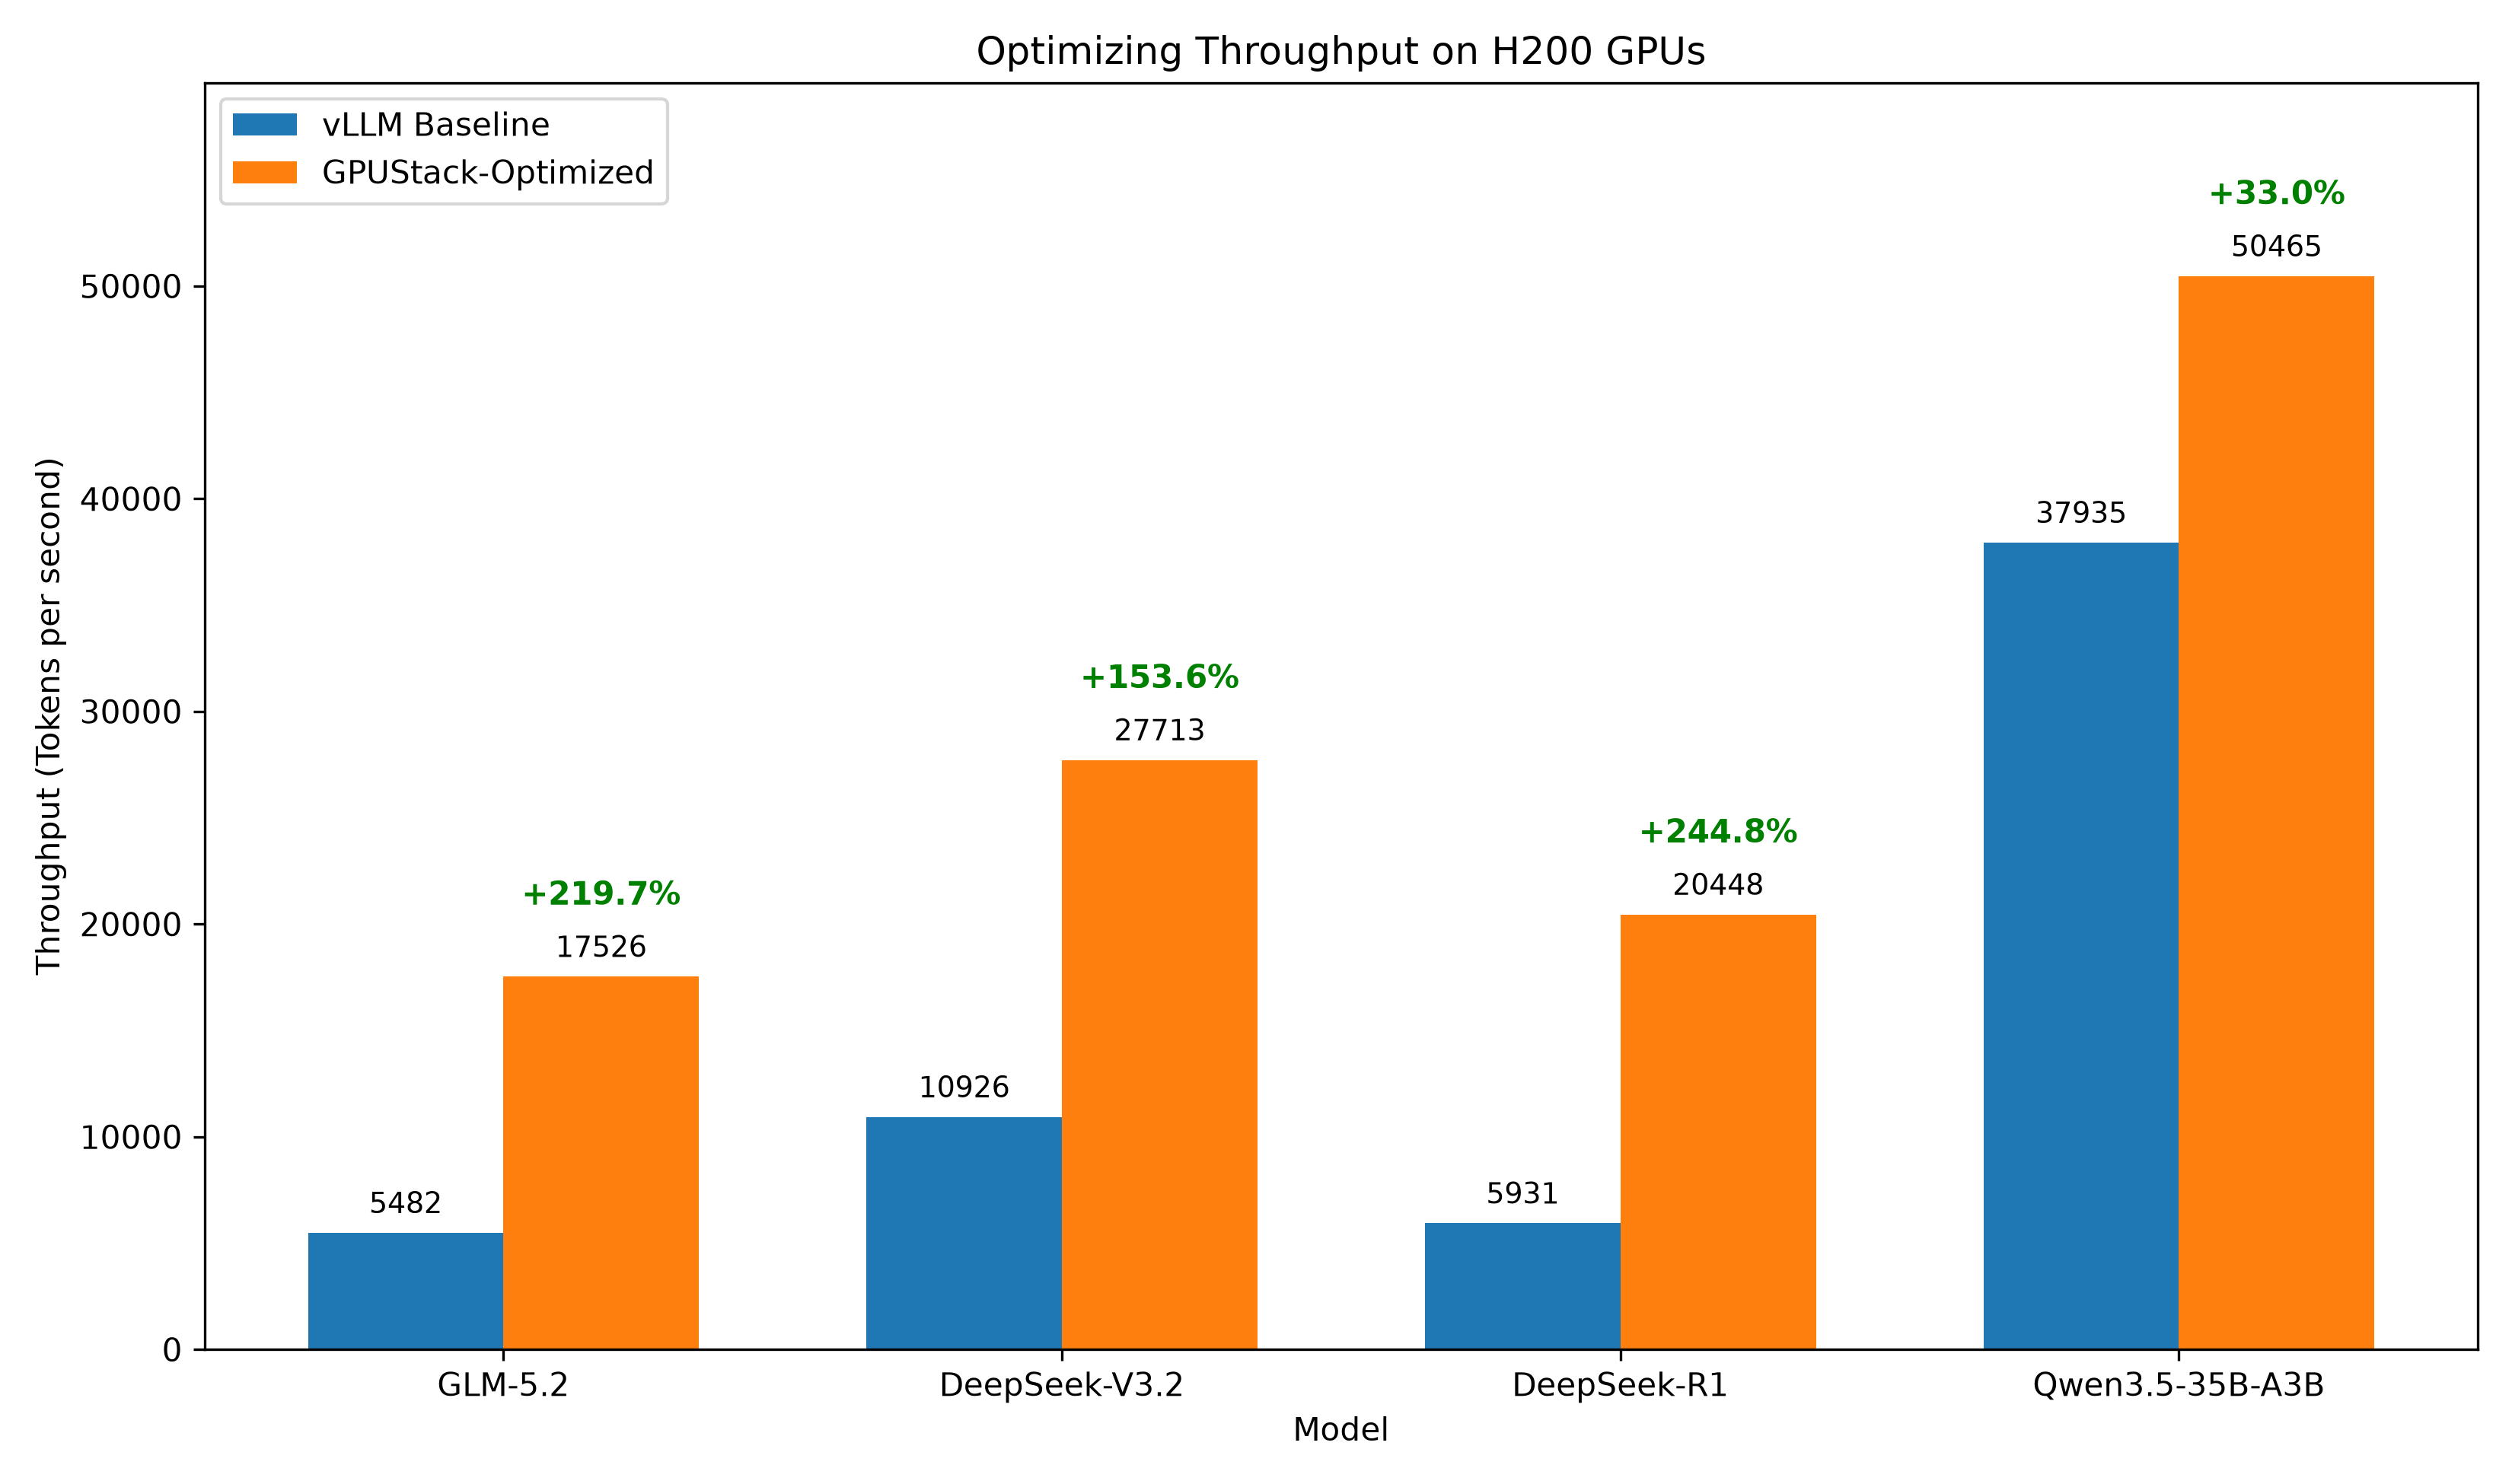
GPUStack's automated engine selection and parameter optimization deliver strong inference performance out of the box. The following figure shows throughput improvements over default vLLM configurations:
For detailed benchmarking methods and results, visit our Inference Performance Lab.
Supported Accelerators
GPUStack supports a wide range of accelerators for AI inference:
For detailed requirements and setup instructions, see the Installation Requirements documentation.